Noam Cohen is a serial entrepreneur building seriously cool data and AI companies since 2018. Noam’s insights are informed by a unique combination of data, product, and AI expertise — with a background that includes winning the Israel Defense Prize for his work in leveraging data to predict terror attacks. As the Head of Artificial Intelligence at Torq, Noam is helping build truly next-gen AI capabilities into Torq’s autonomous SOC platform.
Your analyst tells the AI that the alert is just the red team running a scheduled pen test. They told it the same thing yesterday, and the day before. It works, then it doesn’t, then it does — and that flakiness is harder to live with than a tool that’s simply, predictably wrong.
This is happening in almost every SOC that runs AI triage, and the AI isn’t broken. It just has no memory of its own decisions. It looks at each alert individually, with no idea that your team has already settled this question a dozen times over. Every shift, it starts from scratch.
We tend to file the result under alert fatigue, but that undersells it. The higher cost is what happens to trust. Once analysts stop believing what the AI tells them, they treat it as one more box to click, and the money you spent on AI triage quietly buys you nothing. Earning that trust back is the problem the whole category has to solve next, and it’s the problem the learning layer of the Torq AI SOC Platform was built for.
Where First-Generation AI Triage Stops
The first wave of “AI SOC” tools proved that a large language model can read an alert and produce a credible analysis on day one, with no prior training on your environment. That breakthrough was great (at the time), and the day-one analysis it unlocked is part of the foundation Torq builds on. But it isn’t enough. A capable AI SOC has to keep learning, and the first generation treats day one as the ceiling.
That’s because the trouble starts after day one. The model judges every alert from scratch, and when an analyst corrects it, that correction is added to the prompt rather than the model itself. So the false positive your team carefully explained on Monday comes back looking brand new on Tuesday. Researchers call this self-inconsistency, an inherent failure mode of LLMs. Your analysts call it the reason they stopped trusting the tool.
We reviewed more than 1,000 real analyst corrections across four customer environments to understand why the AI and the analyst kept disagreeing. The reasons split cleanly into two groups.
About half the time, the AI was simply missing context. It flagged an admin who was authorized to do exactly what they did, or a piece of software the team already knew was safe, because nobody had told it who does what inside your walls. That kind of gap has a clear fix, described in the first two posts in our series: the Torq Context Graph and Torq Recall feed that organizational knowledge straight into the model. Together with Reflex, they form the memory and learning layer beneath every agent in the Torq AI SOC Platform.
The other half of disagreements are harder to reconcile, and they’re exactly what Torq Reflex was built for. In these cases, the AI wasn’t missing information. It had access to everything the analyst did, but still landed somewhere the team wouldn’t. Sometimes it contradicted its own earlier verdicts. Other times, it just read a borderline call differently than the team did, treating a contained threat as resolved when the team’s policy was to escalate it anyway, or accepting a thin set of signals as proof when the analysts wanted more. No amount of extra data closes a gap like that, because the gap is about judgment.
Why “Learning AI” From Other Vendors Often Isn’t
Everyone in this space says their AI “learns” now, and they rarely mean the same thing by it. Usually, it comes down to one of two moves: the tool rewrites its own prompt based on your feedback, or it saves your past corrections and pulls up similar ones when a new alert looks familiar. Both are useful. Both run into the same wall.
You can’t prompt your way to consistency. There’s no instruction that makes a model with no memory return the same verdict it gave yesterday; that takes a model that actually remembers what it decided.
Your team’s risk tolerance has the same problem. Something like “we treat blocked executions as malicious” isn’t really a rule. It’s a pattern that only becomes visible once you’ve watched the team rule the same way across a pile of messy edge cases. Calibration works like that, too. Analysts learn how much evidence is enough by being wrong and adjusting, not by being told to relax.
Prompts and lookups can describe your team’s judgment well enough. But they can’t absorb it; they’re limited and inconsistent, and they offer no real confidence in the answer. That’s the line Reflex crosses.
There’s a quieter problem, too: model swapping. As providers upgrade and retire the underlying LLMs, behavior shifts beneath you. Our research shows you have to tune both the prompt and the model, but when the model changes, customer instructions rarely get retuned along with it, which creates more inconsistency and less confidence at the worst possible time. Because Reflex is a stateful model trained on your team’s own calls, it stays resilient to those model changes.
How Torq Reflex Works
The easiest way to picture it is Spotify. Out of the box, Spotify plays music that appeals broadly to everyone: the hits and the editorial playlists. That’s the equivalent of the LLM baseline, and every AI SOC ships with a version of it. Discover Weekly is the part makes Spotify feel personal, built from what you play and what you skip.
Reflex plays the role of Discover Weekly. The general model is the editorial playlist that works for any customer, while Reflex is a model trained on how your team specifically makes decisions, learning more every time an analyst corrects it. It isn’t pulling the nearest past case off a shelf. It’s a classifier that has taken your patterns on board well enough to judge alerts it has never seen before.
Walk an alert through it, and the flow is simple. The alert arrives, and Reflex — a trained language model — assigns the most likely verdict along with a calibrated confidence score. If that confidence is high, its verdict shapes the output. If it isn’t, the full LLM analysis runs, and the case goes to an analyst, just as it would if Reflex weren’t there at all. Whatever the analyst decides flows back in and retrains the model, so each correction is worth a little more than the last.
And because Reflex lives inside the Torq AI SOC Platform, a confident verdict doesn’t just label an alert and stop. It feeds Auto Triage and case creation, and then orchestrates the response from Socrates across Torq HyperAgents™. So the judgment your team teaches Reflex makes every downstream action across the full threat lifecycle more trustworthy.
That confidence number is the advantage of training a model instead of running a search. A lookup can tell you an alert resembles something a human fixed once. Reflex gives you a real, calibrated probability, which is what makes the whole arrangement safe to run. It weighs in when it’s sure and holds its tongue when it isn’t, so it can only help: anything it’s uncertain about goes right back to the pipeline you already trust.
Reflex is a purpose-built language-model design, engineered to learn from a small number of samples and to operate under asymmetric risk, where missing a malicious verdict is far more dangerous than mislabeling a benign one. The same math lets you set your own tolerance for the two kinds of mistakes. Missing a real threat hurts more than chasing a false alarm, so by default, Reflex treats a missed malicious error as the costlier one, and you can dial that weighting to match how your organization actually thinks about risk. It beats typing “THIS IS VERY CRITICAL” into a prompt and hoping the model takes the hint.
What the Data Shows
We ran Reflex against the semantic-similarity approach most “learning” platforms lean on, across those same three environments.
The number we care about most is the performance on alerts where the AI was wrong and a person had to step in. Reflex matched the analyst’s corrected verdict 92% of the time and held within about three points of that across folds. The similarity approach managed 78%. On overall accuracy, the trained model came out roughly 11 points ahead, and on the call that carries the most weight — confirming a real threat — it gained around 22 points over the baseline.
A tight spread means the result isn’t a fluke, and Reflex gets there in roughly two weeks of normal analyst feedback. The early weeks are bumpier while the model finds its feet, then it sharpens with every retraining pass. Most AI triage systems perform exactly the same on day 100 as they did on day one. Reflex draws a curve you can put in front of your board.
What It Means for Your Team
Fewer repeat corrections: Your analysts stop re-teaching lessons that the system should already know. A correction made once carries forward to every alert like it.
Consistency across shifts: The same alert lands on the same verdict, whether it’s a senior analyst at 2pm or a newer one at 3am.
Real confidence scores: You get a calibrated probability instead of hedge language, so high-confidence cases move fast while the genuinely uncertain cases land in front of a person for judgment.
Error trade-offs you control: You decide how much worse a missed threat is than a false alarm, and the model enforces it.
A curve you can measure: The system improves in ways you can actually report on, quarter after quarter.
Built for oversight: The EU AI Act‘s high-risk rules take effect in August 2026. Reflex’s confidence-based routing with a human fallback already aligns with the Act’s oversight and transparency requirements.
Your Data, Your Model
Your model is yours and no one else’s. We don’t pool training data across customers, nor do we share parameters between them. Your red team’s patterns and your policy calls never leave your tenant or quietly shape a competitor’s experience. The model works for you because you’re the one who trained it.
That’s what this series has been building toward. That same data discipline is what makes a genuine human-on-the-loop model possible. Most SOCs run human-in-the-loop out of necessity. An analyst checks the AI on nearly every alert, because there’s no reliable way to know which verdicts to trust.
Reflex changes that calculation because it produces a calibrated confidence score grounded in your team’s own calls, it can act on the cases it’s sure about and send the uncertain ones to a person. Your analysts shift from reviewing everything to supervising the system and stepping in where their judgment actually counts. They stay on the loop, with an auditable record of what the model decided and why.
This is the final piece of our series, Context, Memory, and Learning in the AI SOC: context grounds the agents, memory gives them precedent, and learning teaches them your team’s judgment. Together, they’re the layer that makes an autonomous AI SOC something you can actually trust.
When Anthropic unveiled Claude Mythos Preview in April 2026, the security industry felt the ground shift. First, in a controlled research environment, Mythos autonomously discovered thousands of previously unknown vulnerabilities spanning every major operating system and web browser, including flaws that had survived decades of expert human review. And perhaps most impactfully, it then developed working exploits, without human guidance, at a rate no team of human researchers could match.
At first, Anthropic withheld Mythos from public release, channeling it instead through Project Glasswing to focus the model’s capabilities on defense. Since then, on June 9, 2026, Anthropic released a public version as Claude Fable 5. Even though the full Mythos 5 model remains restricted, the implications were already clear to security leaders. The economics of finding and exploiting software flaws have collapsed. This capability, in the hands of attackers, has fundamentally altered defenders’ collective calculus.
Manual SOC processes architected in an era that predates agentic AI now teeter on the precipice of obsolescence. The urgency shifts from detection to containment and remediation. Machine-speed threats demand machine-speed response. And SOC practices must be reborn and embrace agentic AI if they are to respond at the pace this new reality demands.
The Economics Collapsed. You Know This. So Do Attackers.
Claude Mythos is remarkable not only for its detection capability, but also, and especially, what that capability means in the wrong hands. We want to be clear: this is not fear-mongering. It is a call to action.
Historically, sophisticated cyberattacks required sophisticated attackers. Identifying a zero-day vulnerability in a major browser, chaining it with a privilege-escalation flaw, and building a working exploit required years of experience, deep technical knowledge, and significant time. That barrier kept the most dangerous attacks in the hands of nation-state actors and elite criminal groups.
Mythos obliterates that barrier. Detection is now commoditized.
Security analysts have characterized it plainly: tasks that once required specialist skills (ie, writing exploit code, understanding system architecture, using advanced attack tooling) can increasingly be automated using AI. What once separated a script kiddie from an elite threat actor was expertise. Mythos-class AI can supply that expertise on demand.
The AI-augmented low-skill attacker is born. Someone with minimal technical background can now point a capable AI at a target, receive a map of exploitable vulnerabilities, and get working attack code in return. What once took a nation-state months can now take an amateur hours. One security researcher put it starkly: handing a similarly capable model to bad actors would be “like giving script kiddies a nuclear weapon.”
We think that analogy appropriately frames the urgency. The democratization of exploitation capability is unfolding before our eyes in real time. We are asking you to break the glass and give this the attention it deserves. Now.
Manual SOC Practices Are Already Obsolete
The traditional Security Operations Center was built for a different threat landscape. Analysts triaged alerts manually, investigated incidents by hand, and escalated through human decision chains. Even as SIEM and SOAR tools added automation, the core model remained human-paced: see, think, act.
That model cannot survive in a world shaped by Mythos-class adversaries.
When attackers can generate targeted, sophisticated exploits at machine speed, the attack chain evolves faster than any human-centric operation can run. Vulnerabilities are identified, weaponized, and exploited in cycles measured in hours, perhaps even minutes, but certainly not weeks. The attacker’s tempo has permanently outpaced manual response.
The consequences are predictable: alert fatigue intensifies as detection volume spikes, critical signals get buried in noise, and analysts face an impossible triage workload. The attackers overwhelm the defenders. Triage becomes the bottleneck at exactly the moment that speed matters most.
Enterprise defenders have no choice but to adapt. The organizations that recognize this shift and act now to restructure their operations amidst this new normal will be the ones that contain Mythos-era attacks. Those who don’t will find themselves perpetually responding to breaches they could not prevent.
The Bottleneck Has Moved
Detection is no longer the hard part.
Modern threat detection has matured considerably. EDR, NDR, SIEM, and cloud security tools collectively generate enormous signal fidelity. Seeing a threat does not mean automatically neutralizing it. The bottleneck has shifted from detection to response action.
An alert fires. A SOC Analyst pulls context from five different tools, assesses scope and severity, and decides on containment. They document the recommended response action and initiate communication and coordination with the security control owner. All of this, to say nothing about whether they chose the alert that represents the greatest threat to the enterprise. Because let’s face it, the threat needle resides in an alert haystack. Maybe multiple haystacks. Meanwhile, the attacker has pivoted, moving laterally and establishing persistence. More alerts, more noise, more pressure.
Even for experienced analysts, response time falls off the adversary’s pace set by an automated, focused attack moving at machine speed. The detection sensor is not the SOC’s critical constraint; the gap between detection and action most certainly is.
If the attacker is operating at machine speed, the defender must too. Easier said than done? Perhaps not as difficult as you imagine. Stay with me.
Machine-speed response does not mean removing humans from the loop entirely. Nor does it mean turning the keys entirely over to AI. It does mean restructuring operations so that humans provide critical oversight, define guardrails, and review high-stakes actions, while AI handles the high-volume, time-sensitive work that comprises a large share of security operations.
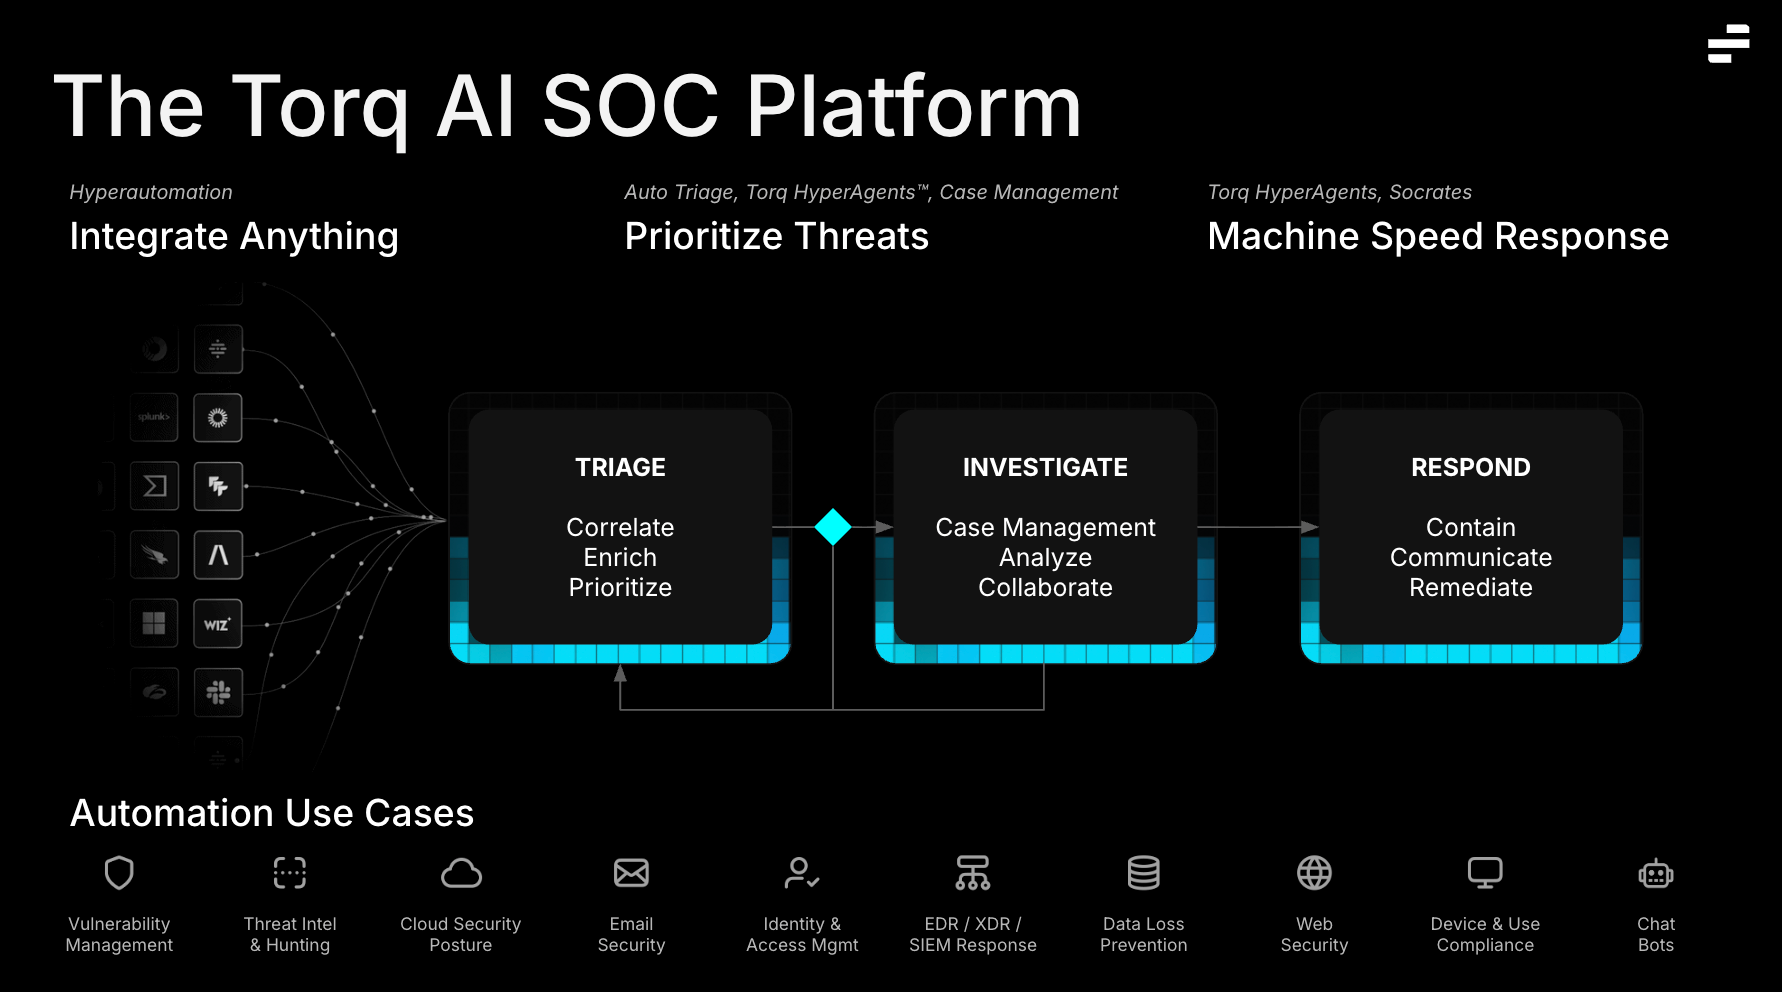
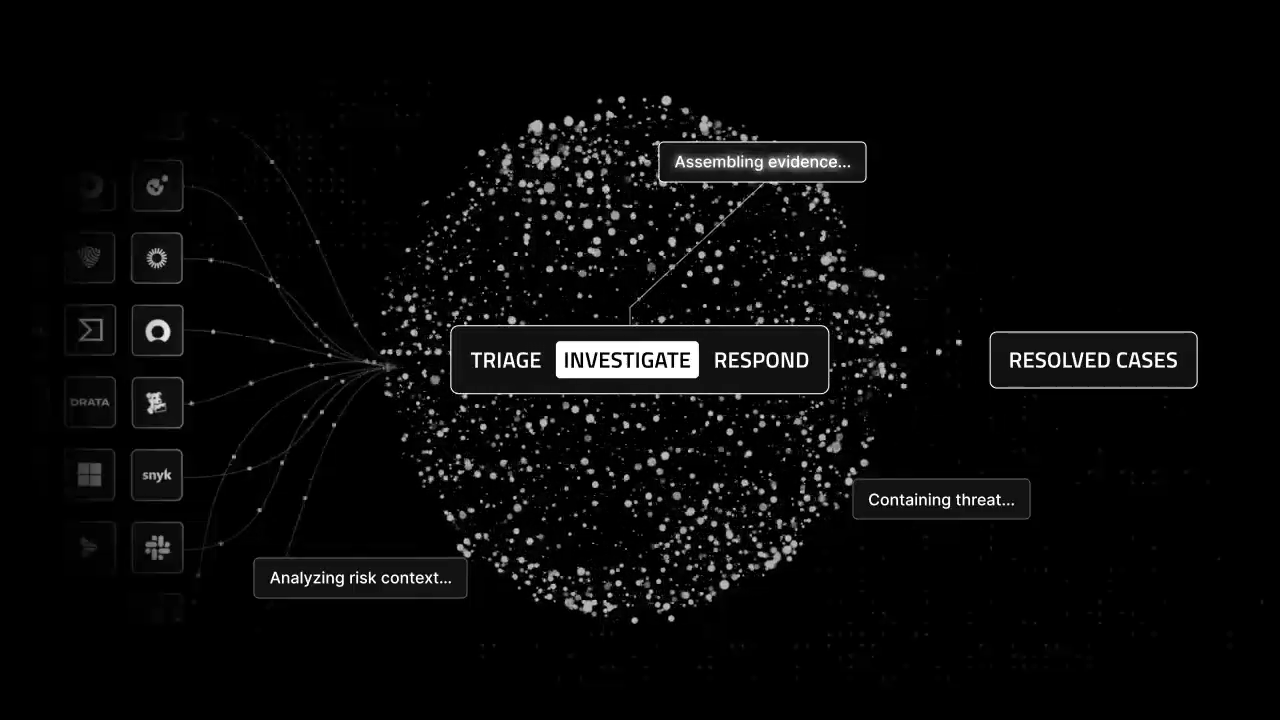
Agentic AI makes this new SOC architecture possible. Hence the term, “AI SOC.” Unlike traditional automation, which executes static playbooks, agentic AI reasons through novel situations, plans multi-step response actions, and executes across integrated systems without requiring human intervention at every step. It can triage an alert, enrich it with threat intelligence, correlate it against historical activity, determine the appropriate response, and execute containment — in seconds, at any hour, across unlimited concurrent incidents.
In a post-Mythos world, the most successful SecOps leaders will (1) structure their operations to use agentic AI to augment their human staff, (2) combine agentic AI and automation to slash MTTR, (3) balance agentic and deterministic automation for economic investment horizon optimization, and (4) build trust in agentically augmented systems through strategic scoping and small wins that build momentum.
How Torq Helps: The AI SOC Platform Built for This Moment
Torq built its AI SOC Platform for exactly the threat environment that Mythos crystallized. Recognized by Gartner® as the Company to Beat in AI SOC Agents for Threat Investigation (May 2026), Torq’s platform is purpose-engineered to close the gap between detection and response at the speed this era demands.
Multi-Agent Architecture
The Torq AI SOC Platform runs a multi-agent system (MAS), with Socrates serving as the agentic orchestrator, overseeing specialized AI agents that work in parallel across triage, investigation, containment, and case management. Each agent accesses only the data you specify and takes only the actions you authorize, within the scope you define. All agentic reasoning and actions are documented, transparent, and auditable.
Autonomous Triage
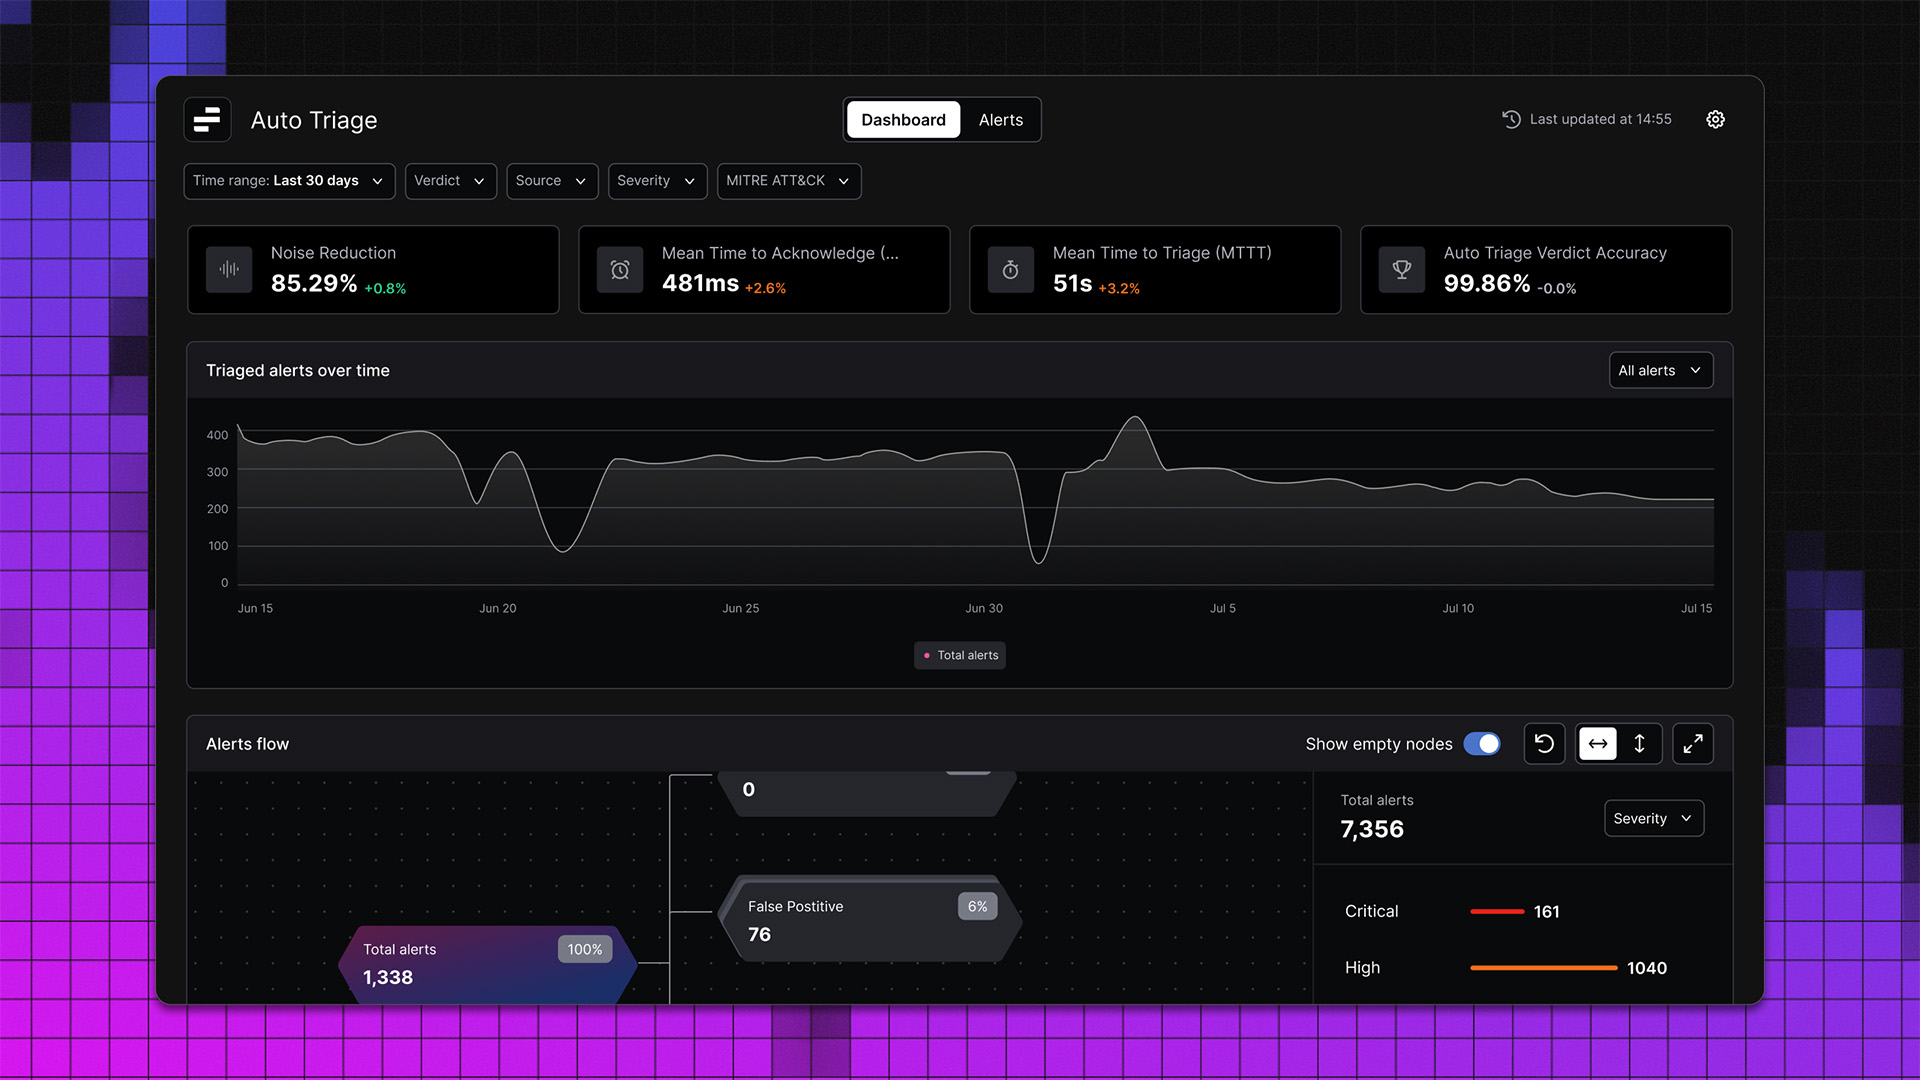
Torq Auto Triage is the agentic engine that stops noise before it floods your SOC. Auto Triage is fully integrated with the Torq AI SOC Platform and your security stack, to (1) ingest, normalize, and analyze telemetry at machine speed, (2) reveal your biggest risks, and (3) automatically open cases for true positives. Torq has some compelling tech under the hood that learns and adapts to how your SOC operates, so our model becomes your model. Where manual triage took 60 minutes, Auto Triage completes in seconds.
Investigation at Machine Speed.
Cases are automatically opened within Torq Case Management. Agentic insights, timelines, and evidentiary artifacts are automatically added to each case, which serves as the single source of truth for analysts and stakeholders. Socrates leads machine-speed investigation, tasking the specialized Torq HyperAgents™ to offload gruntwork from human analysts and get to the recommended course of action quickly, in minutes, not hours.
Autonomous Response with Guardrails
With Torq, autonomous response is a controlled dial, not a binary decision of human or agent. With recommended containment and remediation plans in hand, you decide what level of automation and under what conditions makes the most sense for your enterprise. Start small, build trust, and expand as you go. We have Fortune 500 enterprises using Torq to autonomously handle 100% of Tier 1 incidents. Mean time to respond (MTTR) is reduced by an average of 94% in our enterprise installed base.
Imagine what a 94% improvement in MTTR would mean for your SOC and your enterprise.
Agentic Builder for Continuous Adaptation
As the threat landscape rapidly evolves post-Mythos, Torq’s Agentic Builder enables security teams to translate human natural-language intent into production-grade AI agents and dynamic business logic. Simply, easily. What once took months is now done literally in minutes.
A Fortune 500 Retailer transferred four years of legacy SOAR to the Torq AI SOC Platform in days, freeing time to develop new use cases they never had bandwidth to get to before. Fully operational and deployed in under three weeks.
A Global Hospitality Enterprise ripped out SOAR, upgraded to the Torq AI SOC Platform, and was fully operational and deployed in six weeks.
A Commercial Real Estate Firm realized instantaneous value on Day 1, and now 60% of phishing cases are handled fully autonomously
New attack patterns demand new responses; Agentic Builder makes that adaptation achievable.
The Mythos moment dramatically reduced the barrier to entry to sophisticated attacks, compressed timelines, and raised the volume of what defenders must handle. The Torq AI SOC Platform was built to absorb that pressure, so your analysts can focus on what AI cannot replicate: human judgment, strategy, and context-aware oversight at the edge of the unknown.
The Clock Is Running
Claude Mythos is a preview of the threat environment that is coming. In some ways, this threat environment is already here. Attackers with AI assistance can already find, weaponize, and deploy exploits at a pace that manual SOC operations never anticipated and simply cannot match. The organizations that respond by building agentic defense capabilities that now work alongside their human experts will be significantly better positioned than those waiting for the next incident to prompt action.
The bottleneck has moved from detection to response. The economics of sophisticated attacks have collapsed. The SOC clock is running. The right time to build a machine-speed defense was before Mythos. The second-best time is now.
To learn more about how Torq’s AI SOC Platform can help your team meet the Mythos moment, get a demo.
The manual grind is over: True autonomous security shouldn’t require you to manually tag alerts or write rigid correlation rules just to teach a system how your SOC operates.
Generic RAG fails in the SOC: Standard AI semantic searches hallucinate and match irrelevant data. High-stakes SecOps requires deterministic precision.
Automated institutional memory: Torq Recall transforms an analyst’s everyday workflow — resolving cases and writing notes — into actionable, automated triage precedent.
Honest AI builds trust: In messy, real-world environments, Torq Recall handles conflicting historical data by explicitly flagging discrepancies rather than blindly guessing.
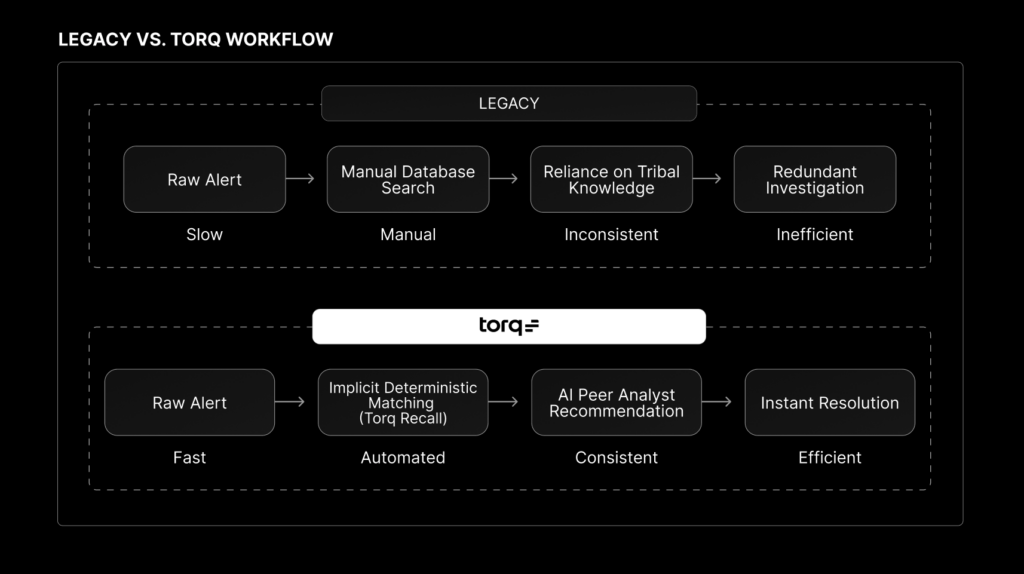
AI SOC memory is the difference between an investigation that starts from your team’s history and one that starts from zero. In most security operations centers, there is none: context disappears the moment a case closes. When a new alert fires, the investigation effectively starts from zero. Analysts are forced to rely on search interfaces — however advanced — to find similar past cases and determine whether an IP, file hash, or domain has been seen before and what the team concluded during the last investigation. But in an agentic SOC, even great search is still manual work; relevant precedent should be retrieved automatically at triage time.
Legacy case management systems weren’t built to retain this operational memory; they were built for tickets. To compensate, these systems require analysts to spend significant time manually gathering and connecting evidence to turn a raw alert into an actionable case. In other words, they demand that the analyst work for the system.
Without an automated way to recall past relevant resolutions, analysts repeatedly reinvestigate the exact same benign patterns the organization has already dismissed, creating the SOC equivalent of déjà vu and wasting valuable time. This inflates false-positive noise, drives alert fatigue, and keeps institutional knowledge siloed — meaning that when a senior analyst leaves, their tribal knowledge walks out the door with them.
True autonomous security requires a completely different architecture. A modern AI-native SOC shouldn’t force teams to change their habits or do extra data entry. Instead, it relies on implicit learning. By turning normal daily workflows — resolving a case and leaving a note — into continuous institutional memory, Torq Recall uses deterministic retrieval to automatically triage future threats based on an organization’s actual history.
The Cost of the Blank Slate
When an analyst investigates an alert without historical context, the problem is not just trivial duplication. The harder problem is recognizing patterns that are tightly connected to the specific user, asset, IP, domain, or behavior involved in the alert. For example, a login anomaly from a suspicious IP may appear risky in isolation, but historical cases may show that the same user and asset repeatedly trigger this pattern after legitimate travel or VPN use, and that the SOC has already validated it as benign.
External threat intelligence — like reputation scores and known IOC databases — is critical for establishing a baseline. But the ultimate context for triaging a new alert is internal: How did your specific organization resolve this exact pattern in the past? Was it tied to a legitimate corporate CDN? Was it an expected admin script?
Without an automated memory of past resolutions, false-positive noise inflates, and analysts burn out from repetitive manual triage.
Why Generic RAG Can’t Survive the SOC
As the industry integrates AI into security operations, Retrieval-Augmented Generation (RAG) has emerged as a popular approach for surfacing historical data. But standard semantic RAG struggles to meet the precision requirements of a modern SOC.
Generic RAG is designed to find semantically similar information. That works well for documents, summaries, and natural language knowledge. It breaks down when the “meaning” resides within security entities such as IP addresses, file hashes, URLs, hostnames, users, assets, or email addresses.
In security, two values can look almost identical and still represent completely different evidence. For example, two hash-like values such as 5jshdh2kfw and 5jshdh2yfw may look semantically close to a model, but in SecOps they are different identifiers and may point to completely different files. A near match is not evidence. In a high-stakes environment, “close enough” can shatter analyst trust.
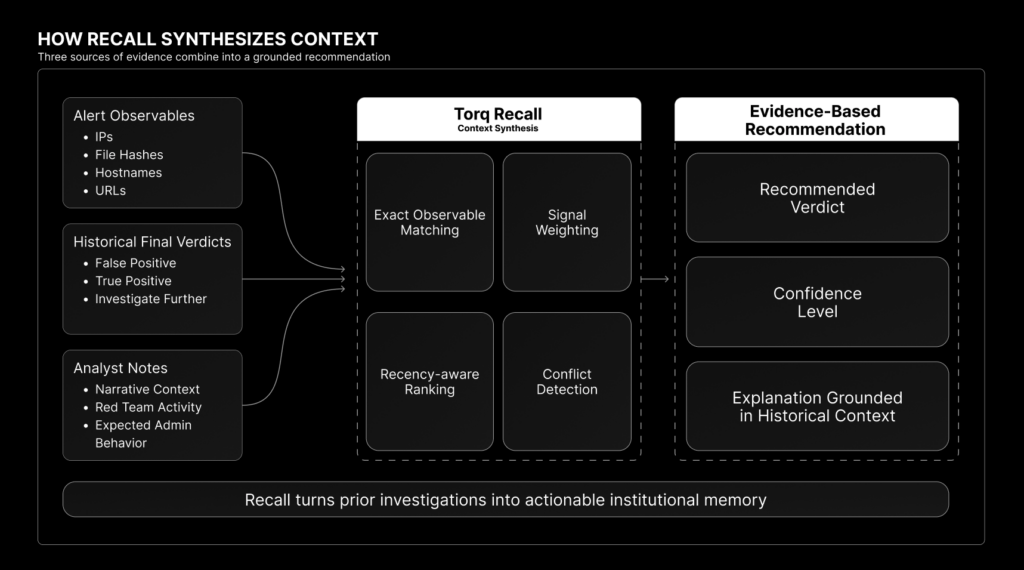
Torq Recall rejects fuzzy precedent matching in favor of Structured Retrieval. Instead of guessing, Recall relies on exact, deterministic overlaps of specific security observables — like IPs, file hashes, URLs, hostnames, or emails — to trigger a historical match. This ensures that every AI-driven triage recommendation is auditable, explainable, and grounded in verifiable evidence from your own environment.
But exact matching is only the first step. Recall also has to understand the signal strength. A match on a rare file hash, unique URL, or unusual email address can carry strong precedent. A match on a common binary like explorer.exe, or a widely shared corporate IP is much weaker. Torq Recall is designed to focus the AI on the security entities that actually matter — not just the ones that happen to overlap.
Deterministic Context Matching: Unlocking the Goldmine
Resolved cases are the raw material for AI SOC memory — the operational record of how your team actually works. Instead of leaving this context buried in closed tickets, Torq Recall seamlessly connects today’s raw alerts with yesterday’s finalized human reasoning.
When a new alert hits, Recall instantly searches your environment’s case history for relevant precedent. It does not treat every historical match equally: cases are prioritized based on exact observable overlap, signal strength, and recency. Because security environments change quickly, Recall applies a time-aware decay factor, allowing fresh resolutions to carry more weight while still preserving older institutional knowledge when the evidence is strong.
Crucially, Recall doesn’t just count past alerts; it analyzes the final resolution decision and the analyst notes.
AI in the Trenches: Handling SOC Chaos
In a real SOC, the data is rarely clean. Alerts arrive with partial context, telemetry is noisy, and human decisions are not consistently captured. Two similar cases may receive different labels, or the analyst’s notes may tell a more nuanced story than the final resolution field. If an AI system is designed in a sterile lab under the assumption of perfect data hygiene, it will inevitably fail when it encounters real-world ambiguity.
Torq Recall was designed not just to find historical matches, but to critically evaluate the quality and consistency of that precedent. Using rigorous LLM-in-the-loop stress testing, the AI was trained on curated case histories that mimic the messiest edge cases in a live SOC.
The guiding design principle was to build an “honest AI” that exhibits calibrated confidence. Instead of blindly forcing a recommendation when data is sparse or contradictory, Recall includes a subagent architecture that is instructed to act like a veteran analyst: it weighs the evidence, spots inconsistencies, and knows exactly when to ask questions.
The system gracefully manages real-world SOC chaos by identifying and adapting to complex scenarios like the ones below.
Real-World SOC Scenario
What was Encountered
How Torq Recall Handles It
Conflicting Precedent
Half of the historical alerts were closed as False Positives, while the other half were escalated as True Positives
Refuses to pick arbitrarily. Recall lowers its confidence score, explicitly flags the split precedent, and recommends the team “Investigate Further”
Misleading Labels (e.g., Red Team)
A past case is labeled “True Positive/Malicious,” but the analyst notes state: “Update: Part of a concluded red team exercise”
Prioritizes the narrative context in the notes over the static resolution label, recognizing that the threat is no longer active, and adjusts its recommendation accordingly
Severity Mismatches
Historical cases sharing an IP address were Critical-severity attacks, but the new alert is a Low-severity informational event
Highlights the severity mismatch as a key difference, ensuring it does not blindly inherit the escalation precedent of a completely different attack type
Weak Signal Overlap
The system finds a match, but it relies on a single, low-fidelity observable (such as a common corporate IP address)
Openly acknowledges the weak precedent, returns a “Low Confidence” assessment, and refuses to force a definitive recommendation
Inconsistent Data Entry
An alert is coded with a “False Positive” reason, but the detailed resolution notes describe actively blocking malicious activity
Flags the contradiction between the label and the details, lowering confidence to prevent the SOC from trusting bad data
To make this behavior reliable, we built a comprehensive testing and evaluation suite based on real-world data, including conflicting precedents, misleading labels, weak observable overlap, severity mismatches, and inconsistent analyst notes.
Recall is evaluated against these scenarios to ensure it surfaces discrepancies transparently instead of hiding them behind a black-box verdict. When the AI is honest about uncertainty and catches inconsistencies in past documentation, it builds the kind of trust analysts need before relying on automated triage.
From Tribal Knowledge to Institutional Memory
Letting the intelligence of your security team disappear the moment a ticket is closed is an architectural flaw that modern SOCs can no longer afford. Torq Recall fixes this by capturing analyst expertise implicitly, turning it into durable AI SOC memory without adding a single click to the workflow.
But this is just the foundational layer of institutional memory. We are currently expanding Recall’s contextual reach beyond closed cases. By integrating directly with the Torq data fabric, the system is evolving to capture deeper organizational context and fetch richer historical signals directly from your alerts. For an AI-native SOC, more context directly translates to better triage quality: the broader the historical data pool, the more precise and reliable the AI’s precedent matching becomes.
Ultimately, this continuous learning layer is being integrated across Torq’s wider product ecosystem, including Socrates — our AI SOC orchestrator. Building a resilient SOC doesn’t mean writing more rigid rules; it means deploying an AI teammate that seamlessly learns from every resolution your team makes.
Torq Recall is one piece of a larger body of work on how we build trustworthy, agentic AI for security operations. Our series on Context, Memory, and Learning in the AI SOC breaks down the architecture, testing methods, and design decisions behind the AI SOC.
Rony Fluk is a Senior AI Engineer at Torq, focused on building AI-native capabilities for modern security operations. He brings deep experience in LLM systems, automation, and agentic AI, designing deterministic, context-aware automation that helps SOC teams preserve institutional knowledge and make faster, more reliable decisions.
Noam Cohen is a serial entrepreneur building seriously cool data and AI companies since 2018. Noam’s insights are informed by a unique combination of data, product, and AI expertise — with a background that includes winning the Israel Defense Prize for his work in leveraging data to predict terror attacks. As the Head of Artificial Intelligence at Torq, Noam is helping build truly next-gen AI capabilities into Torq’s autonomous SOC platform.
The first half of 2026 is coming to a close. And unless you live under a rock, there is only one takeaway: The AI SOC revolution is here, and Torq is winning.
It started in January 2026: Torq secured our $140 million Series D, led by Merlin Ventures, with every single one of our existing investors doubling down, launching Torq into unicorn status at $1.2 billion and fueling the future of the agentic SOC.
Shortly after, Forbes said Torq is the “de facto leader of the AI SOC space,” noting that while the AI SOC boom is real, the work here at Torq started long before the buzz.
In March 2026, Torq became the Cursor of Security Operations, with agentic building capabilities that turn human intent into production-grade AI Agents in minutes, capable of handling triage, investigation, and response across every security solution in the SOC. This was a game-changer for CISOs and SOC leaders looking for a quick-start button for their AI SOC initiative.
It’s no surprise that the AI SOC space is moving fast, but it’s clear that Torq is leading the pack. So let’s talk about why and how.
The AI SOC Land Grab
The threat landscape is massively different than it was two years ago, heck, even six months ago. Attackers are using AI to develop and deploy the most convincing attacks ever seen, at a lower cost than ever before, and with a lower technical barrier to entry. According to CrowdStrike’s 2026 Global Threat Report, AI has enabled the bad guys to ramp attacks 89% year over year, with the fastest break-in they tracked taking only 27 seconds. What used to take months to build now takes hours.
Human-speed defense is no longer the answer to machine-speed attacks, and the market understood that. The problem is, the market overcorrected. Every vendor with an AI chatbot or a triage-only point solution wrapped their website in AI SOC messaging.
To start 2026, roughly 60 vendors claimed to be “AI SOC”; now there are over 100. We’ve seen the confusion firsthand, with different analyst firms defining the space in completely different ways. But the ones who spend the time to do the research — Gartner, KuppingerCole, and more — are reporting a consistent through line: end-to-end threat management, deep integrations across the entire security portfolio, and enterprise scalability.
Some influencers even claim the AI SOC market is already commoditized; we completely disagree. That’s a convenient argument if your product is triage-only, because that space is crowded and there’s no sign of growth slowing any time soon. The space is not commoditized; it’s fragmented. Broken up by hundreds of vendors calling different tools by the same name, leading to SOC teams making purchase decisions they will regret in six months when they realize agentic triage and an AI SOC platform are not one and the same, and defining it as such only works if you believe triage is all the SOC ever needs to do. But as we know, the work doesn’t end there.
Triage-Gate: The AI SOC Definition Rendition
Let’s be specific about what triage-only tools do and don’t do.
Triage does one thing: it prioritizes risk. It tells you which alerts are real and which aren’t, ranks them by severity, and recommends what should happen next. It doesn’t matter if you work in a Fortune 100 enterprise security operations center, or work in the front of an Emergency Room at the hospital. Triage, by definition, remains the same. Who is bleeding out and needs immediate emergency medical intervention? Who is more benign and can be handled with a simple automated email quarantine, followed by an IP address added to the company block list?
Here’s what triage doesn’t do: It doesn’t investigate a threat. It doesn’t contain it. It doesn’t remediate it. It doesn’t close the case. It simply analyzes the risk, reaches a conclusion, hands a to-do list to a human analyst, and then it’s done.
That means triage-only AI still ends with a human opening a ticket at the start of the actual security work. The investigation is still happening manually, and the evidence is gathered by hand, across disparate tools and queries. The response action requires an incident responder to log into a separate platform and make the necessary calls.
That is, by no means to say that AI alert triage isn’t valuable. In fact, alert volume has become so unmanageable in modern SecOps that, in Torq’s 2026 AI SOC Leadership Report, 97% of respondents reported confidence in AI’s ability to address the problem. However, from that same report:
37% are actually using AI for triage
90% reported challenges with AI Triage
80% rely on multiple point-specific tools
80% say this creates operational complexity
And therein lies the problem. The queue is prioritized, sure, but the SOC is still functioning at human speed. The bottleneck has moved. The enterprise remains exposed. The attackers still have the upper hand.
Torq Auto Triage: Going Beyond Analysis
This is not a knock on triage as a function; it’s a knock on calling it an AI SOC when the job isn’t finished. Torq Auto Triage is a key function of the Torq AI SOC Platform. Our customers leveraging Torq Auto Triage report 60x improvement in triage velocity, a mean-time-to-triage (MTTT) of 45 seconds, at a 97% reduction in EDR noise alone — with ruthless accuracy across hundreds of thousands of alerts per week in some of the largest Fortune 500 companies in the world.
Torq Auto Triage is the agentic engine that applies business context, threat intelligence, and historical case knowledge to deliver verdicts, suppress noise across your SOC, and prioritize threats that actually matter before they become incidents. Most importantly, however, Torq Auto Triage is fully integrated into the entire Torq AI SOC Platform, which then takes the baton through deeper investigation, containment, and remediation actions — all while continuously improving accuracy by grounding every decision in the Torq Context Graph.
A true AI SOC has to do everything a SOC does — not triage only, but manage the complete threat lifecycle from alert through resolution. That means triage, investigation, response, and case closure. And that is the difference.
Torq’s deep-rooted history in agentic SecOps and automation means we are not only capable of triaging the alerts firing from every corner of your SOC, but investigating and responding to threats across every security tool you integrate into the platform.
The complete security stack, the complete threat lifecycle, the complete AI SOC Platform.
The AI SOC Bar Should Be Higher
The AI SOC market is crowded, and it’s only getting louder with new vendors emerging from stealth mode what seems like every day. Most of them solve the narrow problem of triage, leveraging AI to ingest alerts, enrich them with threat intelligence, and surface a verdict to the awaiting human team. Others are beginning to add threat hunting capabilities to the mix, not because it’s the logical next step, but because it’s the only remaining SOC function that doesn’t require them to crack the code on taking action.
That should be table stakes. The bar needs to be higher. And Torq is setting it.
The questions SOC teams need to ask are:
Once you’ve triaged the alert and surfaced the risk, what happens next?
Who handles the investigation?
Does the AI agent contain the threat and stop the spread before wasting more valuable exposure time escalating the proposed response plan to the analyst?
Can the platform automatically remediate the Tier 1 and Tier 2 threats that don’t require human intervention?
Does it integrate with the security stack your team has already built to ensure complete visibility into every possible IOC?
Does it learn from, and remember, analyst exceptions, escalations and deviations from SOP so its verdicts aren’t based on last month’s playbooks, before the next VoidLink-level AI-generated threat changes everything about how your SOC operates?
If the answer stops at “we surface the risk,” then that is a useful tool, but it’s not an AI SOC.
Per our 2026 research, 92% of security leaders cite at least one factor actively reducing their trust in AI in the SOC today. Black-box reasoning was the number-one concern for SOC directors specifically. An AI that hands you a verdict without showing its work doesn’t solve the trust problem; it defers it until the first false positive blows up a production system at 2am. Deploying agentic AI without the right guardrails is its own category of risk.
What a Real AI SOC Platform Looks Like
The Torq AI SOC Platform runs the complete end-to-end threat lifecycle, and fast. At Carvana, Torq handles 100% of Tier 1 security alerts. A global biotech enterprise recently reported a 97% noise reduction in EDR alert triage and a 92% decrease in mean-time-to-resolve (MTTR) from the full Torq AI SOC Platform, in just their first quarter, leveraging the platform.
Torq Agentic AI handles 100% of Tier 1 security alerts.
Carvana
In the first quarter, Torq delivered a 97% noise reduction in EDR alert triage and a 92% decrease in MTTR.
Global Biotech Enterprise
These are real stories, across real enterprise customers, and they don’t stop there. Torq processes more than 1 billion automated actions across our customer base each week, including Chipotle, LEGO, Marriott, Scotts, Siemens, Valvoline, and Virgin Atlantic.
When Gartner named Torq the Company to Beat in AI SOC Agents for Threat Investigation in May 2026, they mentioned Torq’s “combination of deterministic and agentic reasoning, multi-agent system, and model context protocol integration makes it the pacesetter in AI SOC agents for threat investigations.” 1
Here’s how it works:
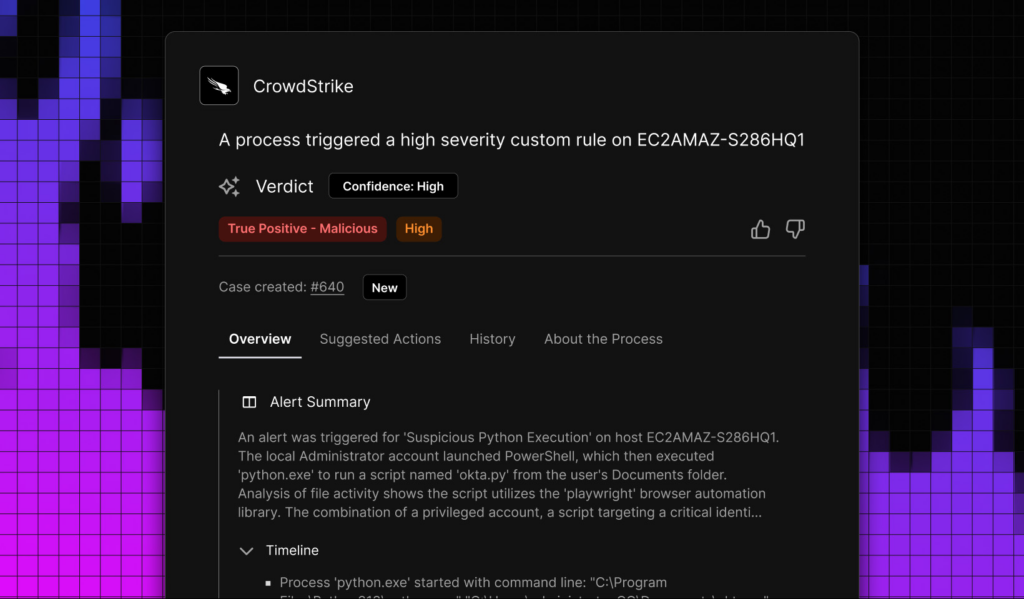
Torq Auto Triage handles ingestion and prioritization, normalizes alerts to the Open Cybersecurity Schema Framework (OCSF), enriches every alert with commercial and OSINT threat intelligence, plus your own organizational context, and applies agentic reasoning to separate real risk from noise. Verdicts come with MITRE ATT&CK® mapping, severity scoring, and full transparency into how the conclusion was reached. True positives don’t generate a recommendation; they automatically become cases in Torq Case Management, with context already assembled and next steps already queued.
From there, Torq SocratesTM, the core orchestrator of the Torq AI SOC Platform, takes over. Socrates plans and coordinates specialized Torq HyperAgents™ that investigate cases, gather evidence, build timelines, and document their reasoning in real time. SecOps engineers simply describe what they need in plain language, and Socrates agentically builds these production-ready AI agents in minutes.
None of this works without the deep integration of Torq HyperautomationTM, and this is where the breadth matters. Torq has over 400+ pre-built integrations across EDR, IAM, SIEM, Network, Email, Cloud, and more. Creating a new integration point to feed alerts into the Torq AI SOC Platform is simple with Socrates’ agentic builder capabilities. Whether a use case is common or completely custom, the platform can handle it — and building new automated security actions no longer requires weeks of engineering work. Bottom line, your existing security stack stays.
With the platform configured and the triage verdicts rolling in, Socrates orchestrates the whole operation, managing case handoffs, executing response actions, and closing cases when the work is done. Over 90% of cases close completely autonomously, while the analysts focus on what actually needs human judgment.
Finally, the Torq Context Graph and memory layer powers every agentic decision in a live, continuously updated model of your environment, grounding each verdict in your environment’s truth and your analysts’ past judgments.
Two mechanisms power that memory: Recall, which surfaces the most relevant historical case precedents each time a new alert arrives, and Reflex, a per-tenant model, developed by Torq Labs, that trains continuously on your team’s confirmed verdicts and corrections. This means every Auto Triage verdict, every Torq HyperAgents investigation, and every autonomous Socrates response is based on the same organizational context, improving the decision-making with each alert prioritized and case closed. A single through line, grounding the AI SOC in real context, across the complete SecOps lifecycle.
The Verdict is the Start, Not the Finish
The AI-generated threat landscape that SecOps teams are operating in today is not going to simplify. Attacks will get faster, more convincing, and harder to keep up with. The velocity gap between machine-speed offense and human-speed defense cannot be closed by a tool that prioritizes risk and then hands it back to a human.
You need an AI SOC Platform that goes beyond analysis — triages, investigates, contains, and remediates at machine speed, with complete transparency into every decision. That’s the blueprint 450 security leaders described when asked what a real AI SOC should do, and that’s what the Torq AI SOC Platform delivers.
Triage gets you to the starting line, but what wins the race is everything that comes after it.
See the full threat lifecycle in action. Get a demo.
1 Gartner, AI Vendor Race: Torq Is the Company to Beat in AI SOC Agents for Threat Investigation (Document ID: G00855833)
Gartner, AI Vendor Race: Torq Is the Company to Beat in AI SOC Agents for Threat Investigation, Tom Powledge, Matt Milone, 25 May 2026.
GARTNER is a registered trademark and service mark of Gartner, Inc. and/or its affiliates in the U.S. and internationally and is used herein with permission. All rights reserved.
Gartner does not endorse any vendor, product or service depicted in its research publications and does not advise technology users to select only those vendors with the highest ratings or other designation. Gartner research publications consist of the opinions of Gartner’s research organization and should not be construed as statements of fact. Gartner disclaims all warranties, expressed or implied, with respect to this research, including any warranties of merchantability or fitness for a particular purpose.
David Melamed is Head of Emerging Technologies at Torq. He joined through Torq’s acquisition of Jit, which he co-founded and led as CTO since 2020, building agentic security on a production Context Graph. A cloud security veteran with 20+ years of experience, David previously held senior technical roles at Cisco (via the CloudLock acquisition) and MyHeritage.
Key Takeaways
An AI SOC agent is only as good as the picture it reasons from, and in most SOCs that picture is rebuilt from scratch on every alert.
Good grounding is current, traceable, decision-capturing, and isolated per tenant.
Keeping context correct is an engineering discipline: freshness, decisions-as-data, and reading the graph instead of re-querying the stack.
I spent a couple of years at Jit building security agents, and the lesson that stuck wasn’t about the models. It was about what the models stand on.
The SOC’s problem was never a shortage of reasoning. It’s a flood of noise with no shared memory. In the SANS 2025 Detection and Response Survey, 73% of teams named false positives their single biggest detection challenge. The average breach still took 241 days to contain, per IBM’s 2025 Cost of a Data Breach report. Drop a smarter agent into that, and you get faster wrong answers.
That gap is the real story of the agentic SOC, and it’s an engineering problem, not a model one. Everyone now claims their AI agents are “grounded in context”; far fewer can say what that context costs to keep correct. Having built one in production, I can tell you what good looks like — and what it takes to build.
What CISOs Should Demand From the Layer Underneath the Agents
Strip away the vendor language, and good grounding is simple: a living model of your environment that an agent can reason on, and you can audit. Four properties separate the context you can trust from context that quietly goes wrong.
Current, not a snapshot. Context decays: ownership changes, services get decommissioned, exceptions expire. A graph that was right at ingestion is wrong by the next alert. The test isn’t whether the data were fresh when you loaded them; it’s whether they’re true when the decision is made.
Traceable. For any recommendation, the system should show what it knew, when it knew it, and where it knew it. That’s why 90% of leaders in Torq’s 2026 AI SOC Leadership Report said explainable AI decisions matter most.
Decision-capturing, not just topological. That a user connects to a device is inventory. Why your senior analyst closes an alert the SOP says to escalate is judgment, and judgment is what walks out the door when they leave.
Isolated. This layer encodes your most sensitive truth: who’s privileged, what’s exempt, where the gaps are. It has to stay yours.
The field bears this out. Practitioners in that same survey rated generative AI tools their least satisfying category of tooling: adoption is real, trust lags. Yet IBM found that teams using AI and automation extensively had average breaches of $3.62 million, compared with $5.52 million for those that didn’t. Grounded AI pays off; ungrounded AI disappoints.
How Torq Grounds Its Agents in a Context Graph
In the Torq AI SOC Platform, that layer is the Context Graph: a live model of your environment every agent reasons on, not a static store each agent re-derives. Torq’s acquisition of Jit — the team I led — brought in a context graph already running in production, moving Torq from a platform that enriches alerts to one that acts on the full story of a case.
The Context Graph doesn’t just inventory what exists; it encodes what it means. Craig and John have the same laptop, and the same alert fires on both. But Craig is a contractor with read-only marketing access; John is a finance director with access to the M&A data room. Same signal, different verdicts.
The critical part here is the decision layer: every verdict, exception, and SOP deviation is stored as a queryable object, not buried in a case note nobody reads. Run it long enough, and the graph reflects how your SOC actually operates, not the runbook from two years ago.
How the Context Graph Works Under the Hood
Four engineering choices decide whether a context graph is trustworthy or just decorative: how it keeps time, how it represents meaning, how it records decisions, and how agents read it without hammering your source systems. None of them is solved by a bigger model.
Every fact carries two clocks: when it was true in the world (valid time) and when the graph learned it (transaction time). That bitemporal model is what makes a verdict replayable. An agent reconstructs the graph as of the moment the alert fired. It reasons against what was true then, not today’s view projected backward onto a two-week-old event.
Facts expire on their own: an exception with a valid-to date in the past stops shaping verdicts the moment it lapses, with no cleanup job required. Where a source streams changes, the graph updates within seconds; where it doesn’t, scheduled reconciliation diffs the source and patches what moved. The goal is to maintain one current, materialized view of the environment rather than re-derive it from scratch on every alert.
2. Typed Meaning, Not Generic Links
The edges carry semantics. Not a vague “related to” but rather “approved by,” “governs,” “grants access to,” “depends on” — the actual operational relationship between two nodes. Policies, access controls, and retention rules live in the graph as queryable nodes too, not as prose buried in a wiki.
That lets an agent traverse a real question — who can approve an exception for this asset, which policy governs this data, what gets exposed if this identity is compromised — as a graph query with known semantics, instead of inferring it from free text and hoping. Typed structure is what turns a diagram into something an agent can plan over.
3. Decisions as First-Class Nodes
This is the part most platforms never build, because it’s a data-model problem, not a feature you can bolt on later. Every verdict, exception, override, and escalation becomes a node in its own right. Each carries who or what made the call, the context available at the time (linked to the as-of state of the graph), the SOP it followed or broke from, and the outcome.
That captures the delta between the written process and what your team actually does — the institutional knowledge that normally lives in senior analysts’ heads and Slack threads, and leaves with them. An agent that only knows your playbook is brittle; one that also knows when your seniors override it, and why, is one the team can work alongside. It’s also what the next agent recalls: a new alert gets triaged against the decisions your SOC already reached on ones like it.
4. Read the Graph, and Keep It Yours
Re-querying the SIEM, EDR, and IAM from scratch on every alert is slow, costly, and punishing to the systems you depend on. Torq’s AI agents reason from one shared, current, normalized layer, so investigations compound instead of restarting at zero, and every action traces back through the reasoning chain to the decision behind it.
And because that layer encodes your most sensitive operational truth — who is privileged, what is exempt, where the gaps are — isolation is an architecture decision, not a config flag. Each tenant’s graph is its own store, learning stays per customer, and your data never enters a shared pipeline.
Where Context Fits in the Agentic SOC
The grounding layer, not the model, is where the real work of the AI SOC happens. You can swap the reasoning engine next quarter. What compounds over time is the graph that knows your environment, remembers your team’s decisions, and stays true as both change — and it’s the foundation most platforms skip, because it’s hard to build and harder to keep correct.
This is the first post in our series on Context, Memory, and Learning in the AI SOC. The next will introduce recall memory: how Torq pulls the most similar past cases to reach an automated verdict on a new alert, triaging it from what your SOC has already decided.
See what 450 security leaders said they want from AI in the SOC — and how to tell the platforms that can deliver from the ones that can’t.
August 24, 2026 Update: Gartner published an update to their AI Vendor Race report on 24 Aug 2026, in which Gartner (once again) names Torq the Company to Beat in AI SOC Agents for Threat Investigation.
The AI SOC category just got its definitive race assessment, and Torq is at the front.
In the May 2026 Gartner® report AI Vendor Race: Torq Is the Company to Beat in AI SOC Agents for Threat Investigation (Document ID: G00855833), Gartner names Torq the Company to Beat. Torq.io’s combination of deterministic and agentic reasoning, multi-agent system, and model context protocol integration makes it the pacesetter in AI SOC agents for threat investigations.
A Hybrid Architecture That Pure-Inference Platforms Can’t Match
According to Gartner, Torq’s defining architectural choice is the combination of its proprietary hyperautomation engine with agentic AI — rather than relying on inference alone. The hyperautomation engine provides deterministic, rule-based workflow execution for repeatable, high-volume tasks such as deduplication, normalization, and escalation routing. Socrates, the agentic OmniAgent layered on top, provides adaptive reasoning, deep investigation, natural language collaboration with analysts, and autonomous remediation for complex, novel threats. This hybrid architecture delivers what pure-inference competitors cannot: consistent, auditable outcomes for routine cases combined with human-level judgment for complex incidents.
According to Gartner, “This hybrid architecture delivers what pure-inference competitors cannot: consistent, auditable outcomes for routine cases combined with human-level judgment for complex incidents.”
We feel that this is the architectural bet Torq placed years ago. Torq believed then, and now more than ever, that this positions our customers for success as agentic AI is poised to fundamentally transform SecOps by working alongside human experts. This architectural decision and investment have now met the market moment.
Inside Torq’s Multi-Agent System
As part of Torq’s multi-agent system (MAS), Torq HyperAgents™ are coordinated by Socrates, Torq’s agentic orchestrator of the Torq AI SOC Platform. Moreover, Socrates serves as an agentic thought partner for natural-language collaboration with analysts as they investigate threats. Its Agentic Builder capability converts natural-language intent into production-ready Torq HyperAgents.
Torq HyperAgents collaborate in real time across the entire threat lifecycle, including but not limited to:
Triage, to ingest and normalize telemetry from across the security stack.
Investigation, to conduct root cause analysis, correlate related activity, and document evidentiary artifacts within Torq Case Management for collaboration and communication with stakeholders
Response, to rapidly contain threats and to remediate root cause
Socrates coordinates these specialized agents, managing handoffs and escalation decisions across the case lifecycle. Per the report, “Torq’s multiagent system represents the most mature multiagent implementation among dedicated AI SOC vendors.”
MCP-Native Architecture as a Structural Lead
Gartner identifies Torq’s native Model Context Protocol (MCP) integration as “the most consequential technical differentiator in the category. MCP standardizes how AI agents exchange context with external tools and data sources, enabling agents to dynamically discover, query, and act on any MCP-compatible system without requiring prebuilt API integrations.”
Torq serves as both an MCP host (accessing external MCP servers) and a client (exposing its own workflows as MCP tools for other agents). This is what an AI-native architecture looks like in 2026, built from the ground up to operate as part of an interoperable agentic ecosystem.
Enterprise Scale, Time to Value, and Commercial Momentum
The Gartner report includes several observations on the size, momentum, and trajectory of the Torq customer base.
On customer base and global reach, the report states: “With over 250 enterprise customers — a figure that doubled in 2025 — and global enterprise references, Torq has achieved cross-sector production validation at a scale no pure-play AI SOC competitor has matched.”
On time-to-value, the report observes: “Customers report being live and automating phishing triage within 48 hours — a time-to-value metric that sets the benchmark for the category.”
On the MSSP channel, the report describes: “Its MSSP channel is equally mature: providers like RSM use Torq AI SOC Platform as the operational backbone of their managed security service delivery.”
On financial position, the report notes Torq’s “$1.2 billion valuation and $332 million in total funding that provide the most substantial resource advantage in the category.”
For buying teams evaluating which AI SOC vendors will still be evolving their platforms three years from now, the combination of enterprise traction, time to value, channel maturity, and financial position helps inform a more complete vendor evaluation.
Our Take on the AI SOC Category
The AI SOC category is just over a year old. Most of the platforms in today’s conversation did not exist 24 months ago. For security buyers, the question isn’t whether AI belongs in the SOC — that’s settled, with 94% of security leaders now using AI in at least one SOC function. The harder question is which platform to anchor the AI SOC on, and which vendors have the architecture and commercial muscle to operate at enterprise scale three years from now.
Automation and agentic reasoning are complements rather than substitutes
The platform that wins will be the one buyers can run end-to-end across the threat lifecycle
We believe this Gartner analysis confirms that this architecture is where the category must head. It is certainly where Torq already resides. And we are not done.
The Road Ahead for the AI SOC
The AI SOC category will continue to evolve. New entrants will push the architecture, and the leader designation will be contested. From our perspective, the architecture we built — and the customer base built on top of it — sets a benchmark we plan to keep raising.
Read the full report, accessible to Gartner clients only.
Gartner, AI Vendor Race: Torq Is the Company to Beat in AI SOC Agents for Threat Investigation, Tom Powledge, Matt Milone, 25 May 2026.
GARTNER is a registered trademark and service mark of Gartner, Inc. and/or its affiliates in the U.S. and internationally and is used herein with permission. All rights reserved.
Gartner does not endorse any vendor, product or service depicted in its research publications and does not advise technology users to select only those vendors with the highest ratings or other designation. Gartner research publications consist of the opinions of Gartner’s research organization and should not be construed as statements of fact. Gartner disclaims all warranties, expressed or implied, with respect to this research, including any warranties of merchantability or fitness for a particular purpose.
Every security vendor promises great support. Dedicated Customer Success Manager. Fast response times. Proactive guidance. It’s in the pitch deck and on the pricing page, somewhere between “seamless onboarding” and “24/7 availability.”
And for the first few months, it’s usually true. Someone knows your name. The check-ins are regular. Requests get handled.
Then your CSM rotates. The ticket queue replaces the direct line. Feature requests disappear into a backlog you’ll never see. The quarterly business reviews become a formality — if they happen at all. And you realize that “dedicated support” meant “dedicated until renewal.”
This is the pattern security teams describe again and again when they talk about the vendor they had before Torq.
Five Years on a Legacy Platform and a Support Model That Quietly Eroded
A five-person cybersecurity team at a global commercial real estate firm spent nearly five years on a legacy platform. The product worked okay. Support did too — at first.
“[Their support] started decent but became less responsive year over year,” the Director of Cybersecurity Engineering and Operations recalled. “We got pushed to the general help desk. No regular check-ins. No proactive guidance.”
The Lead Cybersecurity Engineer who ran the platform daily put it more bluntly: “You’re kind of a number with them.”
This wasn’t a dramatic support failure. Nobody filed a ticket that went unanswered for weeks. The issue was subtler and more corrosive: the vendor had lost its investment in the team’s success. No working sessions to optimize their environment. No one flagging new features that could solve existing pain points. No one reviewing their workflows and saying, “Here’s a better way to do this.”
The platform didn’t evolve, and neither did the relationship.
For a lean team that needed every edge it could get, that passivity was a liability.
A Support Model Built Around Capability, Not Dependency
When the team migrated to Torq, the difference wasn’t incremental; it was structural.
Implementation was a partnership, not a handoff. The team’s implementation partner at Torq didn’t build the platform for the customer and hand over the keys. He reviewed the Lead Cybersecurity Engineer’s work, suggested improvements, and made sure the team owned the knowledge. By the time migration was complete, the team had deep platform expertise in-house — from day one.
That’s a deliberate choice. Building everything for a customer is faster, but it creates dependency. Dependency is how the last vendor relationship went sideways. Torq’s model builds capability, not reliance.
The relationships are direct and personal. The team works with a dedicated CSM and a technical Sales Engineer they can reach directly — not through a ticketing portal or a dispatcher. Response times are under an hour. When the Lead Cybersecurity Engineer has a question, he calls someone at Torq who knows his environment. That person picks up.
“I feel like I have an extension of myself [at Torq] that I can reach out to whenever I need to.”
– Lead Cybersecurity Engineer
The learning goes both ways. The Lead Cybersecurity Engineer and his Torq SE hold regular working sessions to exchange knowledge. The engineer shows the SE creative solutions he’s built. The SE shows the engineer platform capabilities he hasn’t explored yet. Both sides look forward to these sessions.
Proactive, not reactive. Torq’s team monitors platform health, flags opportunities, and brings new features to the customer’s attention with specific context on how they apply to their environment. That’s the difference between a support team and a success team.
1,000+ Hours Saved: The Support Behind the Numbers
Support quality rarely makes the top three criteria in a vendor evaluation. It should.
Every security automation platform is only as good as the team operating it. And the team operating it is only as effective as the support behind it. When a five-person security team is building, maintaining, and expanding an AIS program across an entire enterprise portfolio, the difference between “submit a ticket and wait” and “call your SE and solve it in an hour” is the difference between shipping new workflows every month and shipping none.
This team saved nearly 1,000 analyst hours and $120,000 in Q1 2026 alone. They’re targeting $600,000 savings for the year. Those numbers reflect the platform, yes — but they also reflect a support relationship that accelerates the team instead of slowing it down.
The Lead Cybersecurity Engineer built custom integrations to tools that weren’t natively supported. With his previous vendor, that would have meant a professional services engagement — a separate contract, a separate timeline, a separate team unfamiliar with his environment. With Torq, he used the integration builder, got stuck on one piece, called his SE, and had it resolved the same day.
Every integration this team builds themselves is a professional services engagement that they don’t pay for. Every workflow they ship without waiting in a support queue is time returned to the operation. The ROI of good support doesn’t show up as a line item. It shows up in everything else moving faster.
From Customer Workaround to Platform Feature
The Lead Cybersecurity Engineer is now collaborating with Torq to build his homegrown ROI tracking methodology into the platform for other customers to use. That’s not a support interaction. That’s co-development. It started when the Torq team saw what he built, recognized its value, and asked, “Can we make this a feature?”
That doesn’t happen when your vendor treats support as a cost center.
The Director of Cybersecurity Engineering and Operations framed the contrast in terms any buyer should hear before signing a vendor contract: “There’s a desire from Torq that we get the most out of this tool as possible. With our old vendor, you’re one of many products — not even customers.”
That distinction — between being a product user and being a customer — is the entire gap.
Five Questions That Reveal a Vendor’s Real Support Model
If you’re evaluating security automation platforms, these questions will reveal more about support quality than any reference call:
Who is my day-to-day contact, and how do I reach them? If the answer involves a ticketing portal as the primary channel, that tells you everything. Direct access to a named human who knows your environment should be the baseline, not a premium feature.
What does onboarding look like — do you build for me, or with me? A vendor should do both, depending on what you need. Some teams want us to ship the deployment fast so they can start running cases on day one. Others want to learn the platform alongside the build so they own every workflow from the start. We do both, often in the same engagement — fast deployment for the high-volume use cases, hands-on enablement for the workflows your team will iterate on long-term. Either way, you walk away owning what you run.
How will the relationship evolve after implementation? Regular working sessions, proactive feature guidance, and platform health monitoring should be standard, not require an escalation.
What happens when I need something outside your integration library? This is where support models diverge sharply. Some vendors route you to professional services with a separate SOW. Others give you the tools to build it yourself and the support to unblock you when you get stuck.
Can you show me what support looks like for a team my size? Lean teams need more support, not less. If the vendor’s model scales by reducing access, you’ll feel it within six months.
“A Thousand Times Better”
When asked to compare Torq’s support to the vendor they replaced, the Lead Cybersecurity Engineer didn’t hedge: “Torq support has been a thousand times better. And I’m not overemphasizing — I actually mean a thousand times.”
Most vendors will tell you they care about customer success. Torq is built so you don’t have to take their word for it.
Security automation has evolved dramatically. The rule-based playbook model built for a different era of threats can’t keep pace with today’s alert volumes and attacker speeds.
AI-driven security automation uses AI Agents to handle the full SOC lifecycle: triage, investigation, response, and resolution.
Three pillars define the new model: agentic execution, context grounding, and end-to-end coverage.
Enterprise SOCs are deploying AI-native platforms and seeing measurable results in resolution rates, analyst capacity, and time-to-contain.
Security automation used to mean building a playbook. Someone on the team mapped out a workflow, connected a few tools, and watched it run on the alert types it was designed for. That worked for a while, in a different environment than the one security teams operate in today.
The gap is architectural, not effort-based. The automation model most teams inherited was built for a world where alert volumes were manageable, playbook maintenance was sustainable, and attackers moved at human speed.
This blog covers what changed, why it matters operationally, and what to look for in the platforms built for the new model.
What Has Changed in Security Automation Since 2021?
The automation model from five years ago was a real step forward. Codifying SOC workflows into repeatable playbooks reduced manual work, improved consistency, and let smaller teams cover more ground. For the threats and volumes of that era, it was the right tool.
Three forces have since pushed the model past its limits:
Alert volume has outpaced hiring. The analyst pipeline hasn’t kept up with the alert pipeline. 90% of security leaders say AI has positively impacted SOC workload — because without it, teams were drowning. You can’t hire your way out of the volume problem. The math doesn’t work.
Attackers are operating at machine speed. The CrowdStrike 2026 Global Threat Report clocked the average eCrime breakout time at 29 minutes, with a fastest observed time of 27 seconds. Response workflows measured in minutes aren’t designed for that reality.
AI capability has crossed into production. Agentic execution — AI Agents that reason through a case, take action, and escalate at the right boundary — is running in SOCs today. Building for agentic execution from the ground up expands what’s possible — you get broader coverage, deeper reasoning, and the ability to handle cases no one ever programmed for.
The category is moving fast. Most implementations haven’t caught up yet.
What is AI-Driven Security Automation?
AI-driven security automation uses AI Agents to handle SOC work end-to-end — from triage through investigation, response, and case resolution — with grounded operational context and analyst oversight when warranted. It replaces rule-based playbooks with autonomous agents that reason on context, learn from analyst decisions, and adapt as the environment changes.
The practical difference shows up in three ways.
Legacy Security Automation
AI-Driven Security Automation
Execution model
Rule-based playbooks, hand-built workflows
AI Agents operating under declarative instruction
Coverage
Limited to pre-built playbook scope
Unbounded alert types — handles what it wasn’t programmed for
Adaptability
Requires manual rewriting as threats evolve
Learns from analyst decisions over time
Speed is measured in seconds rather than minutes. Coverage expands from playbook-bounded to unbounded. Adaptability shifts from a maintenance task to a native capability.
The architectural distinction matters here. Layering AI features onto a workflow-based engine changes the execution speed. Building for agentic execution from the ground up changes what’s possible. Such as the scope of coverage, the depth of reasoning, and the ability to handle cases the platform was never explicitly programmed for.
Before you evaluate platforms, it’s worth understanding how AI Agents work in the SOC and where agentic execution delivers the biggest operational lift.
Why is Traditional Security Automation Falling Behind?
Three failure modes compound, and most teams are dealing with all three at once.
Tool sprawl. The average SOC runs seven AI tools. 80% of security leaders say their tools are still fragmented, and adding more point solutions doesn’t close the gap. It makes it bigger. Each new tool introduces its own interface, data model, and maintenance burden.
Rule rot. Workflows built last year don’t map cleanly to this year’s threat landscape. Quarterly playbook reviews rarely happen. Version control for automation logic mostly doesn’t exist. Teams often don’t notice until something breaks under pressure.
The cumulative effect is a security stack that costs more each quarter while the MTTR climbs and attackers operate at speeds that make manual investigation timelines structurally unworkable.
The opportunity is real: addressing these three failure modes with an AI-native architecture — one built for agentic execution, context retention, and end-to-end coverage — is where teams are finding the biggest gains.
What Makes Security Automation “AI-Driven”?
Three pillars separate AI-driven security automation from automation with AI features attached. Each one is non-negotiable.
1. Agentic Execution
AI Agents are autonomous, scoped, and accountable. They handle the case rather than triggering a static playbook. Each agent operates under declarative instruction: a defined role, defined tools, defined data access, and a defined decision boundary. It reasons through the case, acts within its authority, and escalates at the right threshold.
Torq HyperAgents™ is built on this model. Every action is logged in a transparent timeline. Every decision sits in an immutable audit log. 90% of security leaders say explainable AI decisions matter most. Agentic execution delivers that transparency by design, because each step in the agent’s reasoning is visible and auditable.
2. Context Grounding
Agentic execution without context leads to worse decisions. The Torq Context Graph keeps every agent grounded in the operational reality of the environment, providing a full picture of who the user is, what the asset means, which policies apply, and what the team has decided in similar situations.
The Context Graph operates across five dimensions: temporal (when), provenance (source), semantic (meaning), governance (constraints), and decision trace (why). With the recent Jit acquisition, Torq extended this grounding capability across the full agentic lifecycle, accelerating the context work by years. 92% of security leaders rank continuous learning as the top capability they want in an AI SOC platform. Continuous learning depends entirely on a context layer that captures and retains decisions over time.
3. End-to-End Coverage
Most “agentic AI” tools on the market focus on triage. They generate a verdict, attach some context, and hand it off to a human. Investigation, containment, remediation, and case closure remain manual work.
End-to-end means the Torq AI SOC Platform handles everything: triage, investigation, response, and resolution. All on a unified case management layer with consistent context at every step.
Where Does AI-Driven Security Automation Deliver?
The use cases with the highest ROI share three traits: high volume, repeatable structure, and heavy manual context requirements. Where all three are present, AI-driven automation compounds fast.
Phishing Triage and Response.Phishing remains one of the highest-volume, most time-consuming workflows in the SOC. Lennar Corp cut phishing response time from hours to minutes after consolidating workflows on the Torq AI SOC Platform, the kind of operational shift that frees analyst capacity for higher-complexity work.
Identity Threat Response. Identity-driven attacks are now the dominant initial access vector. AI-driven automation correlates identity anomalies across IAM, EDR, and cloud control plane in seconds. The speed difference at this stage is the difference between containment and breach.
Multi-Cloud Alert Triage. Alert volume across AWS, Azure, and GCP is a problem no human team can process at scale. Bloomreach scaled automation beyond the SOC entirely — starting with multi-cloud security operations and expanding across IT and business workflows on a single platform.
Threat Enrichment and Investigation. Manual evidence gathering is one of the biggest drains on analyst capacity — correlating alerts across tools, pulling context, building timelines by hand. Torq’s AI Agents handle enrichment and investigation autonomously, assembling the full case picture so analysts walk in with context already built, not a raw alert to decode. Teams using this model report getting that time back for threat hunting and strategic work.
The common thread: the teams seeing the biggest results started with their most painful manual workflow and let the platform compound from there. The SOC teams that move first on AI-native architecture are pulling ahead on resolution rates and analyst capacity.
How Do You Evaluate AI-Driven Security Automation Platforms?
Six questions cut through the noise when evaluating vendors.
1. Does the platform handle the full incident lifecycle, or only triage? End-to-end coverage separates AI SOC Leaders from point solutions. Ask for proof, not demos.
2. Is every AI decision grounded in an operational context? Threat intel enrichment is the floor. Grounding means reasoning on the full picture: who the user is, what the asset means, what policies apply, and what the team has decided in similar situations before.
4. Can the platform handle unbounded alert types? Look beyond the demo’s curated scenario set. Real environments produce alerts the platform was never explicitly programmed for. The question is whether the agents reason through novel cases or stall on them.
5. Does it integrate natively with your existing stack? API depth matters more than connector count. Ask about time-to-deploy for tools not on the standard integration list, and whether unlimited users are included by default — the licensing structure changes total cost significantly.
The buyers asking these questions will find that AI SOC Leaders answer them cleanly. Understanding what AI security automation tools can actually do at the architecture level makes those conversations faster and more decisive.
The Category Has Moved. The Buying Conversation Should Move With It.
Security automation in 2026 isn’t in the same category as it was in 2021. The alert volumes, attacker speeds, and AI capabilities available today have created a fundamentally different operational environment and a new standard for what automation should deliver.
Torq is built natively to this model. The Torq AI SOC Platform is recognized as a Leader by KuppingerCole, Gartner, GigaOm, and is covered by Forbes as the architecture enterprises are moving toward. The platform was designed for agentic execution from day one: end-to-end coverage, context grounding at every step, and transparent AI decision-making that analysts can trust and auditors can verify.
The gap between platforms built for agentic execution and those that have added AI capabilities over time is showing up in production outcomes, resolution rates, analyst capacity, and time-to-contain. That gap is what security buyers are increasingly asking about. The teams that make the move now are the ones setting the new baseline.
The 2026 AI SOC Leadership Report has the data on what 450 security leaders actually want from automated identity threat response.
AI-driven security automation uses AI Agents to handle security operations work end-to-end — from alert triage and investigation through response and case resolution. Unlike rule-based automation, which operates within pre-built playbooks, AI-driven platforms reason through context, handle unbounded alert types, and learn from analyst decisions over time. Learn more about how AI Agents work in the SOC.
How does AI-driven security automation reduce alert fatigue?
Alert fatigue builds when analysts spend most of their time triaging, enriching, and manually contextualizing alerts rather than responding to threats. AI-driven security automation handles the high-volume, repeatable triage work autonomously, routing what matters, resolving what doesn’t, and preserving analyst capacity for Tier 3 critical risk. See how SOC teams are deploying this model.
What's the difference between AI-driven security automation and traditional security automation?
Traditional security automation executes rule-based playbooks on alert types it was explicitly programmed to handle. AI-driven security automation uses AI Agents that reason through cases, operate across unbounded alert types, and adapt as the environment changes, without requiring manual playbook rewriting. The architectural difference is most visible in coverage, adaptability, and end-to-end case resolution. See how automated SOC incident response compares in practice.
What are common use cases for AI-driven security automation?
High-ROI use cases share three traits: high volume, repeatable structure, and heavy manual context requirements. The most common include phishing triage and response, identity threat detection, multi-cloud alert triage, GRC audit support, and cloud misconfiguration remediation. Each maps to a workflow where AI Agents can handle the full lifecycle rather than just the first step. Explore incident response automation use cases in detail.
How do AI Agents work in security automation?
AI Agents are specialized autonomous systems that operate under declarative instruction — a defined role, defined tools, defined data access, and a defined decision boundary. Each agent reasons through the case, acts within its authority, and escalates at the right threshold. In the Torq AI SOC Platform, every agent action is logged in a transparent timeline, and every decision sits in an immutable audit log. Learn more about Torq’s AI Agents for the SOC.
How do you evaluate AI-driven security automation platforms?
Six questions matter most: Does the platform cover the full incident lifecycle? Is every AI decision grounded in operational context, not just threat intel enrichment? Are decisions explainable and auditable? Can it handle alert types it wasn’t programmed for? How deep is the native stack integration? And what named customer outcomes exist beyond demos? The 2026 AI SOC Leadership Report sets the record straight for what security leaders are saying about the AI SOC.