Most of the CISOs I talk to agree with all of it. And yet many of them haven’t moved.
This is the piece I wanted to write most, because it’s the one I’ve lived. The gap between agreement and action is not a new phenomenon in security. But with agentic AI, the cost of that gap is compounding faster than it ever has before.
The Gap Is Not What You Think
When I ask CISOs what’s holding them back, I rarely hear “budget.” I rarely hear “we don’t believe in the technology.” I almost never hear “our board said no.”
What I hear is hesitation. And hesitation, in my experience, is not one thing. It’s a collection of smaller, quieter blockers that don’t show up in a slide deck but absolutely show up in the pace of decision-making.
It sounds like this:
“We’re waiting to see how the market shakes out.”
“We need to finish our current platform migration first.”
“We haven’t figured out who owns this internally.”
“I want to do a proper evaluation, and we just haven’t had the bandwidth.”
None of these are unreasonable on their own. But stacked together, they produce the same outcome as saying no without anyone ever having to say it.
Ownership Is the First Problem
In most organizations I’ve worked with, AI adoption sits in an awkward governance gap. Security wants it, IT has opinions about it, data teams think they should lead it, and the CISO knows they need it but isn’t sure whether it is a security or an enterprise technology initiative, or something else entirely.
When nobody steps forward to own the decision, the decision doesn’t get made. It gets deferred into a working group, studied for another quarter, and revisited at the next offsite.” And six months later, the CISO is still in the same position — agreeing that AI is necessary, attending the same vendor demos, and waiting for something to change.
Here’s what I’ve learned: whichever function grasps the nettle first will benefit most. Security is uniquely positioned to lead AI adoption because we already operate under the conditions that make it essential — relentless alert volume, machine-speed threats, and a structural inability to hire our way out. We don’t need permission from another function to solve our own operational challenges. We need to lead.
If security doesn’t step into that role, someone else will make the decisions for us. And they will optimize for their priorities.
Fear of Getting It Wrong
There’s a second blocker that’s harder to talk about: the fear of making a wrong bet.
CISOs are trained to be risk-averse. It’s in the job description. When the AI SOC vendor market is noisy, fragmented, and moving fast — when every vendor is claiming “agentic” and the analyst landscape is still forming — the safest-feeling move is to wait for the market to mature and let someone else go first.
I understand the instinct. I’ve had it. When I was on the practitioner side, the biggest thing that slowed me down was the lack of a clear framework for distinguishing between what was real and what was marketing. Every vendor had a slide that looked like the future. Very few of them could explain what happened when you actually turned it on.
But here’s the problem with waiting: the threat environment is not waiting with you. AI-augmented attacks are accelerating. The gap between your attack surface and your defense capability is widening every quarter you don’t act. And the accountability question — did you fail to adopt capabilities that would have materially reduced your exposure — is already being asked by boards and insurers. Regulators will follow.
Waiting feels safe. It is not.
The Market Has Shifted
Something has changed in the last 6-9 months: the hesitation is starting to break.
A year ago, at InfoSecurity Europe, the conversations I was having were exploratory. CISOs were curious but cautious. They wanted to understand what “AI SOC” really meant. They were doing research, comparing vendors, and trying to determine whether the category was mature enough to warrant a serious evaluation.
This year, the conversations are different. CISOs are coming in with approved budgets and set timelines. Some are skipping the proof of concept entirely and going straight to purchase — a signal that they understand the problem, they’ve done their homework, and they have organizational momentum behind them. The early majority is moving.
The organizations that acted 12 months ago are now operating at a fundamentally different speed. They have AI handling Tier 1 and Tier 2 triage around the clock. They’ve moved analysts out of repetitive ops and into roles where they apply judgment, not just process volume. They’re measuring outcomes, not activity. And they’re doing it with the same headcount — or less.
The question is no longer whether AI belongs in the SOC. The question is whether you’re going to design this intentionally or scramble to catch up.
What the Smallest Step Looks Like
If you’re a CISO who agrees AI is necessary but hasn’t moved yet, here is the most practical advice I can give: stop trying to solve the whole problem at once.
Pick one category of alerts. Something repeatable, consistent, and high-volume — phishing, maybe, or endpoint detections that follow a predictable pattern. Something where the decision criteria are clear and the risk of an autonomous action is low.
This is exactly where the Torq AI SOC Platform starts. Auto Triage ingests your alerts, filters the noise, and surfaces the cases that actually matter. From there, specialized AI Agents handle the investigation and response (within the guardrails you define), while your analysts focus on the judgment calls that need them. You don’t bolt AI onto your existing workflow. You start with an execution layer and build around it.
Set the guardrails, watch the output, and build confidence in the results. Measure what changes: time saved, accuracy, analyst capacity freed up, and then expand. Carvana is auto-resolving 100% of Tier 1 and Tier 2 cases. That’s what the trajectory looks like when you start with the right platform.
You don’t need a 12-month roadmap, a team reorganization, or buy-in from every stakeholder. You need one use case, one quarter, and the willingness to start.
Everything I’ve written in this series — the Outcome, Judgment, Execution model, the org design shift, the accountability conversation, the case that human-centric security no longer scales — it all becomes real when you take that first step.
The Window Is Closing
I want to end this series where I started: with a direct challenge to every CISO reading this.
You agree. I know you do. The data is clear, the technology is deployable, the market has validated it, and the threat environment demands it. The only thing between agreement and action is a decision.
The organizations that design around this model now will have the agility to operate at machine speed when it matters most. The ones that wait will try to bolt it on mid-crisis and wonder why nothing holds together.
The future of the SOC is humans at the edges and AI in the middle. The only question is whether you design that intentionally or let it happen to you.
Don’t let this be the year you watched from the sidelines.
AI incident response uses AI agents to investigate, contain, and remediate security incidents at machine speed, while humans set goals and approve high-impact actions.
It follows the familiar incident lifecycle, detection, triage, investigation, containment, eradication, and recovery, and accelerates every phase.
Proactive AI hunts for weak signals and closes gaps before incidents start, and reactive AI works on live incidents from alert to resolution.
An effective plan starts with a readiness assessment, a clear framework, defined approval gates, and documented policies.
The Torq AI SOC Platform brings together agentic triage, investigation, case management, and response, with humans in control.
Ask a SOC lead where the first hour of an incident goes, and much of it disappears into logging in to consoles, copying indicators between tabs, and waiting for approvals. The attacker keeps moving the whole time. AI incident response gives that hour back: AI agents gather evidence, scope the threat, and make initial containment moves while your team stays in command.
Below, you’ll find what AI incident response means, how it compares with traditional approaches, how to build a plan, and which technologies and use cases matter most.
The Role of AI in Incident Response for Modern Threats
Attackers now use AI to move faster and look more convincing, so defenders need the same advantage. AI gives incident response the speed and reach to keep up.
How AI Is Changing the Security Landscape
Attackers use AI to write convincing phishing messages, scale reconnaissance, and adapt tactics in minutes. That increases both the volume and quality of threats reaching the SOC.
Defenders answer with AI of their own. Agentic AI reasons through an investigation, picks the right tools, and takes action, so the SOC moves from reading alerts to resolving them.
Key Differences Between AI-Driven and Traditional Incident Response
Traditional incident response built the foundations of the discipline, and AI extends its reach. The table shows where the two approaches differ in practice.
Dimension
Traditional incident response
AI-driven incident response
Initiation
An analyst picks up an alert from the queue
An AI agent starts investigating the moment the alert arrives
Evidence gathering
Analysts query each tool by hand
Agents pull evidence from connected tools and build the timeline
Scaling
Capacity grows with headcount
Capacity grows with agent coverage
Consistency
Depends on the responder and the shift
The same guidelines apply to every incident
Documentation
Written up after the fact
Recorded as the agent works, with reasoning logged
Human role
Performs most steps
Sets goals, reviews reasoning, and approves key actions
Why Modern Threats Require an Evolved Response Approach
Modern attacks cross endpoints, identities, cloud, and SaaS in a single campaign, so responders need to correlate signals across many tools. Attack timelines keep shrinking, and hybrid environments add more places to look.
A response approach built for these threats pairs machine-speed investigation with human oversight. It treats every tool in the stack as both a source of evidence and a place to act.
Core Concepts of AI Incident Response
AI changes how incident response gets done, but the underlying goals stay the same: find the threat, limit the damage, and restore normal operations.
Defining AI Incident Response
AI incident response is the use of AI agents to carry out incident response tasks: triaging alerts, investigating scope and root cause, containing threats, and remediating. Humans set goals and approve high-impact actions.
Teams give an agent guidelines in plain language, such as “handle phishing reports using these steps,” and the agent works out the details. The term also covers responses to incidents involving AI systems themselves.
The Evolution of Incident Response Lifecycles
Classic frameworks like the NIST four-phase model and the SANS six-step model describe the same arc: prepare, detect and analyze, contain, eradicate, recover, and learn. Early programs ran those phases as manual handoffs between people and tools.
Scripted automation then sped up individual steps. AI agents take the next step by carrying context from phase to phase, so detection, investigation, and containment flow as one continuous motion, and lessons learned feed straight back into preparation.
Essential Components of AI-Powered Incident Response
Strong AI incident response rests on six building blocks:
A data foundation. Alerts and telemetry from across the security stack arrive normalized, so agents reason over consistent information.
Agentic reasoning. AI agents plan the investigation, choose tools, and explain each conclusion.
Integrations and response actions. Agents act through the EDR, identity, email, and cloud tools your team already runs.
Case management. One record holds the evidence, timeline, and decisions for every incident.
Guardrails and human oversight. Approval gates and auditable logs keep people in control.
A learning loop. Analyst feedback and past cases improve every future verdict.
Proactive vs. Reactive Approaches in AI Incident Response
AI supports incident response on both sides of the clock: before an incident starts and while one is underway. The strongest programs invest in both.
What It Means to Be Proactive with AI
Proactive AI looks for trouble before an alert demands attention. AI agents hunt through telemetry for weak signals, flag unusual identity and access behavior, and prioritize exposures by the risk they pose to your business.
Proactive work also improves detections. Triage outcomes show which rules generate noise and which catch real activity, and agents can recommend tuning to keep the queue cleaner over time.
Reactive Response Scenarios with AI
When an incident is live, AI agents run agentic response for the first minutes, which matter most. Common scenarios include:
A reported phishing email. The agent analyzes the message, checks for indicators, removes it from mailboxes, and flags users who clicked it.
A suspicious endpoint alert. The agent gathers process and network evidence, scopes the activity, and isolates the host when guidelines allow.
A possible account compromise. The agent reviews sign-in history, checks for impossible travel, and forces a credential reset after approval.
In each case, the agent records its reasoning and hands the analyst a complete case.
Balancing Automation and Human Judgment
The right balance depends on the action. Low-risk, reversible steps, such as blocking a known malicious indicator or quarantining a phishing email, suit autonomous execution. High-impact steps, such as isolating a production server or disabling an executive account, call for human approval.
Teams that set these approval gates up front get speed where it is safe and oversight where it counts. Auditable logs of every agent decision let analysts review, adjust, and override at any time.
Developing an Effective AI Incident Response Plan
A strong incident response plan tells people what to do, and an AI-ready plan also tells AI agents what to do. Start with where you stand today, then build up.
Assessing Organizational Readiness
A short readiness review shows where AI agents can help first. Ask these questions:
Which tools generate alerts, and do they offer APIs that agents can use?
Which incident types consume the most analyst hours?
Who approves containment actions today, and how quickly?
How consistent is the quality of your telemetry and asset data?
What are your baseline numbers for mean time to investigate (MTTI) and mean time to respond (MTTR)?
The answers set your starting point and give you a baseline to measure against.
Building a Framework for AI Incident Response
Most teams succeed by starting small and expanding with evidence:
Pick two or three high-volume use cases, such as phishing reports and endpoint alerts.
Write plain-language guidelines that tell the agent how your team handles each one.
Connect the tools the agent needs to gather evidence and take action.
Set autonomy levels and approval gates for each type of action.
Pilot with analysts reviewing every verdict, then loosen review as accuracy proves out.
Measure results, tune the guidelines, and add the next use case.
Policy Design and Documentation Essentials
Clear documentation keeps people and agents aligned, and it satisfies auditors. A complete set of policies covers:
Roles, escalation paths, and on-call responsibilities are captured in a triage checklist that analysts can use live.
Which actions agents may take on their own and which need approval.
Data access and handling rules for agents.
Logging and audit requirements for every agent decision.
Communication templates for executives, customers, and regulators.
A review cadence, including tabletop exercises that involve both analysts and agents.
Key Technologies and Tools in AI-Powered Incident Response
AI incident response works best as part of a connected stack. These are the technologies that matter most and how they fit together.
Popular AI Incident Response Platforms and Solutions
The market offers three broad categories of AI-powered incident response tools: AI SOC platforms that cover the full threat lifecycle, point solutions that focus on a single stage, such as triage, and established security tools that add AI features. Platforms that run the whole lifecycle give teams the most leverage because each verdict flows straight into investigation and response.
When you evaluate options, look for:
Coverage from triage through remediation.
Deep integrations with the stack you already run.
Transparent reasoning and auditable logs.
Human approval controls for high-impact actions.
The ability to customize agents around your own guidelines.
Integration with SIEM, EDR, and Legacy Security Automation Tools
AI agents add value on top of the tools you already own. Your SIEM supplies detections and logs, your EDR supplies endpoint evidence and containment actions; and legacy security automation keeps running the scripted steps your team trusts. Agents bring the investigative judgment that ties those pieces together.
The Torq AI SOC Platform connects to more than 400 security tools out of the box, so agents can read from and act on the stack you already run. Your existing investments stay in place and gain more reach and speed.
The Role of Generative AI in Agentic Incident Response
Generative AI gives agents the ability to read unstructured data such as emails, tickets, and threat reports, then summarize it, reason over it, and decide the next step. Analysts also benefit because they can ask questions about a case in natural language and get a clear summary back.
Generative AI speeds up building, too. With Agentic Builder, security engineers describe what they need in plain language and get a deployed AI Agent. Pair that flexibility with guardrails and approval gates, so every agent acts within limits your team defines.
Benefits of AI in Incident Response
Teams adopt AI incident response for three reasons: results arrive faster, quality holds steady, and capacity grows without a matching jump in headcount.
Increased Speed and Accuracy
Speed is where incident response automation pays off first. AI agents start investigating the moment an alert arrives, gather evidence in parallel, and apply the same guidelines every time. Torq Auto Triage averages 42 seconds per alert and reaches 94% accuracy out of the box, improving as analysts confirm or correct verdicts.
Faster, more consistent investigation shortens the whole lifecycle. Torq delivers a 90%+ reduction in MTTR.
That capacity extends across use cases, too. Once an agent handles phishing effectively, the same approach applies to endpoint alerts, identity events, and cloud findings.
Enhanced Threat Detection and Insights
Agents correlate signals that humans would need several consoles to connect, and they map findings to frameworks like MITRE ATT&CK so the attack story is easy to follow. Each case adds to a memory of what normal looks like in your environment.
Those insights flow back to detection engineering. Patterns across cases reveal noisy rules, coverage gaps, and recurring attack paths, so your detections improve with every incident your team closes.
Real-World Use Cases and Case Studies
The scenarios below show how AI agents handle two demanding incident types, followed by the lessons teams carry into successful deployments.
Responding to Supply Chain Attacks with AI
Picture a trusted vendor update that rolls out across your environment, and soon endpoints begin making unusual outbound connections. An AI agent correlates endpoint, network, and identity telemetry, identifies every host running the affected version, and checks indicators against threat intelligence.
From there, the agent scopes the exposure, isolates high-confidence compromised hosts under your approval rules, and opens a case with a complete timeline. Speed matters because the same compromised component often runs in many places at once, and agents investigate those places in parallel.
AI in Addressing Insider Threats
Now picture a departing employee who pulls an unusual volume of files to a personal cloud storage service. An agent combines data loss prevention alerts, identity activity, and access history, then compares the behavior against the normal baseline for that role.
Insider cases carry privacy and HR considerations, so guidelines route them to a human with the evidence already assembled. The agent shortens the evidence gathering, and people make the judgment calls.
Lessons Learned from Successful AI Incident Response Deployments
Teams that succeed with AI incident response tend to share a few habits:
They start with high-volume, well-understood use cases.
They write agent guidelines the way they would train a new analyst.
They keep humans in the loop at first and expand autonomy as accuracy proves out.
They insist on transparent reasoning and auditable logs.
They measure MTTI and MTTR before and after, so results speak for themselves.
They feed analyst corrections back into the system.
The results can be striking. Carvana’s CISO reports that Torq agentic AI now handles 100% of the company’s Tier 1 security alerts.
The Future of Incident Response Is Agentic
AI incident response gives SOC teams the speed, consistency, and capacity that modern threats demand. AI agents handle investigation and containment around the clock, while analysts focus on decisions that require human judgment.
The path forward is clear: start with a few high-volume use cases, set approval gates, and expand as results prove out. Along the way, the platform you choose decides how far AI agents can take your team, so evaluate options carefully and look for transparent reasoning, deep integrations, and human control.
AI incident response is the use of AI agents to triage, investigate, contain, and remediate security incidents, with humans setting goals and approving high-impact actions. The term also covers responding to incidents that involve AI systems, such as prompt injection or data leakage from a model.
How does AI software reliability impact incident response strategies?
AI software reliability determines how much autonomy a team can safely give AI in the response process. Models can misread context or produce confident but wrong answers, so strong strategies include validation, deterministic guardrails, human approval gates for high-impact actions, and ongoing monitoring of agent accuracy. Auditable reasoning lets analysts verify conclusions, and fallback procedures keep response moving if an AI component is unavailable.
What challenges do organizations face when responding to incidents involving AI systems?
Incidents involving AI systems bring challenges such as prompt injection, data leakage through model inputs and outputs, poisoned training or retrieval data, misuse of connected tools and permissions, and unpredictable model behavior. Evidence can be harder to gather, and ownership may span security, engineering, and data science teams. Teams that inventory their AI systems, log prompts and tool calls, and assign clear owners turn these challenges into manageable work.
How do organizations develop an effective incident response plan for AI systems?
Start by inventorying every AI system and the data and tools it can reach. Then add AI-specific incident categories to your plan, such as prompt injection, data leakage, and model misuse, and define owners and escalation paths across security, engineering, and data science. Set up logging for prompts, outputs, and tool calls, write containment guidelines like revoking an agent’s credentials or disabling a model endpoint, and test everything with tabletop exercises.
How do AI agents improve incident response?
AI agents start investigating the moment an alert arrives, gather evidence across tools, apply consistent guidelines, and take approved response actions. Torq Auto Triage handles the front door by filtering noise and prioritizing real threats, and the Torq AI SOC Platform carries true positives through investigation, containment, and remediation. Analysts stay in control through approval gates and auditable logs.
EDR finds the threat. Without an AI SOC behind it, alerts still wait in a queue for a human to triage, investigate, and respond.
The Torq AI SOC Platform carries EDR alerts from detection to resolution, so you get the full value of the endpoint investment you already made.
Endpoint detection and response (EDR) gives a SOC more visibility into endpoint activity than any other tool in the stack. That visibility is the biggest EDR benefit, and it’s also where most teams stall. Every process, connection, and registry change becomes telemetry, and every suspicious pattern becomes an alert someone has to work on. When attackers can move from initial access to lateral movement in under half an hour, the speed of response after the alert matters as much as the detection itself.
This guide covers the core EDR benefits, why they matter more than ever in 2026, where EDR alone hits its limits, and how an AI SOC turns endpoint visibility into decisive action.
What Is Endpoint Detection and Response?
EDR is security software that continuously records activity on endpoints (laptops, servers, virtual machines, and cloud workloads), analyzes that activity for signs of compromise, and gives defenders the tools to investigate and respond. A lightweight agent on each device streams telemetry to a central platform, where detection logic and behavioral analytics flag anything that appears to be an attack.
In practice, an endpoint detection and response solution catches what perimeter tools miss: a user’s browser spawning PowerShell, an unsigned binary reading credential stores, or a server suddenly connecting to an unfamiliar IP. From the same console, analysts can pull the full process tree, isolate the host, kill the process, and collect forensic artifacts.
Leading EDR companies include CrowdStrike, Microsoft, SentinelOne, Palo Alto Networks, and Trend Micro. The market is growing fast: Mordor Intelligence values EDR at $6.33 billion in 2026, rising to $18.68 billion by 2031.
EDR vs. Antivirus
Traditional antivirus compares files against signatures of known malware and blocks matches. That worked when attacks relied on malicious files. They mostly don’t anymore.
According to the CrowdStrike 2026 Global Threat Report, 82% of detections in 2025 were malware-free. Attackers log in with stolen credentials and use the admin tools already on the machine, so there’s no file for antivirus to catch. EDR watches behavior instead: what a process does, what it touches, and how it fits the normal pattern for that device and user.
Antivirus answers, “Is this file known to be bad?” EDR answers, “Is this activity an attack?”
Six Key EDR Benefits for the Modern SOC
The value of EDR shows up in SOC outcomes. These are the benefits that matter most to a SOC director.
Continuous endpoint visibility: Every endpoint becomes a sensor. Analysts can reconstruct exactly what happened on a device, shortening investigations and reducing guesswork.
Behavior-based threat detection: EDR catches fileless attacks, living-off-the-land techniques, and credential abuse that signature tools miss. With most intrusions now malware-free, this benefit keeps EDR essential.
Faster detection and containment: Network isolation, process termination, and file quarantine are built in, so an analyst can stop an attack from spreading without logging into the device.
Forensic depth and threat hunting: Historical telemetry lets hunters search for indicators across the fleet and trace an attack back to initial access.
Reduced breach impact: Catching an intrusion during the window between initial access and lateral movement can be the difference between a single compromised laptop and an enterprise-wide incident.
Compliance evidence: EDR produces the detailed activity logs and response records that auditors expect.
Compliance and Regulatory Advantages
EDR compliance value comes from the record it keeps. HIPAA requires audit controls on systems that handle patient data, PCI DSS requires anti-malware protection and logging in cardholder environments, and GDPR requires organizations to detect and report personal data breaches promptly.
EDR telemetry helps with all three: it shows when an endpoint was compromised, what data it could reach, and what the team did about it. Paired with a platform that documents every response action, it turns daily operations into an ongoing compliance record instead of a pre-audit scramble.
EDR for the Enterprise
At enterprise scale, EDR has to cover tens of thousands of endpoints across offices, data centers, and multiple clouds, alongside other EDR tools inherited through acquisitions. Deployment planning covers agent performance on critical servers, coverage of legacy and OT systems, and how EDR data flows into the SIEM and case management systems.
Smaller organizations face a different problem: they rarely have analysts to watch EDR around the clock, which is why EDR for small businesses is often delivered through managed EDR services.
The SOC Director’s Challenge: Why EDR Alone Isn’t Enough
EDR is excellent at detection. The limit starts after the alert fires.
Alert volume outpaces analysts. EDR is one of the noisiest sources in the SOC. In the 2026 SANS State of Detection Engineering survey, 66% of false positives were traced back to vendor-provided detection rules, the kind of out-of-the-box content EDR tools ship with. Without AI or automation, every one of those alerts still needs a human to decide whether it matters.
Attackers are faster than manual triage. The CrowdStrike report puts average eCrime breakout time at 29 minutes, with the fastest at 27 seconds.
Attackers now target EDR directly. ESET researchers analyzed nearly 90 EDR killers in early 2026 and found that 54 of them use vulnerable signed drivers to disable security tools, and Cisco Talos reported that tooling tied to the Qilin ransomware group can disable more than 300 EDR drivers. When EDR goes quiet on a host, that silence is itself a signal, but only if it’s correlated with identity, network, and cloud activity.
Context lives in other tools. An EDR alert says what happened on a device. It doesn’t know whether the user is a VIP, whether the host is a crown-jewel server, or whether the same pattern was closed as benign last week. Analysts pivot across consoles to find out, and the average SOC already runs seven or more AI tools, most of them disconnected.
Exposure keeps growing. The 2026 Verizon DBIR found ransomware in 48% of breaches, and vulnerability exploitation overtook stolen credentials as the top initial access vector at 31%. EDR is often the first tool to see either one land.
Amplifying EDR Benefits With the Torq AI SOC Platform
The Torq AI SOC Platform sits on top of the EDR you already run and carries its alerts through the full threat lifecycle: triage, investigation, response, and remediation. It integrates natively with leading EDR platforms, including CrowdStrike, SentinelOne, and Microsoft Defender, among more than 400 integrations.
Torq Auto Triage normalizes every EDR alert, enriches it with business context and threat intelligence, and delivers an explainable verdict before an analyst is involved. Torq HyperAgents® investigate and respond, and Torq Socrates™ orchestrates them across the lifecycle. Every decision is grounded in the Torq Context Graph, which resolves identities, assets, and relationships across your stack, and every step is logged so analysts and auditors can see exactly why an action was taken.
A New EDR Workflow: From Alert to Autonomous Resolution
Here’s how a typical endpoint threat moves through Torq.
Alert: CrowdStrike flags credential dumping on a finance workstation at 2am.
Triage: Torq Auto Triage enriches the alert in seconds. The Context Graph shows the device belongs to a finance user with access to payment systems, threat intelligence flags the hash, and Torq Recall finds no benign precedent in past cases. Verdict: true positive, high severity.
Case: A case opens automatically, mapped to MITRE ATT&CK, with the evidence attached.
Investigation: Torq HyperAgents pull the process tree, check identity logs for suspicious sign-ins, and search the fleet for the same hash on other endpoints.
Containment: Within the guardrails your team set, Torq isolates the host through the EDR, revokes the user’s sessions in the identity provider, and blocks the hash everywhere. High-impact actions can require analyst approval: autonomy is a dial you set, not a switch.
Resolution: The user and on-call analyst are notified in Slack or Teams, the ticket is updated, and the case is documented end-to-end. When the analyst confirms the verdict, Torq Reflex learns from it, so the next similar alert is handled even more accurately.
The analyst starts their day by reviewing a contained, fully documented incident rather than discovering an attacker who had a six-hour head start.
The Measurable Impact of an AI SOC
The payoff shows up in the metrics SOC directors report on. One global pharma enterprise cut EDR triage noise by 97% and reduced MTTR by 92% in its first quarter on Torq. Torq customers have achieved response times up to 10x faster, and Carvana runs 100% of its Tier 1 alerts through Torq’s AI Agents.
Industry data points the same way. Per IBM’s Cost of a Data Breach Report 2026, organizations that use AI and automation extensively in security save about $1.93 million per breach and contain breaches 65 days faster than those that don’t, compared with a global average breach cost of $4.99 million.
Analysts stop clearing noise and start working on the threats that need human judgment, which is how a SOC scales without adding headcount.
Turn EDR Visibility Into Action
EDR benefits are real: deep visibility, behavior-based detection, forensic depth, and compliance evidence. But visibility only pays off when it turns into action, and in 2026 that action has to happen at machine speed. Attackers move in minutes, operate without malware, and increasingly go after the EDR itself.
Pairing EDR with an AI SOC closes that gap. Torq triages every endpoint alert, investigates in context, and responds within the guardrails you define, so your team gets the full return on the EDR investment you already made.
The main EDR benefits are continuous endpoint visibility, behavior-based threat detection, faster containment through built-in isolation and remediation, forensic data for investigations and threat hunting, and detailed logs that support compliance. Together, they help a SOC catch attacks earlier and limit how far they spread.
How does EDR work?
EDR agents continuously record endpoint activity, including processes, file changes, network connections, and user behavior. The platform analyzes that telemetry with detection rules, behavioral analytics, and threat intelligence, raises alerts on suspicious activity, and gives analysts tools to investigate and respond, such as isolating a device or killing a process.
What is the difference between SIEM and EDR?
EDR focuses on endpoints, collecting deep telemetry from devices and enabling direct response actions like host isolation. A SIEM aggregates logs from across the environment, including network, identity, cloud, and applications, to correlate events and support compliance reporting. Many SOCs use both and layer an AI SOC platform on top, with EDR feeding detections into the SIEM and the AI SOC handling triage and response across them.
What are the methods of endpoint detection?
The main methods of endpoint detection are signature matching for known malware, behavioral analysis that flags suspicious actions regardless of file, anomaly detection against an endpoint’s normal baseline, machine learning models trained on attack patterns, and threat intelligence matching on indicators such as file hashes, domains, and IP addresses.
What are examples of EDR?
Common EDR products include CrowdStrike Falcon Insight, Microsoft Defender for Endpoint, SentinelOne Singularity, Palo Alto Networks Cortex XDR, and Trend Micro Vision One. All five vendors were named Leaders in the 2025 Gartner Magic Quadrant for Endpoint Protection Platforms.
John White is the Field CISO for EMEA at Torq. A respected security executive with more than 20 years of leadership experience, John previously served as CISO at Virgin Atlantic, where he led a multi-year transformation deploying the Torq AI SOC Platform to modernize cyber operations. Prior to that, he built and transformed security functions for global organizations, including ASOS, Liberty Global, AEG Europe, and KPMG.
I’ve briefed a lot of boards, and I’ve watched plenty of sharp security leaders lose one. The strategy was sound and the spend was justified, but the room still went quiet in the wrong way because the briefing was built for a SOC standup rather than a boardroom.
Every serious conversation about AI in the SOC eventually reaches the board. Whether it lands depends on two things: a platform that can back the claims, and the language you use to make them. After 20+ years on the practitioner side, here are the four frames I’ve watched directors actually respond to, and the words I’d leave outside the door.
If you’ve followed this series, you know the scenario: More than 100 vendors now claim the “AI SOC,” most stop at triage or bolt chatbots onto legacy systems, and the AI SOC Apocalypse Manifesto laid out how to tell the real platforms from the pretenders. The boardroom is where all of that noise turns into a budget decision. Brief it well, and the platform you chose becomes an obvious yes. Brief it badly, and you hand the room a reason to wait another year, while attackers keep moving at machine speed.
Frame 1: Value and ROI
Boards don’t fund security. They fund business outcomes, and your AI SOC story has to connect to value creation as tightly as it connects to risk. The question in the room is simple: what do we get, and what does it cost?
So give them the all-in numbers, framed as risk-adjusted ROI. In plain terms, that’s three things:
What the AI SOC delivers (faster containment, more threats handled, capacity recovered without new hires)
What a breach would cost the business if our controls fail
What we spend to close that gap while keeping the business fast
Don’t frame it as money saved. Adding AI agents rarely means cutting analysts, so the honest story is one of incremental returns. For the extra you invest, how much more do you get back in threats handled, time to contain, and work closed within SLA? The capacity you free up gets redeployed into higher-value work, and that redeployment is its own line of value. Measured that way, security spend reads as protection for the bottom line, not a tax on innovation.
The line I’d use: “Here’s the value our AI SOC creates, here’s what a failure would cost us, and here’s what we spend to keep moving fast safely.”
Frame 2: Strategic Focus
Most boards have sat through a dozen AI demos and watched none of them reach production. They know pilot purgatory when they see it, and their patience is thin. Don’t walk in with a menu of experiments. Walk in with a short, ranked list of high-impact commitments tied to what the business already cares about.
In the SOC, that means being honest about where AI earns its keep — autonomous triage and response on the high-volume, time-sensitive work — and where it’s merely table stakes. Governance effort should scale with impact: an agent that can contain a host or disable an account deserves board-level attention; one that drafts a summary doesn’t. Showing the board you’ve drawn that line demonstrates focus rather than FOMO.
The line I’d use: “We’ve pointed AI at the few SOC outcomes that move the needle, and we govern each one in proportion to what it can touch.”
Frame 3: Risk Appetite and Governance
This is the frame that may be the most consequential. AI has crossed a line our governance habits haven’t caught up to: it moved from suggesting to executing. It triggers live workflows, queries production systems, and takes actions that affect the business, sometimes before a human reviews the output. Once a system acts, governance has to graduate from a static PDF policy to active permissioning — who can touch what, under which approvals, with what rollback.
The framing that works in the room is autonomy as a dial, not a switch. You widen it as trust builds: start with low-risk, high-volume processes, verify the outcomes against what a good analyst would have done, and expand layer by layer. That measured, risk-based approach is exactly what boards and auditors want to see.
Give the board the risks in plain language: data leakage, model abuse, integrity failures, model supply-chain exposure, and compliance pressure as rules, such as the EU AI Act’s high-risk requirements, take effect in August 2026. Then show the guardrails are formal: documented as policy, operationalized in the platform so they’re enforced automatically, and reviewed on a set cadence — not a set of good intentions in a Slack channel.
Expect the board, and later the auditors, to get specific, so have the answers ready: What due diligence did we apply? Have we risk-assessed each process we’ve automated? Do we understand the data involved and the regulatory requirements around it? How do we evidence that what’s in place is working? The point that lands: as autonomy goes up, blast radius goes up, so governance has to scale with it instead of lagging behind.
The line I’d use: “As our AI started taking action, we tightened the guardrails to match: scoped permissions, human approval on high-impact moves, and a rollback for everything it does.”
Frame 4: Accountability and Ownership
The last question is the shortest: Who owns this? Boards want a single accountable owner and unmistakable role clarity across leadership. In nearly every AI incident I’ve tracked, the root cause wasn’t a purely technical failure. It was three executives in a room, each assuming the problem belonged to someone else. When it goes public, that confusion becomes the headline. The story isn’t “the model got it wrong.” It’s “no one was in charge.”
So bring a clean RACI. The business owns outcome and use-case risk acceptance; security owns the controls and monitoring; legal owns regulatory alignment; the AI solution owner sets standards and lifecycle governance; and the board owns oversight and risk appetite. For the SOC specifically, be explicit about who owns an autonomous agent’s actions, who reviews them, and how an escalation reaches this board.
The line I’d use: “Here’s exactly who owns the AI’s decisions, who reviews them, and how an escalation reaches this board.”
The Language to Leave Out
The fastest way to lose the room is to brief the board the way you’d brief your team.
Drop the jargon. “Agentic,” “LLM,” “SOAR,” product names, model names — none of it survives contact with a board, because directors don’t buy architecture; they buy outcomes. Drop the vanity metrics, too. Raw alert volume and integration counts measure how busy you are, not how protected the business is. And go easy on the superlatives. “Fully autonomous” and “revolutionary” invite skepticism faster than they build confidence.
Before any capability comes out of your mouth, translate it into risk, dollars, or defensibility. If it doesn’t map to one of these, it doesn’t belong in the room.
A Briefing That Lands in Three Slides
If you want a board briefing structure you can reuse, this is the one I keep coming back to:
The risk. Machine-speed threats against human-speed response, in business terms.
The move. An AI SOC that reduces exposure, expands capacity, and stays defensible.
The proof. Your own before-and-after numbers — time-to-contain, capacity recovered — and the governance that backs them.
The AI SOC Decision Underneath the Briefing
The board conversation isn’t really about whether to adopt AI in the SOC. Machine-speed threats made that call for most of us already. It’s about which platform earns the risk, capacity, and defensibility story you’ll tell in that room.
This is where the AI SOC Apocalypse Manifesto‘s test follows you into the boardroom: If it can’t take action, it’s not an AI SOC. A triage-only tool can’t honestly promise a board faster containment, because it stops at the verdict and hands the real work back to your team. The same pretenders that look fine in a demo fall apart the moment a director asks, “So what happens after the alert fires?”
A true AI SOC gives you all of these frames at once. It reduces exposure by taking action across the full threat lifecycle. It expands capacity by handling the repetitive work, so your people can focus on judgment. And it stays defensible because every decision is grounded, logged, and reversible. That’s the platform that lets you walk into the boardroom with a story directors say yes to, and it’s the bar this series has held every “AI SOC” up against from the start.
The Torq team headed back to Vegas for CrowdStrike’s Fal.Con conference this week, and it quickly became clear that the conversation has moved past whether AI belongs in the SOC. This year, everyone wanted to know what happens after a detection fires and who actually closes the case.
That question is the reason Torq and CrowdStrike fit together so well: CrowdStrike finds threats, and the Torq AI SOC Platform finishes them. Here’s what stood out from the week.
The Gap in the Current SOC Model
We said it last year, and it was even more true this year. There are too many alerts, too few analysts, and too many threats slipping through the gap between the two. Detection has never been better. Closure is where teams still drown.
What changed in 2026 is the noise around the fix. The market is now crowded with “AI SOCs” that stop at triage — they summarize an alert, maybe suggest a next step, and hand it back to a human. That is not finishing the job. A CrowdStrike Falcon detection deserves a platform that carries it all the way from alert to closed case, automatically, and that was the bar everyone at Fal.con was measuring against.
What Everyone Was Talking About at Fal.Con 2026
Four themes came up at Torq’s Fal.Con booth.
Finishing the job, not just flagging it: A CrowdStrike Falcon detection flows straight into Torq Auto Triage, then investigation, then response, then a closed case, with prebuilt CrowdStrike steps and no manual handoff in between. Watching an alert close itself is a different demo than watching one get summarized.
Grounding agentic decisions in your SOC’s reality: Beneath Torq’s AI Agents sits the Torq SOC Brain™, the layer that makes autonomy trustworthy: the Context Graph models your environment, Torq Recall draws on your case history from day one, and Torq Reflex learns your team’s judgment over time. It is the difference between a platform that starts every shift from zero and one that remembers.
Turning autonomy into a dial:Socrates orchestrates Torq HyperAgents® with transparent, auditable reasoning and analysts on the loop. The point that landed: autonomy is a dial you widen as trust builds, not an all-or-nothing switch.
Bridging the SOC and the rest of the stack: Torq sits across CrowdStrike Falcon and other data sources to correlate, act, and manage data across the whole environment, not just one console. For teams running more than one data lake, that was the unlock.
Torq + CrowdStrike: Better Together
The Torq and CrowdStrike partnership runs deep. Torq’s AI SOC platform natively integrates across CrowdStrike Falcon detections, incident response, and vulnerability management with nearly 100 pre-built CrowdStrike steps ready to embed in Torq HyperAgents. There is no manual handoff between CrowdStrike finding a threat and Torq closing the case.
While Falcon Fusion automates inside the CrowdStrike ecosystem, Torq orchestrates those signals across the entire security stack — spanning identity, cloud, email, and ticketing. A Falcon detection triggers endpoint containment and then coordinates action wherever else it needs to go across the entire SOC.
Above the integration sits Socrates, Torq’s agentic AI SOC orchestrator that reasons through an investigation, plans next steps, and closes nearly 95% of cases automatically. But the entire action plan still runs on Falcon-native data from detection to remediation:
Detection: Falcon Next-Gen SIEM telemetry via CrowdStrike trigger
Investigation: Natural language hunting over Falcon telemetry through a Torq NGSIEM query agent
Response: Falcon Real Time Response commands executed from inside Torq
Vulnerability prioritization: CVEs from Falcon Exposure Management scores against CISA and NIST
Every alert triggered by CrowdStrike is fed into Torq Auto Triage for filtration and prioritization, and every security case gets AI case summaries, agentic investigation, and a full audit trail with explainable reasoning. The agentic decisions are based on the Torq Context Graph, building on Falcon telemetry with a real grounding in what’s true about the entire environment in that moment, and each alert allows the Torq AI SOC Platform to learn over time and produce more accurate responses.
The Torq and CrowdStrike partnership is the difference between a detection and a defensible outcome, with:
60-second average triage time
60x increased triage velocity
10x faster response
95%+ of Tier 1 work auto-remediated
Near-real-time case management on CrowdStrike data
Onstage: What a Unified AI SOC Actually Looks Like
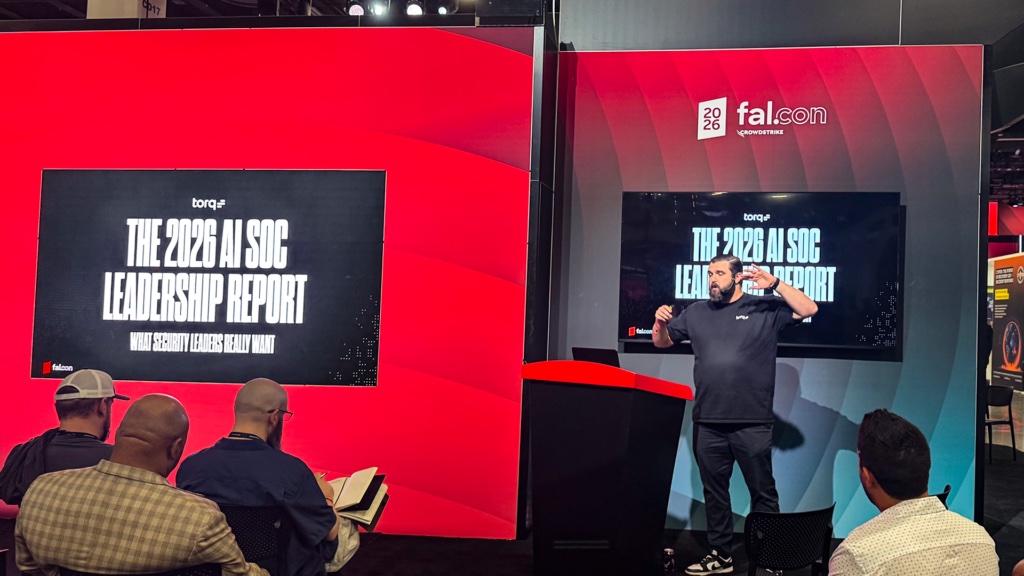
I had 20 minutes on the Fal.Con theater stage this year, and I used them to unpack a finding from Torq’s 2026 AI SOC Leadership Report: 94% of security teams now use AI somewhere in the SOC, the average team runs seven different AI tools, and 85% still say they want something different.
During the discussion, we talked about the tension in those data points. AI adoption is high, and so is the confidence, but most teams still aren’t satisfied. The reason is that most “AI SOC” tools stop at triage, so teams keep adding another one to cover the next gap until they end up with disconnected solutions that aren’t seeing the full picture, or worse, shelfware.
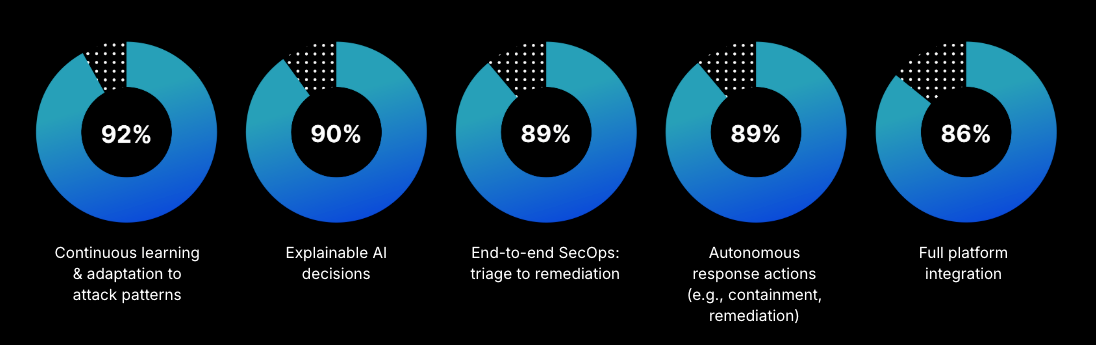
The data shows that it all comes down to trust and transparency in AI decisions. CISOs and security leaders need to see why AI reached a decision and how it got to that point before trusting it to actually act on the next one. When we asked those same CISOs what specifically they were looking for, the results were clear:
92%: Continuous learning & adaptation to attack patterns
I walked through what transparent, end-to-end agentic SecOps actually requires — carrying an alert from detection through remediation on one platform — and how enterprises like Carvana, Valvoline, and Kenvue are operationalizing it in production today, using the Torq AI SOC Platform.
See Torq + CrowdStrike in Action
Detection isn’t the hard part anymore. The advantage is in closing the case at machine speed, with a full audit trail behind every decision. CrowdStrike finds it. Torq finishes it. If we missed you at the booth, we’ll show you what that looks like on your own stack, running on your Falcon data.
APIs have become the dominant attack surface in enterprise environments, and API security companies provide the discovery, protection, and threat detection capabilities that keep them secure.
The API security market covers several distinct capability categories: API discovery and inventory, runtime threat detection, posture management, and API gateway security.
Leading API security platforms surface threats effectively, and the Torq AI SOC Platform extends their value by adding the autonomous response layer that turns detections into contained incidents.
AI Agents handle the investigation and triage work that security teams previously managed by hand.
The Torq AI SOC Platform integrates with API security tools across your stack, giving AI Agents the context they need to investigate, triage, and respond autonomously.
APIs power modern enterprise architecture. They connect applications, move data between services, authenticate users, and enable every cloud-native integration your organization depends on. They also represent the fastest-growing attack surface in enterprise security, and the one that traditional perimeter-based tools address least effectively.
API security companies emerged to address exactly that gap, building platforms that discover APIs across sprawling environments, monitor runtime traffic for attack patterns, and surface threats that would otherwise go undetected. This article covers what API security companies do, the major players and capability categories shaping the market, and how the Torq AI SOC Platform extends API security coverage with autonomous AI Agents that respond to threats the moment they are confirmed.
What Are API Security Companies, and Why Do They Matter?
APIs have become the connective tissue of enterprise infrastructure and a primary target for attackers who recognize that security teams often direct less attention to API-based attack surfaces than to traditional network and endpoint environments. Understanding the API security lifecycle clarifies what API security companies do and where each capability category fits.
The API Security Lifecycle
API security spans three distinct operational phases, and leading companies address one or more of them.
Discovery and inventory is the foundational phase. Enterprises frequently have thousands of APIs in production, including legacy endpoints, shadow APIs that development teams spun up outside formal security review, and third-party integrations that security teams have never formally cataloged. API discovery tools map the full API surface by analyzing traffic patterns, crawling gateways, and connecting to development pipelines to maintain a live inventory.
Runtime protection is the detection phase. Once APIs are discovered and cataloged, runtime protection platforms monitor live API traffic for attack patterns: authentication bypass attempts, injection attacks, excessive data exposure, broken object level authorization (BOLA), and volumetric abuse. Runtime protection tools use behavioral baselines to distinguish legitimate API usage from attack traffic, generating alerts when anomalies surface.
Response and remediation is where most API security programs find their greatest opportunity. What happens after detection determines actual security outcomes, and AI Agents that handle investigation, containment, and remediation autonomously turn API security from a detection capability into a complete protection program.
Why APIs Represent a Distinct Security Challenge
API-specific vulnerabilities differ from traditional web application vulnerabilities. The OWASP API Security Top 10 covers attack categories such as broken object level authorization, broken object property level authorization, and unrestricted resource consumption that perimeter firewalls and traditional WAFs handle poorly. API security tools understand API semantics and identify these vulnerability categories in runtime traffic.
API proliferation makes manual inventory management operationally impractical. Development teams create and modify APIs continuously through CI/CD pipelines, and the gap between what security teams know about and what actually exists in production grows with development velocity.
API attacks also generate alert volumes that manual triage struggles to keep pace with. A single API endpoint under attack generates thousands of alerts within minutes. The Torq AI SOC Platform’s Auto Triage capability handles that volume autonomously, investigating alerts and resolving them with AI Agents at each step.
Leading API Security Companies and Their Core Capabilities
The API security market has matured significantly, with specialized vendors covering each phase of the lifecycle and platform vendors combining several. Four capability categories define how they differentiate.
Runtime Detection and Behavioral Analysis
Runtime detection platforms monitor live API traffic and use behavioral analysis to identify attack patterns that signature-based tools miss. These platforms establish baseline models of normal API behavior and flag deviations that indicate attack activity.
Salt Security pioneered this behavioral analysis approach, using AI to model API behavior and surface attacks that standard rules-based tools would classify as legitimate traffic. These platforms excel at detecting business logic attacks that target API semantics, and each high-fidelity detection benefits from AI Agent investigation that converts alerts into closed incidents.
API Discovery and Posture Management
Discovery and posture management platforms build and maintain the API inventory that runtime protection depends on, connecting to gateways, analyzing traffic, and integrating with pipelines to map every API, including shadow endpoints. Noname Security (now part of Akamai) built strong capabilities here, combining discovery with posture management that surfaces misconfigured endpoints and sensitive data exposure. AI Agents then handle remediation at scale by opening tickets, routing findings to the right development teams, and automatically tracking status.
API Gateway Security and Traffic Management
API gateways sit in the data path between clients and backend services, enforcing authentication, rate limiting, and traffic policies. Dedicated gateways include Google Cloud Apigee, Kong, AWS API Gateway, and Azure API Management, while edge and web application and API protection (WAAP) platforms such as Akamai and Imperva (now part of Thales) enforce API security policy in the same traffic path.
Gateway and edge security provide the enforcement layer, while behavioral detection platforms handle the more sophisticated attacks that policy-based enforcement misses. Together they give security teams both proactive enforcement and reactive detection across the API surface.
Specialized and Emerging API Security Platforms
Wallarm delivers a unified API security platform combining discovery, runtime protection, and automated testing across web APIs and microservices. Cequence Security focuses on API protection against bot-based abuse and business logic attacks. 42Crunch specializes in API security testing integrated into development pipelines, helping teams catch API vulnerabilities before they reach production.
The market also includes cloud-native API security capabilities built into broader platforms: AWS API Gateway security features, Azure API Management, and GCP Apigee all offer API security capabilities as part of their cloud platform offerings.
What the Torq AI SOC Platform Adds to API Security
API security companies deliver strong detection, discovery, and enforcement. The Torq AI SOC Platform adds the layer that turns a confirmed API threat into a contained, documented, remediated incident, using AI Agents for the investigation, triage, and response steps that manual processes leave slow and inconsistent.
AI Agents for API Threat Investigation and Triage
When an API security platform surfaces an alert (an authentication anomaly, a BOLA attack pattern, a spike in error rates suggesting enumeration), an AI Agent in the Torq AI SOC Platform receives that alert and begins investigation immediately.
The AI Agent pulls identity context from IAM, checks the SIEM for related activity, queries the API inventory for endpoint sensitivity, and cross-references threat intelligence feeds, assembling the complete investigation picture before a human analyst sees the case.
Torq HyperAgents® handle this investigation autonomously. Torq HyperAgents is built to work across connected security tools simultaneously, correlating data from API security platforms, identity systems, SIEMs, and threat intelligence in real time. The result is faster, more consistent triage across every API security alert.
Torq Socrates™, Torq’s agentic SOC orchestrator, adds reasoning to the triage layer. Socrates evaluates each API security case in context, determines the appropriate response path, and executes or escalates based on the specific risk profile of the incident. High-severity API attacks trigger immediate containment. Lower-priority findings are routed to the appropriate team with full context attached.
Auto Triage for High-Volume API Alert Environments
API security environments generate significant alert volume, particularly in organizations with large API surfaces under active attack or testing. Auto Triage handles that volume by applying consistent investigation logic to every alert, resolving false positives autonomously and surfacing genuine threats with investigation context already assembled.
Security teams running Auto Triage reduce manual triage burden while improving detection accuracy. Explore how Torq’s automated SOC incident response applies to API security environments.
Agentic Builder for Custom API Security Response
API security environments vary significantly in tooling, API architecture, and response requirements. Torq’s Agentic Builder lets security engineers describe the API security response they need in natural language, and Agentic Builder deploys a production-ready AI Agent in minutes.
A security engineer building an API incident response capability describes the outcome: “When an API security alert is confirmed as a BOLA attack, identify the affected endpoint, pull the owner from the API inventory, open a P1 incident, notify the API team via Slack, and initiate a rate limit on the source IP via the gateway API.” Agentic Builder translates that description into a deployed AI Agent that executes the full response sequence autonomously.
Case Management Across API Security Incidents
Torq’s case management ensures every API security incident generates a complete, auditable record (alert, investigation findings, response actions, and outcome) captured automatically as part of the AI Agent’s execution. For enterprises subject to data protection regulations, that documentation supports compliance timelines without requiring manual reconstruction after the fact.
Building an API Security Program That Scales
API security at enterprise scale requires two layers working together: specialized API security platforms that provide discovery, behavioral detection, and runtime protection, and an AI SOC platform that extends those capabilities with autonomous investigation, triage, and response.
Is your API security program turning detections into autonomous response, or are analysts still closing the gap by hand?
Buying an AI SOC platform is a fundamentally different decision from any security purchase most leaders have navigated before. John White, Field CISO EMEA at Torq, wrote the AI SOC Buyer’s Guide from the buyer’s seat, drawing on 20+ years running security functions at Virgin Atlantic, ASOS, and Liberty Global. It covers the differentiators that separate real AI SOC platforms from marketing, the questions to ask every vendor, and a 90-day rollout framework for teams ready to move.
If you are evaluating how to extend your API security program with autonomous AI Agents, this is the framework that tells you exactly what to look for.
API security companies build platforms that discover, monitor, and protect APIs against attacks and misconfigurations. The market covers several capability categories: API discovery and inventory tools that map the full API surface, runtime protection platforms that detect attack patterns in live traffic, posture management tools that identify misconfigured or vulnerable endpoints, and API gateway and edge platforms that enforce authentication and traffic policies. Leading vendors include Salt Security, Noname Security (Akamai), Wallarm, Cequence Security, 42Crunch, Imperva (Thales), and cloud-native options from AWS, Azure, and Google Cloud. The Torq AI SOC Platform extends API security coverage by adding autonomous AI Agent investigation and response on top of detection platform alerts.
What are API tools used for in security?
API security tools serve three primary functions: discovering and cataloging the full API inventory (including shadow and legacy APIs), monitoring runtime API traffic for attack patterns and behavioral anomalies, and enforcing security policies at the API gateway layer. In a mature API security program, these tools feed alerts into an AI SOC platform that handles investigation, triage, and response autonomously. Learn how Torq’s AI Agents handle API threat investigation and response across enterprise API environments.
How does an API create security challenges?
APIs create security challenges for several reasons. API-specific vulnerability categories like broken object-level authorization (BOLA), excessive data exposure, and authentication bypass require specialized detection tools that understand API semantics. API proliferation makes manual inventory management operationally impractical, as large enterprises frequently have thousands of APIs in production including shadow APIs that security teams have never formally cataloged. API attack volumes also generate alert volumes that scale beyond manual triage capacity, creating the gap between detection and response that AI Agents address. Explore Torq’s security incident response capabilities for API security environments.
What is an API security gateway?
An API security gateway sits in the data path between API clients and backend services, enforcing authentication, authorization, rate limiting, and traffic policies.. Gateway security complements behavioral detection platforms: gateways enforce policies and block known attack patterns, while runtime detection platforms identify sophisticated attacks that policy-based enforcement misses. In an AI SOC program, gateway-level security events feed into AI Agents that investigate anomalies, correlate them with other security signals, and execute response actions across connected tools. See how Torq integrates across security tools to support API gateway security response.
How does an AI SOC platform extend API security?
Most API security platforms focus on detection and policy enforcement. An AI SOC platform extends that coverage by connecting detection alerts to autonomous investigation, triage, and response. When an API security platform flags a BOLA attack or authentication anomaly, an AI Agent investigates immediately, correlates findings across connected systems, and either contains the threat autonomously or escalates with a fully assembled case. The result is faster MTTR, consistent triage quality across high-volume API environments, and complete case documentation that supports compliance requirements. Explore Torq’s automated SOC incident response to see how this applies to API security specifically.
David Melamed is Head of Emerging Technologies at Torq. He joined through Torq’s acquisition of Jit, which he co-founded and has led as CTO since 2020, building agentic security on a production Context Graph. A cloud security veteran with 20+ years of experience, David previously held senior technical roles at Cisco (via the CloudLock acquisition) and MyHeritage.
Odysseus left Troy with a fleet and reached Ithaca with nothing, having lost every ship to the sea. While the war was won by force, the journey home was won by wits, and ultimately the fleet barely mattered.
Most security operations centers are still running their SecOps voyage the way Odysseus ran the war: more tools, more force, more signal. It is the wrong instinct, because the SOC bottleneck was never how much you can see. It is how fast you can decide.
You already agree with this. That is the problem.
Of course more tools won’t fix the SOC. Everyone knows that. “Tool sprawl” and “alert fatigue” have been on conference slides for a decade, and no security leader would defend buying their way to maturity out loud.
And yet the same people who nod along will buy another tool the next time a new threat class appears, stand up another console, and still report their program by how many detections fired rather than how many good decisions got made. A claim everyone repeats, but no one acts on, is not a consensus. It is a collective blind spot.
Tools are not the enemy, and a real coverage gap deserves a dedicated tool. The failure is reaching for a purchase when the real constraint is decisions, a move leaders may still knowingly make because a purchase is a single defensible act, and the system rewards visible action over structural change.
The Math Stopped Working
The first symptom is noise. Enterprise SOCs field thousands of alerts a day, and because the average SOC now runs seven AI-powered tools, with 80% of teams relying on disconnected point solutions, the same event often fires as duplicate alerts across several platforms with no shared context.
Most teams named false positives their single biggest detection challenge, and the rate is rising every year. That is the point, not a footnote. The flood is not raw blindness; teams can see plenty. But they lack the capacity to handle incoming alerts and make decisions fast enough to matter and with enough confidence to close the related case: is the suspicious PowerShell on a finance laptop an intruder or the IT team? Nearly two-thirds (62.5%) say they are simply overwhelmed by the volume of data.
The attacker is not waiting. Verizon’s 2026 Data Breach Investigations Report found that for the first time in 19 years, exploitation of vulnerabilities overtook stolen credentials as the top initial access vector, rising to 31% from 18% the year before, while breaches involving a third party climbed to nearly half of all cases. Verizon’s own read is blunt: the speed at which known vulnerabilities are now weaponized, accelerated by AI, risks a capacity crisis for security teams. The inflow is accelerating faster than any hiring plan can keep up with.
The consequence is not just wasted effort; it is lost coverage. Most analysts spend time manually sorting low-value alerts that should have been filtered upstream, ultimately leading to slow responses: about a third of teams (32.8%) take hours rather than minutes to respond to a threat. Hours are a losing trade against the velocity Verizon just described.
There is an easy answer on the market, and it is the wrong half. Speeding up triage is the win every tool sells, but automation that acts faster without proving when it is right does not remove risk. It simply relocates risk from a slow human to a fast machine no one has taught you to trust. Speed is not the hard problem. Earned trust is.
The Second Symptom Is Human
The other half of the equation is the people, and it is not fixable by hiring, because you cannot hire fast or cheaply enough.
The ISC2 2025 Cybersecurity Workforce Study, drawn from more than 16,000 practitioners, found that a third of organizations lack the resources to adequately staff their security teams, that skills gaps are now nearly universal, and that 72% of professionals believe cutting security staff materially raises the likelihood of a breach. The talent you do have does not stay: SANS found that 70% of analysts with five years or less of experience leave their roles within three years.
So the loop closes on itself. Volume overwhelms the team, the team burns out and turns over, institutional knowledge walks out the door, and the next analyst inherits an even larger backlog. You cannot hire your way out at the speed or price the math requires. The point is not fewer analysts; it is more decisions per analyst: people spending their hours on judgment calls only a human should make, instead of clearing queues a machine could clear.
You Can See It. You Cannot Assemble It Fast Enough.
It is tempting to call all of this a visibility problem. It is not, and the distinction is the whole point of this series.
Most SOCs are not blind. A great deal of telemetry exists, spread across dozens of consoles. But two things make “we can see it” a false comfort. First, raw data is not always easy to query in the moment, and the context that actually settles a decision often lives entirely outside the security stack. Confirming whether a flagged user is on approved leave means reaching into an HR system. Confirming whether that odd remote login was really an employee can mean pinging them directly. None of that is a detection feed, and none of it is one query away.
Second, even when the evidence is all technically available, someone has to assemble it. An analyst working on one alert pulls evidence from several tools, enriches the indicators, and checks by hand whether this signal connects to something the team has already seen, one pane of glass at a time.
Torq’s 2026 AI SOC Leadership Report, featuring 450 security leaders, puts a number on that bridging work: Analysts spend 8.6 hours a week validating and reconciling AI outputs across disconnected tools. That isn’t lost time. AI took over the old execution work, and 9 in 10 leaders say it has improved SOC workload. Those 8.6 hours are the new judgment layer.
The catch is where the hours go. Reviewing clear, explainable reasoning is time well spent. Stitching partial answers together across disconnected tools is not. Same 8.6 hours, and the difference is platform design. So a phishing verdict that should take minutes can sit for hours, not because the evidence is missing, but because assembling it is slow.
That is not a gap in what the SOC can see. It is a gap in how fast a human can gather scattered context, some of it outside the security tools, into a single judgment, and how little of that judgment survives the next shift change. Which puts manual correlation squarely on the decision side of the ledger, not the visibility side, and makes it one of the most expensive line items on that side.
The Bag of Winds
Let’s return to the Odyssey for a moment. A day from home, Aeolus gives Odysseus a bag holding every storm wind, so only a fair breeze carries him towards his home in Ithaca. In sight of the shore, his crew opens it, certain it hides treasure. The freed winds blow the ship all the way back out to sea. The gift was real, but it worked only while one condition held; the moment reality stepped outside it, the tool did not just stop helping — it undid the progress already made.
That is the signature of static playbook automation. It executes the steps a human mapped in advance, so it runs beautifully while an incident matches the script and fails the moment one does not — quietly, at the worst time. Automation itself is not the issue here. The problem is that deterministic-only automation, where every branch is pre-mapped by a human, has no answer for anything unmapped. The fix is not less automation; it is automation that can reason rather than replay a fixed script.
But adaptive automation brings its own failure mode: a confident wrong answer. So the hard part is not the reasoning; it is proving when to trust it. (But that is the focus of a later post; I will get back to it).
Zoom out, and the pattern repeats. SIEM promised that centralizing the logs would surface the answers, and delivered more signal with a search problem. SOAR promised that automating response would let humans step back, and delivered brittle playbooks to maintain. XDR promised cross-domain correlation and delivered real value, but still left a human to decide what each correlated case means. Each added capability downstream of the real SOC bottleneck, so each moved the constraint rather than removing it. Automate the response, and the bottleneck moves to triage. Centralize the logs, and it moves to investigation. The decision was always the part that did not scale.
The SOC Bottleneck Was Never Where You Were Spending
The honest test of any security investment is simple, and you can try it at home: Does it increase the number of correct decisions your team can make in a day, or does it just increase the number of things your team has to decide about?
Most of what the industry sold did the second while claiming to do the first. The tell is that more than half of teams still do not track mean time to detect or mean time to respond at all. The metric that would actually expose the problem is rarer still: time to decision — the gap between an alert arriving and a verdict someone will stand behind — as well as time to close the loop. Almost no one measures it. This series will argue that this, not visibility, is the binding constraint, and it will try to earn that claim post by post rather than assert it.
This is why buying the next tool out of anxiety can feel less like navigation than like adding one more ship to a fleet the sea will take anyway. The capability accumulates. The stack grows. And the thing that actually determines whether you get home, the capacity to turn scattered evidence into a decision to close, escalate, or contain, at the volume the sea throws at you, barely moves.
The cheapest first move is not another tool; it is a number: Start measuring time to decision, because you cannot fix a bottleneck you have never put a number on.
Where This Series Goes
Troy fell to force. Ithaca was reached by wits. The rest of this series is all about the wits: how to define maturity by the quality of decisions rather than the size of the arsenal, what changes when reasoning enters the loop, how to let automation act only when it has earned the right, and how to govern it so autonomy strengthens the SOC instead of becoming its next attack surface.
None of that means visibility never matters. Real coverage gaps are real, and sometimes a new tool is the right call. The point is narrower and more useful: for most SOCs, the next unit of value is not another feed of signal; it is the capacity to turn the signal you already have into decisions, faster and more reliably, at scale. That is the voyage. Everything else is just another ship in a fleet the sea is waiting to take.
Next in this series: Why the most mature SOC in your peer group is not the one with the most tools, and how to measure the difference.
For the data behind the shift this series is built on, the 2026 AI SOC Leadership Report captures how 450 security leaders are rethinking tooling, trust, and the decisions that actually move their programs forward.
Financial institutions are some of the hardest environments to secure. They hold the data attackers want most, they run payment rails that a breach can freeze, and they answer to the most overlapping set of regulations in any industry. When one is breached, the damage runs past exposed records into systemic risk and lost customer trust.
The average financial-sector data breach reached $5.56 million in 2025, second only to healthcare and well above the $4.44 million global average. The attacks keep climbing. Nation-state groups tripled their pace against the sector and stole more than $2 billion in crypto over the past year. Over a third of financial services incidents now start with social engineering, and confirmed ransomware in the sector rose about 30% from 2024 to 2025, with the first quarter of 2026 up 76% year-over-year. AI is in the mix now too, showing up in 16% of breaches through automated phishing and deepfake impersonation.
The threat is obvious. Keeping up with it is where the traditional SOC model falls short, and where AI-driven financial services SOC automation earns its place.
Why Financial Services SOCs Are Under Pressure
Most financial institutions run more security tools and get more alerts than any team can work through by hand, and the compliance load only adds to it. Analysts wake up to a flood of alerts, interpret them manually, gather context across disconnected systems, and run response steps one tool at a time. That worked until the volume outpaced the team, which in finance it already has.
Slow response is what makes the gap between alerts and capacity expensive. Across industries in 2025, organizations took an average of 241 days to identify and contain a breach, and the ones that ran past the 200-day mark cost $5.01 million on average versus $3.87 million for those caught sooner. For a bank, the longer an attacker goes undetected, the higher the odds of a frozen payment rail or a fraudulent wire.
Plenty of institutions turned to legacy SOAR to close the gap and found it added work instead of removing it. Playbooks pile up, each one tied to a couple of integrations, and the maintenance load lands on the detection engineering team. The platform ends up recording manual effort rather than reducing it. That’s a big part of why 85% of security leaders now say they want a single, unified platform they can trust. AI-driven financial services SOC automation, done right, is how they get there without adding headcount.
What Torq Does Differently
The Torq AI SOC Platform uses agentic AI and Hyperautomation to run the entire threat lifecycle (triage, investigation, response, and remediation) under your team’s direction, with every decision grounded in context, logged, and reversible. For financial institutions, Torq does three things that matter most.
Torq acts across the full lifecycle. Most tools marketed as an “AI SOC” stop at prioritizing an alert and hand the real work back to a human. A true AI SOC carries the alert through to resolution and only escalates to a person when human judgment is needed. In finance, that shortens the time between when an attack starts and when it’s stopped, and it leaves a defensible record of every move.
Compliance and auditability are built in. Financial services operate under PCI DSS, SOX, GLBA, FFIEC guidance, and SEC cybersecurity disclosure rules, with the EU’s Digital Operational Resilience Act (DORA) now fully applicable to financial entities and the EU AI Act’s high-risk requirements taking effect in August 2026. Torq builds audit-ready evidence into every agentic action. Torq HyperAgents® log their full reasoning chain, and native case management keeps a full chain of custody, so daily operations become a running compliance record instead of a pre-audit scramble.
It layers onto the stack you already run. With more than 400 integrations across tools like CrowdStrike, Microsoft Sentinel, SentinelOne, ServiceNow, and Wiz, Torq unifies response without a rip-and-replace. Where an integration doesn’t exist, teams prompt the Torq Socrates™ Agentic Builder in natural language to quickly build it.
Together, that lets financial institutions automate their most critical, highest-volume work: fraud and wire-transfer defense, phishing triage and containment, ransomware response, and identity and access management, all with the transparency and control a regulated environment demands.
What It Looks Like in Practice: FICO
FICO, the global analytics and financial services company, shows what happens when a financial institution moves to a real AI SOC. Its 24/7 global SOC had been running on a legacy SOAR where 95% of the work inside its playbooks was still done by hand. The team needed integration depth, automation reach, and a real support partnership, and moved to the Torq AI SOC Platform to get all three.
The migration was scoped at 90 days and delivered in about half that time, with more than 100 playbooks moved and consolidated, many collapsing from 10 steps down to a single automation that produced the same output. Today, FICO’s SOC runs on Torq end-to-end, from autonomous phishing investigation to 24/7 monitoring across teams in North America and Asia, with compliance evidence packaged for every workflow.
The results line up with what most financial institutions are after:
A 99.4% reduction in MTTR, from more than 150 hours to under an hour in nine months.
75% of cases closed by automation, 15 percentage points past FICO’s internal target, with analyst time concentrated on the cases that need human judgment.
Phishing response from about three days to under 30 minutes, as phishing workflow automation went from 60% to 95%.
A clean audit record across PCI DSS and country-specific cycles since the migration, with no case where Torq lacked the documentation an auditor asked for.
“When another security leader asks me whether the move from XSOAR to Torq was worth it, I tell them three things. We have the integrations we need, and when we don’t, we build them. We can run our own AI models inside our own workflows. And the support. The Torq team is in our standup every single week.”
– Ernesto Ugalde, Senior Manager of Detection Engineering at FICO
The Takeaway on AI-Driven SOC Automation for Financial Services
Financial institutions everywhere face the same squeeze: machine-speed attacks, rising regulatory pressure, and SOC teams that can’t scale by hiring.
What actually helps is an AI SOC that acts across the full threat lifecycle, works with the stack you already own, and can prove every decision to a regulator or a board. Another point tool or a repackaged SOAR won’t get there. That’s what Torq built, and it’s already running in production across some of the most demanding financial environments.
FICO is one of them, and its results show what that looks like in practice.
Most agentic triage solutions hand you a verdict and stop right there. Maybe you get an alert ranking, maybe a severity score, maybe some light investigation, but you, as the analyst, still have to do the cleanup manually. There is still a mountain of evidence that needs to be gathered by hand, and a mountain of cases to dig through on your own. If you’re lucky enough to have cases created for you, great, but you’re still the one logging back into different security solutions to close alerts, tune configurations, and, most importantly, take action.
Whether you work in an emergency room or in a Fortune 100 enterprise security operations center, triage, by definition, tells you what needs attention. The limitation of a triage-only solution in SecOps is that you won’t have visibility into the overall scope of threats or what your team decided the last time a specific indicator of compromise appeared in your environment.
That is why enterprise organizations need a complete, end-to-end AI SOC Platform. Want to hear more about what that looks like? Check out:
Clearly, the AI SOC is one of my favorite things to talk about! But today, we are going to take a turn and actually talk about triage. Not your standard, LLM-wrapped chatbot — but true, agentic auto triage with a brain… Torq Auto Triage.
What Agentic Triage Should Actually Deliver
Here’s the thing about triage: It was always meant to be a compromise. The reason triage exists in the first place is that human analysts don’t have the bandwidth to handle deep investigations into every single alert at enterprise scale, so the triage step was born to differentiate which alerts were worth investigating and which weren’t.
The problem is that most triage-only tools baked that same compromise into their solutions. They applied agentic AI to the problem (too many alerts) but replicated the same old outcome (prioritizing only the most critical alerts).
But using AI to solve the problem means we don’t have to accept the same logic. With AI on our side, “triage” now can, and should, go much deeper than surface-level filtering.
When an alert enters the SOC, the analyst needs a complete picture of what happened, what it means in the context of the organization, and what the right next move is before anyone has to look at it. Sometimes, the move is still to flag it as a false positive and remove it from the queue. Other times, the correct flow is immediate escalation to a Tier 3 analyst or incident responder for critical action.
But between the obvious false positives and the critical escalations lies a bulk of ambiguous alerts that require investigation to resolve. And that middle ground is where Torq Auto Triage shines.
How Torq Auto Triage Works
Torq Auto Triage applies organizational context, threat intelligence, and security case history to every single alert it receives, delivering increasingly accurate verdicts and suppressing noise. It is fully integrated with any of the near-limitless security solutions found in your SOC and, most importantly, into the Torq AI SOC Platform to drive deeper investigation, containment, and remediation actions.
Mean time to triage is 60 seconds, and customers running Torq Auto Triage report a 97% reduction in EDR alert noise and a 60x improvement in triage velocity.
Every alert that Torq Auto Triage ingests is normalized to the Open Cybersecurity Schema Framework (OCSF), with observables such as IPs, domains, file hashes, and user identities extracted immediately upon arrival. It then enriches each alert with OSINT and commercial threat intelligence, as well as your organization’s historical case data, before any verdict is even made. This is completely out of the box, meaning there are no manual enrichment playbooks or workflows to maintain.
From there, Torq Auto Triage weighs the observables and attack stage against your SOC’s history of similar activity — using Torq Recall to drive exact, deterministic observable matching and Torq Reflex to align with your SOC’s actual historical judgment calls — before coming to a verdict, all in under 60 seconds.
Each verdict includes a severity score, MITRE ATT&CK mapping, full agentic reasoning logs, and recommended next steps. To ensure VIP users are always treated as critical, regardless of what probability models and agentic reasoning might say, deterministic guardrails created by your team are always running in parallel and baked directly into Torq Auto Triage.
The Verdict Is Just the Beginning
Once a verdict is made with Torq Auto Triage, there are a few paths forward in the Torq platform. True positives automatically become cases in Torq Case Management, with all the evidence, context, and next steps already assembled. The verdict is immediately encoded in the Torq Context Graph, visible for reference in both the Torq Auto Triage alert and the case itself. This means that, regardless of whether the case is assigned to a human analyst or handled by Torq HyperAgents®, neither starts from scratch.
Non-malicious findings do not become cases, but are similarly logged and stored for future reference. And every alert is auditable and reviewable by a human, so every confirmation or correction can become an intelligence signal that trains Torq Auto Triage — powered by the Torq SOC Brain — to continuously learn over time and improve accuracy with each alert.
The Accuracy Curve
Most agentic triage solutions perform roughly the same way on day 100 as they do on day 1,000, because every alert is treated as if it’s the first time the system has seen it. Analyst corrections from last week don’t change the way a verdict is made this week, because that institutional knowledge is buried in closed tickets across disparate security tools.
Torq Auto Triage is different because of the Torq SOC Brain™, the learning and memory layer built into every Torq AI SOC Platform. Every analyst confirmation and verdict redirection feeds back into a dedicated, per-tenant model that continuously trains on your human intelligence. The Torq SOC Brain, and in turn, Torq Auto Triage, accumulates your SOC team’s judgment over time and gets more accurate with each case your analysts work on.
The Torq SOC Brain is made up of three underlying technologies:
Torq Recall: Retrieves relevant historical cases using deterministic matching on security observables, ranks them by relevance, then analyzes how past analysts’ decisions should influence the current verdict.
Torq Reflex: Learns your organization’s unique approach to risk, evidence, and decision-making while continuously training on your team’s confirmed verdicts to improve accuracy over time.
Torq Retrospect: Imports resolved incidents from existing security tools, making years of organizational knowledge immediately available and informing accurate verdict decisions starting on day zero.
As a result, Torq Auto Triage accuracy scores improve from roughly 94% to 99% in a matter of weeks, so the longer it runs, the more it becomes your own SOC intelligence model.
Torq Auto Triage is The Front Door, The AI SOC is What’s Behind It
Torq’s agentic Auto Triage delivers its full value when verdicts flow directly into the Torq AI SOC Platform — intelligent case management, containment agents, and autonomous incident response.
The investigations are more precise because the triage verdict was accurate and documented in the Torq Context Graph. The response is faster because Socrates and Torq HyperAgents have the full scope of the threat and the historical justification to back it up. The agentic decisions are validated and trusted because they all trace back to the same learning powered by the Torq SOC Brain.
Triage solutions that filter false positives and escalate everything else are stuck in their old ways. Torq Auto Triage takes it further — with every alert garnering the attention it deserves, every verdict improving the system over time, and every case fully ready for the escalation, containment, or response that comes next.