Automating Data Leakage Response: Beyond Traditional DLP

Contents

Get a Personalized Demo

See how Torq harnesses AI in your SOC to investigate, prioritize, and respond to threats faster.

Request a Demo

TL;DR

  • Data leakage is the unintentional or malicious exposure of sensitive information, and traditional DLP tools alone leave significant gaps in detection and response.
  • Leakage risks span human error, misconfigurations, insider threats, and sophisticated exfiltration across cloud, email, and endpoint environments.
  • Detection requires cross-system visibility, behavioral anomaly monitoring, and automated enrichment that legacy tools struggle to deliver at scale.
  • The Torq AI SOC Platform automates data leakage detection, triage, and response workflows, cutting alert fatigue and accelerating containment.
  • No-code automation and 300+ out-of-the-box integrations let SOC teams build and deploy leakage response playbooks without engineering overhead.

Data leakage has a way of hiding in plain sight. It shows up in a misconfigured S3 bucket, an employee forwarding sensitive files to a personal email, an overly permissive API, or a third-party integration that quietly exposes more data than it should. By the time a traditional data loss prevention (DLP) tool flags it, the exposure has often been active for hours, days, or longer.

For SOC teams managing complex, multi-cloud environments, fast detection and even faster response both matter. This article covers what data leakage is, the risks it creates, how to detect and prevent it, and how automated workflows transform response from a reactive scramble into a coordinated, autonomous operation.

Understanding Data Leakage

What Is Data Leakage?

Data leakage is the unauthorized or unintentional exposure of sensitive, confidential, or protected information to parties who should not have access to it. It differs from a data breach in an important way: a breach typically involves a deliberate attack by a malicious actor, while leakage often results from human error, misconfiguration, or overly permissive controls that create exposure without anyone intending it.

That distinction matters operationally. Detection and response strategies built around known attack patterns miss the leakage scenarios that originate inside the organization. Information leakage in enterprise environments spans a wide range: sensitive documents shared with the wrong distribution list, API keys embedded in public code repositories, cloud storage buckets left open to the internet, or employee credentials exposed through third-party breaches.

Traditional DLP tools address a portion of this risk by scanning for sensitive data patterns and blocking certain outbound transfers. The coverage gap emerges in the scenarios DLP was not designed for: lateral movement between internal systems, exfiltration through authorized channels, or leakage that occurs at the infrastructure layer rather than the application layer. Closing that gap requires a broader detection strategy and automated response that operates across your full security stack.

Types and Models of Leakage

Data leakage takes several forms depending on the source, the mechanism, and whether the exposure is intentional.

Unintentional leakage accounts for the majority of incidents. Employees misdirect emails, misconfigure cloud storage permissions, or unknowingly install software that exfiltrates data in the background. Misconfigurations in IAM policies, network segmentation, or cloud resource settings create persistent exposure that may go undetected for extended periods.

Malicious insider leakage involves a trusted employee or contractor deliberately exfiltrating sensitive data, often using authorized channels and access that DLP tools are configured to allow. Detection requires behavioral baselines and anomaly monitoring rather than simple policy enforcement.

Third-party and supply chain leakage occurs when vendors, partners, or integrated services handle sensitive data with weaker controls than your own environment enforces. A single over-permissioned API integration can expose more data than a targeted attack.

In machine learning and AI development contexts, model leakage (also called data leakage in ML) refers to a separate but related problem: training data or target information bleeding into model evaluation in ways that inflate performance metrics and produce unreliable models. For security teams building AI-powered detection systems, model leakage undermines the validity of the models they rely on. Rigorous data pipeline controls are an operational security concern and a data science discipline.

Common Risks and Impacts

Data leakage creates risk across three dimensions that matter directly to security architects and operations analysts.

Regulatory exposure is immediate and quantifiable. GDPR, HIPAA, PCI DSS, and CCPA all impose notification requirements and potential penalties when personal or sensitive data is exposed. The timeline from discovery to regulatory notification is often measured in days, and organizations that lack automated detection and evidence collection consistently struggle to meet it. Security incident categories that involve personal data carry the most acute regulatory consequence.

Operational disruption compounds the initial exposure. A leakage event that requires manual investigation across dozens of systems pulls analyst time away from active threats, creates a backlog in the alert queue, and often surfaces secondary findings that extend the response timeline significantly. SOC teams without automated enrichment and triage workflows face a compounding workload effect when leakage events coincide with other active incidents.

Reputational and financial damage follows discovery, whether the organization discovers the leakage internally or learns about it from an external reporter or regulator. The cost of a data breach extends across immediate remediation, customer notification, legal fees, and the longer-term erosion of trust that affects enterprise relationships and sales cycles.

The common factor across all three risk dimensions: speed of detection and response determines the magnitude of impact. Every hour a leakage event goes unaddressed expands the potential exposure.

Detection and Prevention Strategies

Data Leakage Detection Tools and Methods

Effective data leakage detection requires visibility across the full data path: where sensitive data lives, how it moves, who accesses it, and whether that access matches established behavioral patterns.

Traditional DLP tools provide a foundation by scanning outbound traffic and cloud storage for sensitive data patterns like credit card numbers, Social Security numbers, or proprietary document formats. They work well for known data types moving through monitored channels. The detection gaps emerge at the edges: encrypted traffic, authorized channels used for unauthorized transfers, and data that has been transformed to avoid pattern matching.

Advanced SOC detection approaches layer behavioral anomaly monitoring on top of DLP coverage. Rather than matching data patterns, behavioral detection establishes baselines for how users and systems normally interact with sensitive data, then flags deviations. An employee who downloads 10 times their normal weekly volume of files on a Friday afternoon triggers an anomaly alert regardless of whether the files match a DLP signature.

Torq Socrates™, Torq’s agentic SOC orchestrator, brings AI-powered reasoning to data leakage detection. Socrates evaluates alerts across connected systems, correlates signals indicating leakage activity, and autonomously initiates investigation workflows. When an email gateway flags a large outbound attachment, Socrates cross-references the sender’s recent access history, the sensitivity classification of the attached files, and any concurrent anomalies on the same user account. The result is a contextualized, investigation-ready alert rather than a raw signal requiring manual lookup.

Torq’s automated SOC incident response capabilities extend detection into case management: when a leakage event is confirmed, Torq automatically opens a case, assigns it to the appropriate team, and populates it with the full evidence trail gathered during investigation. Analysts arrive at a case that is already enriched and ready for decision-making.

These detection strategies represent a significant improvement over DLP alone, and they share one challenge: without automation, they still require substantial manual effort to operationalize at scale. The next section covers how automated workflows close that gap.

Prevention Best Practices

Prevention operates at several layers simultaneously. The most effective programs combine technical controls, policy enforcement, and automated monitoring into a defense-in-depth posture that addresses both unintentional and malicious leakage vectors.

Access control is the most foundational prevention layer. Applying the principle of least privilege across cloud resources, internal systems, and third-party integrations limits the blast radius when credentials are compromised or an insider acts maliciously. Automated non-human identity security and regular access reviews ensure that permissions reflect current need rather than accumulating over time.

Encryption of sensitive data at rest and in transit ensures that exposure due to misconfiguration or interception does not directly result in readable data loss. Encryption controls work in combination with DLP and behavioral monitoring: they reduce the value of data that leaks, while detection controls reduce the likelihood that leakage occurs undetected.

Proactive workflow automation fills the gaps left by manual processes. Torq Hyperautomation™ continuously monitors connected systems for misconfigurations, permission drift, and anomalous access patterns that precede leakage events. When a cloud storage bucket is created with public access enabled, or when an API key is committed to a code repository, Torq detects the exposure and triggers a remediation workflow immediately, before the window of vulnerability extends.

No-code automation makes these workflows accessible to security architects and operations analysts without requiring custom development. Torq’s drag-and-drop workflow builder lets teams configure, test, and deploy leakage prevention playbooks rapidly and adapt them as environments and threat patterns evolve.

Automating Response to Data Leakage Events

Real-Time Response Workflows

Speed is the defining variable in data leakage response. The difference between a contained incident and a material breach often comes down to whether response actions (access revocation, session termination, data quarantine, stakeholder notification) execute in minutes or hours.

Torq HyperAgents™ enable real-time response across email, cloud storage, endpoint, and identity environments simultaneously. HyperAgents is built to execute multi-step response workflows autonomously the moment a leakage event is confirmed: revoking the affected user’s access, quarantining flagged files, capturing a forensic evidence snapshot, notifying the security team, and opening a case management record with full incident context attached.

This response architecture addresses the coordination overhead that slows manual response. Rather than an analyst manually working through a runbook across five different consoles, Torq executes the full response sequence in parallel, with each action logged and auditable. The analyst’s role shifts from execution to oversight and decision-making on the escalated findings that require human judgment.

Agentic AI makes response workflows adaptive. When an investigation surfaces unexpected context, such as a leakage event that appears connected to a broader credential compromise, Socrates dynamically adjusts the response scope, expanding the investigation and response actions to cover the full extent of the incident.

Integrating Across Tools

Data leakage spans every layer of the enterprise environment: email systems, cloud storage, endpoint devices, identity providers, code repositories, SaaS applications, and network infrastructure. Effective detection and response require coordinated action across all of them, which is why point solutions with limited integration coverage consistently leave gaps in detection.

Torq’s Hyperautomation platform provides 300+ out-of-the-box integrations across the security tool ecosystem, including DLP platforms, SIEM, CASB, EDR, IAM, and cloud providers, allowing SOC teams to build unified leakage detection and response workflows without custom API development. When your email security platform, cloud access security broker, and endpoint detection tool all feed into a single automated workflow, correlation happens at machine speed.

Integration depth also reduces vendor sprawl. Teams that consolidate leakage detection and response orchestration through Torq replace point-solution complexity with a single automation layer that connects existing investments rather than adding new tools. That architectural simplicity translates directly into lower maintenance overhead, faster onboarding for new team members, and measurable KPI improvement on detection and response time metrics.

For teams building or expanding their detection coverage, Torq’s agentic coding for SecOps capabilities extend workflow customization further, letting security engineers build and iterate on automation logic rapidly without leaving the Torq environment.

Automate the Gap Between Detection and Containment

Data leakage is too fast, too varied, and too consequential to manage with manual triage and static DLP policies. The organizations that are able to contain leakage events quickly, share one operational characteristic: automated workflows that detect, enrich, and respond across the full data environment without waiting for analyst intervention.

Torq’s AI SOC Platform gives SOC teams the automation layer to close the gap between detection and containment, reduce alert fatigue from leakage-related false positives, and maintain a defensible, auditable response posture across every environment where sensitive data lives.

The AI SOC Apocalypse is underway. Data leakage is exactly the kind of fast-moving, cross-system threat that exposes the limits of manual SOC operations. The organizations closing that gap are doing it with agentic AI and automated response workflows. Torq is the only true AI SOC platform built to detect, investigate, and contain threats like data leakage at machine speed, across every environment where your sensitive data lives.

If your security program still depends on analysts to catch what automation should be stopping, the AI SOC Apocalypse has already started for you.

FAQs

What is data leakage in cybersecurity?

Data leakage is the unintentional or unauthorized exposure of sensitive, confidential, or protected information to parties outside its intended audience. It differs from a deliberate data breach in that leakage often results from human error, misconfiguration, or overly permissive controls rather than an external attack. Common examples include misconfigured cloud storage, misdirected emails containing sensitive attachments, exposed API keys, and over-permissioned third-party integrations. Leakage events can carry the same regulatory and reputational consequences as breaches, making detection and rapid response critical. Learn how Torq automates data leakage incident response workflows.

What are the types of data leakage?

Data leakage falls into three broad categories. Unintentional leakage results from human error or misconfiguration, including misdirected emails, public cloud storage buckets, or credentials committed to code repositories. Malicious insider leakage involves a trusted user deliberately exfiltrating data through authorized channels, often in ways that standard DLP policies allow. Third-party leakage occurs when vendors or integrated services expose data through weaker controls than the organization enforces internally. Each type requires different detection approaches: pattern matching for known data types, behavioral anomaly detection for insider activity, and vendor risk monitoring for supply chain exposure. Explore how security incident categories inform response prioritization across leakage types.

What is information leakage in cybersecurity?

Information leakage in cybersecurity refers broadly to any unintended disclosure of sensitive data, including system configuration details, network topology, application error messages, and personal or business-critical information. At the application layer, information leakage can expose details that attackers use to refine subsequent attacks: stack traces that reveal software versions, verbose error messages that disclose internal path structures, or API responses that return more data than the requesting user should see. At the enterprise level, information leakage encompasses the broader category of data exposure events that create regulatory, operational, and reputational risk.

Does a data leak mean I was hacked?

A data leak and a hack are related but distinct events. A hack involves an external attacker deliberately breaching your systems to steal data. A data leak can occur without any external attack: a misconfigured server, an employee error, or an overly permissive access control can expose sensitive data without any malicious actor involved. That said, data leaks create the conditions that make successful attacks more likely. Exposed credentials, visible system configurations, or accessible sensitive data all lower the cost and complexity of a subsequent targeted attack. Detecting and remediating leakage events promptly reduces both the immediate exposure and the downstream attack surface. See how Torq’s high-security automation workflows support proactive leakage detection and remediation.

SEE TORQ IN ACTION

Ready to automate everything?

“Torq takes the vision that’s in your head and actually puts it on paper and into practice.”

Corey Kaemming, Senior Director of InfoSec

“Torq offers unprecedented protection and drives extraordinary efficiency for RSM and our customers.”

Todd Willoughby, Director

Compuquip logo in white

“Torq saves hundreds of hours a month on analysis. Alert fatigue is a thing of the past.”

Phillip Tarrant, SOC Technical Manager

Fiverr logo in black

“The only limit Torq has is people’s imaginations.”

Gai Hanochi, VP Business Technologies

Carvana logo in black

“Torq Agentic AI now handles 100% of Carvana’s Tier-1 security alerts.”

Dina Mathers, CISO

Riskified logo in white

“Torq has transformed efficiency for all five of my security teams and enabled them to focus on much more high-value strategic work.”

Yossi Yeshua, CISO

AI Security and Trust: Why SOC Teams Don’t Trust AI

Contents

Get a Personalized Demo

See how Torq harnesses AI in your SOC to investigate, prioritize, and respond to threats faster.

Request a Demo

92% of security leaders say something is actively reducing their trust in AI within the SOC. These aren’t skeptics, they’re people who have already adopted AI and believe in its ability to enhance security operations. We know from the 2026 AI SOC Leadership Report that AI is already widely adopted in the SOC, with 94% of organizations using it in some capacity. 

And yet, there’s still an AI security and trust gap in the SOC. Why?

Confidence Isn’t the Issue. Deployment Is. 

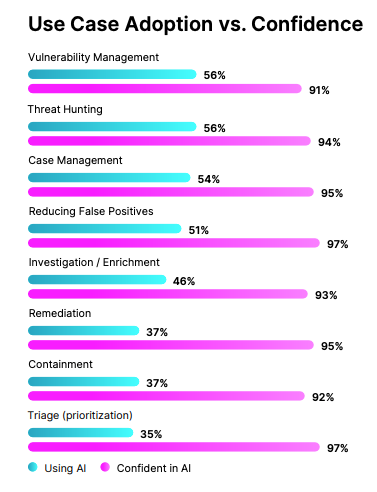
Digging into the data from Torq’s AI SOC Leadership Report, one gap stood out as the most shocking. Across every SOC use case we measured, confidence in AI’s ability to get the job done is nearly universal, ranging from 91% to 97%. CISOs and security leaders aren’t sitting around debating whether AI can handle the work; they know it can. But actual adoption tells a different story.

Vulnerability management and threat hunting lead AI adoption metrics at 56% each. Followed by case management, reducing false positives, investigation, and remediation. What was surprising is that triage is the least deployed AI use case, with only 37% adoption — even though triage is arguably the most obvious fit for AI. SOC teams are overwhelmed with massive amounts of false-positive–riddled alerts, making triage one of the most repetitive and time-consuming tasks analysts face. 

If the use case best suited for AI in the SOC is the one organizations have been slowest to adopt, what does that say?

When we dove deeper into each use case, the responses helped pinpoint exactly what challenges SOC teams were experiencing that led to the adoption vs. confidence gap. The top response for triage was the need for too much human review (34%); for investigation, manual enrichment (32%) and unreliable conclusions (31%) were neck and neck; and for response, the most common answer was lack of trust (33%).  

It’s not a capability problem. It’s a lack of trust in the products themselves. 

What’s Actually Reducing Trust in AI?

When we asked 450 CISOs and security leaders this question, the answers weren’t what you might expect (or maybe they were, given how universal they were). Nobody led with “I’m worried that AI will take my analysts’ jobs” or “I’m not comfortable with the idea of autonomous remediation”. These are the answers other vendors are telling you to have, but the reality is, the top concerns were far more fundamental than that, and included: 

  1. Data privacy concerns: 45%
  2. False negatives (missed threats): 40%
  3. Data governance: 37%
  4. Black-box AI: 32%

Looking at these four top concerns together paints a pretty clear picture. Security leaders aren’t questioning whether or not AI works; they’re asking:

  • What data is AI accessing? 
  • What is AI doing with that data? 
  • Why is AI making the decisions it’s making? 

When we break down the responses by seniority level, the story remains the same. The top concerns surrounding AI in the SOC were:

  • Executives: False negatives 
  • VPs: Data privacy
  • Directors: Black-box AI
  • Senior Managers: Loss of control

These responses aren’t contradictory;they’re all expressions of the same need: visibility and control at every level. 

What Would Build Confidence in AI in the SOC? 

We asked what was reducing trust in AI, so it only made sense to ask what would build that confidence too and the answers were just as telling. 

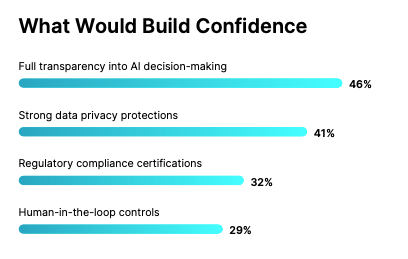
Security teams aren’t looking for less AI; they are looking for more visibility into the AI they already have. They want to understand the planning and reasoning that goes into agentic execution. They want to be able to report to their executives that the AI solutions they’ve invested in are protecting their data and meeting their organization’s unique regulatory and compliance requirements. 

And most importantly, they want to maintain the flexibility of human-in-the-loop control. Not human intervention at every step, but the ability to control and customize where and when human analysts should step in, either as overseer or final decision maker. High-severity incident with a critical system on the line? Humans make the call. Low-severity, high-confidence attack pattern? AI handles end-to-end.

Rearchitecting AI for Security and Trust

90% of security leaders say that explainable AI decisions are critical to a true AI SOC platform. The current gap between confidence and deployment exists because too many AI SOC solutions can’t provide the type of transparency that builds trust. As a result, SOC teams are spending their time double-checking AI decisions, doubling the work, and not realizing the time savings that AI in the SOC was intended for. 

A true AI SOC platform needs to inherently answer the simple questions that SOC teams are asking — what tools is the AI accessing, what data is the AI looking at, and why did the AI reach the conclusion it did? Until those questions have clear, verifiable answers built into the platform architecture, the ceiling on AI expansion in the SOC isn’t the technology. It’s trust. 

What Transparent AI Looks Like

The Torq AI SOC Platform was built with these concerns in mind. We understand the importance of transparency in building trust in human-AI collaboration. Here’s how the Torq AI SOC Platform addresses each one directly. 

Declarative instruction: Torq HyperAgents™ work under your explicit direction. You give each agent a role, an objective, behavioral guidelines, and specific instructions. You define the tools that they can use (as broadly as a workflow or as granularly as a single step), the data they can access, and the decisions they are authorized to make. Control is built in from the start, not bolted on as an afterthought. 

AI reasoning and output visibility: Every agentic action is documented in a transparent timeline view that maps the reasoning leading to each execution. Analysts aren’t left guessing why a verdict was reached, or what evidence supports a specific conclusion. The planning, reasoning, and execution are reviewable and structured for human validation — in real time — with manual override always available. 

Immutable audit logs: Every AI decision, action, and reasoning chain is recorded and uneditable. Not just for compliance purposes, but because auditability is what builds trust in AI across the organization. When a CISO asks “What did the AI do, and why?”, the answer is already written, traceable, and defendable.

Human-AI collaboration: Torq Socrates coordinates the full platform, with humans on the loop by design. Response actions can execute completely autonomously for high-volume, high-confidence scenarios or with human-in-the-loop confirmation when severity or business context demands it. Analysts set the boundaries and build in off-ramps for human intervention, while Socrates documents and learns over time. As confidence in AI grows, SOC teams can grant greater autonomy across day-to-day use cases. Trust is earned, after all. 

The Confidence SOC Teams Need

The #1 confidence booster in A isn’t more features or better algorithms — it’s transparency. Show how AI reached its decisions, and teams will trust it more. Give them the ability to dial autonomy based on context, and they’ll grant more of it.  AI security and trust come down to architecture, not marketing. A true AI SOC platform is built for trust from the inside out.

For more on how the Torq AI SOC Platform is the only enterprise-ready AI SOC that security leaders can actually trust, check out the complete blog series below. 

SEE TORQ IN ACTION

Ready to automate everything?

“Torq takes the vision that’s in your head and actually puts it on paper and into practice.”

Corey Kaemming, Senior Director of InfoSec

“Torq offers unprecedented protection and drives extraordinary efficiency for RSM and our customers.”

Todd Willoughby, Director

Compuquip logo in white

“Torq saves hundreds of hours a month on analysis. Alert fatigue is a thing of the past.”

Phillip Tarrant, SOC Technical Manager

Fiverr logo in black

“The only limit Torq has is people’s imaginations.”

Gai Hanochi, VP Business Technologies

Carvana logo in black

“Torq Agentic AI now handles 100% of Carvana’s Tier-1 security alerts.”

Dina Mathers, CISO

Riskified logo in white

“Torq has transformed efficiency for all five of my security teams and enabled them to focus on much more high-value strategic work.”

Yossi Yeshua, CISO

How to Choose the Best API Automation Tool for Your Security Team

Contents

Get a Personalized Demo

See how Torq harnesses AI in your SOC to investigate, prioritize, and respond to threats faster.

Request a Demo

TL;DR

  • API automation tools handle testing, integration, and orchestration across your security stack — reducing manual work and accelerating response.
  • For SOC teams, the right tools connect every platform in your environment and keep those connections validated and running.
  • Tools like Postman, SoapUI, and Apache JMeter each cover specific testing needs — and the Torq AI SOC Platform ties them into unified, automated security workflows.
  • The next frontier in API automation is agentic AI: systems that test APIs and act on them autonomously to contain threats in real time.

Security teams today manage hundreds of integrations from tools like SIEMs, EDR platforms, ticketing systems, threat intelligence feeds, cloud environments, and more. Every one of those connections runs on APIs. Every API that goes untested, unmonitored, or manually managed is a gap in your security posture.

API automation tools close that gap. They handle testing, orchestration, and integration at a speed and scale that empowers modern SOC teams to stay ahead of threats and operate with real confidence.

This article covers what API automation tools are, why they matter for IT and security operations, how to evaluate the leading options, and how the Torq AI SOC Platform extends API automation into full agentic SOC orchestration.

What Are API Automation Tools?

API automation tools are software platforms or frameworks that automatically execute, validate, monitor, and integrate API-based interactions, without any manual intervention required for each task.

In a traditional IT or development context, that means running automated test suites against endpoints, validating responses, and generating reports. In a security context, it means something more powerful: connecting disparate tools, triggering automated responses to threats, and orchestrating complex multi-step workflows across your entire stack.

API requests form the connective tissue of modern security infrastructure. Every time your SIEM fires an alert, your ticketing system logs an incident, or your threat intelligence platform flags an indicator of compromise, APIs carry that data between systems. Automating how those requests are handled — the testing, validation, routing, and response — transforms a reactive security team into a proactive one.

Software API testing tools generally fall into four categories:

  • Functional testing tools that validate APIs return correct responses under expected conditions
  • Performance testing tools that measure speed, throughput, and behavior under load
  • Security testing tools that probe APIs for vulnerabilities, misconfigurations, and unauthorized access vectors
  • Integration and orchestration platforms that connect APIs across tools and automate end-to-end workflows

Security teams need all four and increasingly, they need them unified under a single automation layer.

Key Benefits of Using API Automation in Security Workflows

Improved Efficiency and Scalability

Manual API management doesn’t scale. A growing enterprise SOC can easily manage 50 to 100+ integrated tools, each exposing dozens of API endpoints. Testing and monitoring those connections by hand consumes engineering hours that should be spent on higher-value security work.

API automation tools let teams scale testing and monitoring across every integration simultaneously. When you add a new tool to your stack, automated security workflows validate its API connections, check for expected behavior, and flag anomalies — all without analyst intervention. That scalability compounds over time: the larger your stack grows, the more value automation delivers.

Enhanced Accuracy and Reduced Risk

Misconfigured API endpoints are a real and underappreciated attack surface. An overly permissive authentication scope or an untested edge case in an API response can create vulnerabilities that go undetected for months. Automated testing catches those issues at the point of integration, before they reach production.

Automated testing also reduces alert fatigue from false positives. When your incident response automation relies on clean, validated API data, analysts spend time on genuine threats instead of chasing noise. Consistent, repeatable test execution means the same checks run every time, with full coverage and reliable results.

Faster Integration and Deployment

Security teams operate in a vendor ecosystem that never stops changing. New tools enter the stack, existing tools release API updates, and threat landscapes shift in ways that demand rapid workflow adjustments. API automation tools accelerate that cycle by automatically handling integration validation.

When your automation layer can test a new integration and confirm it’s working correctly in minutes, your team stays agile. Connecting tools to your security stack becomes a low-friction process, and your workflows update in real time as your environment evolves.

API Automation With Torq AI SOC Platform

The Torq AI SOC Platform approaches API automation from a security operations perspective. Torq Socrates™, Torq’s agentic SOC orchestrator, builds, monitors, and maintains API integrations across any security solution, using these API connections to orchestrate workflows across your entire security stack — SIEM, EDR, ticketing, threat intelligence, and beyond. 

Torq Socrates’ Agentic Builder lets analysts use natural language to build and modify API-driven Torq HyperAgents™ without engineering support.Rather than validating whether an API works, Torq uses APIs as the foundation for automated security work. When an alert fires, Torq HyperAgents autonomously gather context from multiple API sources, evaluate the threat, and execute a response — without waiting for analyst intervention. Torq HyperAgents are built to handle the speed and complexity that modern SOC environments demand.

Torq Socrates goes further by reasoning across API-connected data sources to make intelligent decisions about alert triage, investigation priority, and response actions. Socrates adapts to the specifics of each incident — pulling data from the right APIs at the right time — rather than following a fixed playbook.

Torq Hyperautomation™ is the engine that powers containment, remediation, and response action through API driven flows. By leveraging the vast network of APIs, Torq provides security teams with a full AI-driven SOC orchestration platform — covering end-to-end threat detection and response, from integration validation to autonomous action.

How to Implement API Automation in Your Security Operations

Moving from manual API management to full automation is a process. These five steps give security teams a structured path forward.

1. Audit Your Current Integrations

Start with a complete inventory of every API connection in your security stack. Map which tools connect to which, what data they exchange, and how those connections are currently tested and monitored. This audit surfaces gaps — integrations without test coverage, endpoints that haven’t been validated recently, and connections carrying sensitive data without proper authentication controls. Your incident response plan is a useful reference for identifying which integrations are most critical to your response workflows.

2. Define Your Automation Objectives

API automation can serve several goals: reducing manual testing effort, accelerating incident response, improving integration reliability, or enabling agentic AI workflows. Prioritize based on where your team spends the most time and where failures carry the most impact. SOC teams typically find the highest immediate value in automating alert enrichment and incident triage workflows.

3. Select Tools Matched to Your Use Cases

Match tools to objectives using the framework above. Pure testing needs fit tools like Postman, SoapUI, or JMeter. Orchestration and workflow automation across your full security stack calls for a platform like Torq. Many teams run both layers: testing frameworks for integration validation, and an orchestration platform for operational automation. Explore Torq’s integration library to see how your existing stack maps to available connectors.

4. Build and Test Incrementally

Start with two or three high-priority integrations rather than attempting to automate everything at once. Build your first automated workflows, validate their outputs against expected behavior, and refine before expanding. Automated SOC incident response workflows benefit from this incremental approach — test each step before connecting them end-to-end.

5. Measure and Iterate

Define success metrics before you go live: mean time to detect, mean time to respond, analyst hours saved, and false positive rate. Measure against those baselines after implementation and use the data to guide the next round of automation. API automation compounds in value over time — each new automated workflow frees capacity for the next one. Check out Torq’s guide to security incident categories to help prioritize which response workflows to automate first.

Your Security Stack Deserves Better Than Manual

API automation tools are foundational infrastructure for modern security operations. They eliminate the manual overhead of managing hundreds of integrations, accelerate testing and deployment cycles, and enable the real-time orchestration that today’s threat landscape demands.

The right stack combines purpose-built testing frameworks for integration validation with a full orchestration platform for operational automation. The Torq AI SOC Platform brings both together — giving security teams the connectivity to link every tool in their stack and the agentic AI capabilities to act on what those connections reveal.

The AI SOC Apocalypse is already here. Security teams that automate their API workflows, integrate their toolchains, and deploy agentic AI are ahead. 

Are you ready to see what’s reshaping how enterprise security leaders think about AI, automation, and the future of the SOC?

FAQs

Does API testing need coding?

Modern API testing platforms are built for accessibility. Tools like Torq’s agentic workflow builder let security analysts build and run API tests and automation without writing code. Torq’s customizable automation and workflow builder makes API-driven workflow building available to analysts at every technical level.

What are the two types of API testing?

The two primary categories are functional testing — validating that an API returns correct responses under expected conditions — and non-functional testing, which covers performance, security, and reliability. Security testing of APIs (checking authentication, authorization, input validation, and vulnerability exposure) falls under non-functional testing and is especially critical for SOC teams managing complex integrations.

Is API testing the same as automation testing?

API testing and automation testing are related but distinct. API testing specifically validates the behavior of API endpoints. Automation testing is a broader category — it means using software to execute tests automatically rather than manually. API automation testing is the intersection: using automated tools to run API tests without manual execution. In a security context, API automation extends beyond testing to include orchestrating workflows and triggering automated responses across integrated tools.

How do I choose an API testing tool?

Start by identifying your primary use case: functional testing, performance testing, security scanning, or full workflow orchestration. Evaluate tools against your team’s technical skill level (some require coding, others offer low-code interfaces), your integration requirements, and your scalability needs. For security teams, look for tools that connect with your existing SOC stack and support the automated incident response workflows your analysts depend on. A platform like Torq addresses the orchestration layer that pure testing tools don’t cover.

What are examples of API-based automation in security?

Common examples include automated alert enrichment (pulling threat intelligence data via API when an alert fires), automated ticket creation in systems like Jira or ServiceNow when incidents are detected, automated containment actions (isolating endpoints or blocking IPs via EDR APIs), and automated case management. Torq’s case management capabilities and HyperAgents execute these workflows autonomously, reducing mean time to respond across the full security incident lifecycle.

What is the role of agentic AI in API automation for security?

Agentic AI takes API automation from rule-based execution to intelligent, adaptive response. Rather than following a fixed script, an agentic AI SOC platform like Torq — powered by Socrates, Torq’s agentic SOC orchestrator — reasons across API-connected data sources in real time, decides which actions to take based on the specifics of each incident, and executes multi-step response workflows autonomously. This is where modern AI SOC platforms are headed: APIs as the foundation, agentic AI as the decision layer on top.

SEE TORQ IN ACTION

Ready to automate everything?

“Torq takes the vision that’s in your head and actually puts it on paper and into practice.”

Corey Kaemming, Senior Director of InfoSec

“Torq offers unprecedented protection and drives extraordinary efficiency for RSM and our customers.”

Todd Willoughby, Director

Compuquip logo in white

“Torq saves hundreds of hours a month on analysis. Alert fatigue is a thing of the past.”

Phillip Tarrant, SOC Technical Manager

Fiverr logo in black

“The only limit Torq has is people’s imaginations.”

Gai Hanochi, VP Business Technologies

Carvana logo in black

“Torq Agentic AI now handles 100% of Carvana’s Tier-1 security alerts.”

Dina Mathers, CISO

Riskified logo in white

“Torq has transformed efficiency for all five of my security teams and enabled them to focus on much more high-value strategic work.”

Yossi Yeshua, CISO

SOC Automation Framework: How Agentic AI Powers the AI SOC

Contents

Get a Personalized Demo

See how Torq harnesses AI in your SOC to investigate, prioritize, and respond to threats faster.

Request a Demo

TL;DR

  • Agentic AI is the engine that powers every stage of the threat lifecycle from triage to resolution.
  • A five-step AI SOC automation framework gives SOC directors a practical, structured path to faster, smarter security operations.
  • Customers running on the Torq AI SOC Platform have seen 100% of Tier 1 cases auto-triaged (Carvana) and phishing responses drop from hours to minutes (Lennar Corp).
  • Academic research published in April 2026 independently validated this same architectural direction — agentic detection, enrichment, and resolution — confirming what leading SOCs are already running in production.

The best SOCs in 2026 resolve alerts before most teams have finished triage. Agentic AI makes that possible — handling the full threat lifecycle with transparent reasoning and documented action at every step, so analysts spend their time on the work that actually requires human judgment.

The Torq AI SOC Platform was built around exactly this architecture. Results from customers like Carvana and Lennar Corp show what it looks like in production.

What’s Driving the Shift Toward AI SOC Automation

SOC teams have more tools than ever. That’s part of the challenge. According to the 2026 AI SOC Leadership Report, 80% of security leaders say their SOC is still fragmented across too many platforms, which means analysts carry the burden of connecting context that the toolstack never hands them in one place.

Three forces are accelerating the need for a smarter SOC automation framework:

  • Threat volume has outpaced manual triage capacity. The alerts keep coming faster than any human team can process them at the pace attackers now operate.
  • Tool fragmentation places the burden of context on the analyst. When detection lives in one platform, enrichment in another, and response in a third, speed is the first casualty.
  • Agentic AI has matured to the point where it can handle reasoning and action — not just scripting. This is the shift that makes a true AI SOC automation framework possible.

Independent research is catching up to where leading SOCs already operate. In April 2026, researchers Md Hasan Saju and Akramul Azim published “Toward Autonomous SOC Operations”, a peer-reviewed framework for automating SOC operations that reduced average incident triage time from hours to under ten minutes using ensemble detection, retrieval-augmented investigation, and grounded automated resolution. The architecture the paper describes maps directly to what the Torq AI SOC Platform delivers.

What the Research Gets Right and What Real-World SOCs Still Need

The Saju and Azim paper achieved strong results under lab conditions:

  • 82.8% detection accuracy with a 0.120 false positive rate
  • Resolution code prediction accuracy improved from 78.3% to 90.0% with evidence-grounded reasoning
  • Average incident triage time reduced from hours to under 10 minutes

These numbers validate the architectural direction: ensemble detection, automated enrichment, and grounded resolution all belong in a modern SOC automation framework. What the research doesn’t address is what deployments actually require — integration breadth across thousands of tools, multi-tenant case management, compliance evidence packaging, transparent agentic reasoning that analysts can audit, and continuous learning that improves accuracy over time. That’s what the five-step framework below is built around.

A Practical AI SOC Automation Framework Powered by Agentic AI

The five-step AI SOC automation framework is a structured, repeatable approach to building SOC automation that actually closes cases rather than one that just moves alerts from one queue to another. Each step maps to a phase of the threat lifecycle, and each one is anchored by agentic AI working transparently alongside your team.

1. Ingest Detection Signals Across Every Layer of the Stack

Effective SOC automation starts with coverage. Endpoint, network, identity, cloud, email, and threat intelligence all need to feed into a single system — because gaps in ingestion mean gaps in detection. A framework that only sees part of the stack will only automate part of the problem. The more signal sources unified in one place, the more context an AI system has to make accurate decisions downstream. The Torq AI SOC Platform connects across 1,000+ native integrations, giving every subsequent step the full picture from the start.

2. Apply Agentic Triage With Transparent Reasoning

Not every alert is a threat. The triage layer needs to separate real incidents from noise — fast, at scale, and without burying critical signals under false positives. The strongest triage systems apply business context, known activity history, and threat intelligence together to produce a verdict that an analyst can actually trust and act on. Explainability matters here: if the system can’t show its work, the analyst can’t verify it. Torq Auto Triage does exactly this — an agentic engine that delivers verdicts with full reasoning surfaced at every step.

3. Auto-Enrich the Case With Grounded Evidence

Once a real threat surfaces, the investigation should move immediately, without waiting for an analyst to manually pull context from multiple tools. The system should automatically gather the evidence needed to understand scope: querying threat intelligence sources, cross-referencing internal activity, and assembling a complete picture before a human ever opens the case. The sooner the evidence package is ready, the sooner the right decision is made. Torq HyperAgents™ handle this enrichment layer, with specialized AI Agents that investigate and gather context across the full threat lifecycle — transparently and with full visibility into every action taken.

4. Resolve or Escalate With Documented Reasoning

Resolution is where most SOC automation frameworks leave room to grow. Getting to a verdict is one thing; taking the right action — or knowing when to hand off to a human — requires reasoning that’s both accurate and auditable. The system needs to surface what it found, what it recommends, and why, so the analyst reviewing it can approve with confidence. Escalations should carry full context, not just a ticket number. Torq Socrates™, Torq’s agentic SOC orchestrator, coordinates HyperAgents, generates a structured plan for analyst review, and executes only what’s been approved — keeping the human in the loop at every decision point that matters.

5. Close the Loop With Audit Trails and Continuous Learning

A framework that stops at resolution leaves the hardest operational problems unsolved. Production SOCs need every action logged for compliance (PCI DSS, SOX, GDPR), feedback mechanisms that improve accuracy over time, and case management that connects related incidents into a coherent picture. This is also where the business case gets built — the data that shows the board what automation is actually delivering. Torq Case Management and Torq Hyperautomation™ close this loop natively, packaging audit trails, linking related cases, and continuously tuning the system based on analyst feedback and resolved outcomes.

Step 5 is where deployments diverge from research frameworks. Lab results show what’s achievable. Compliance packaging, multi-tenant case management, and a system that gets smarter over time — that’s what makes automation sustainable at scale.

Real-World Outcomes From an Agentic AI SOC 

Torq customers are running the AI SOC today and the outcomes reflect what happens when agentic AI is applied across every step of the threat lifecycle.

Carvana: 100% of Tier 1 and Tier 2 cases are auto-triaged by the Torq AI SOC Platform. 

Lennar Corp: Phishing response dropped from hours to minutes after consolidating workflows on Torq. 

The research describes what’s possible. These outcomes prove it has been operational at scale and in production with real organizations.

A Five-Step Checklist for Evaluating Your SOC Automation Today

Use this checklist to assess where your current SOC automation stands against the framework:

  1. Audit detection signal coverage across endpoint, network, identity, cloud, email, and threat intelligence
  2. Confirm agentic triage capability — does business context, activity history, and threat intelligence apply together to every alert?
  3. Map automated enrichment paths — what percentage of cases receive full evidence packages without analyst effort?
  4. Evaluate resolution decision support — does the system surface verdicts with documented reasoning that the analyst can review and approve?
  5. Verify audit trails and feedback loops — does every action log for compliance, and does the system improve accuracy over time?

If the answer is “uncertain” on more than two of these, your SOC has the gaps that this AI SOC automation framework is designed to help close.

The Future is an Agentic AI SOC

The 2026 AI SOC Leadership Report covers how 450 security leaders are building toward AI SOC automation at scale — the tools they’re using, the outcomes they’re measuring, and the decisions that separate the leading SOCs from the rest.

Want the Data Behind AI SOC Automation?

FAQs

What is SOC automation?

SOC automation is the use of agentic AI and workflow orchestration to detect, investigate, and respond to security threats across an organization’s full technology stack — without relying on manual analyst effort for every step. Modern SOC automation goes beyond running scripted playbooks; it uses agentic AI that reasons and acts across the threat lifecycle, unified case management, and cross-stack orchestration that closes cases — not just moves them.

What does an AI SOC automation framework look like in practice?

An AI SOC automation framework ingests alerts from across the stack, applies agentic triage to determine severity with transparent reasoning, auto-enriches the case with grounded evidence from threat intelligence and internal sources, resolves or escalates with documented reasoning, and closes the loop with audit trails and continuous learning.

How does automation improve SOC efficiency?

Automation improves SOC efficiency by eliminating manual handoffs between detection, investigation, and response. Data shows the impact at scale: Carvana auto-triages 100% of Tier 1 and Tier 2 cases. Lennar Corp cut phishing response from hours to minutes.

What are the main challenges in security operations today?

The three biggest challenges in security operations today are tool fragmentation (80% of security leaders say their SOC is split across too many platforms), alert volume that exceeds manual triage capacity, and the difficulty of grounding AI outputs in trustworthy, auditable evidence.

How does agentic AI handle complex SOC investigations?

Agentic AI handles complex SOC investigations through a plan-and-execute model. Torq Socrates™, Torq’s agentic SOC orchestrator, reads the case, coordinates specialized HyperAgents™ to gather evidence and assess scope, generates a structured plan the analyst reviews, and executes only the approved actions — with full audit trails at every step. The result is agentic reasoning with human oversight at the decision points that matter.

What makes an AI SOC platform different from legacy security automation tools?

Legacy security automation tools execute predefined playbooks against known conditions. An AI SOC platform like Torq applies agentic AI that reasons across novel scenarios, adapts to new threat patterns, and takes action across the full threat lifecycle — from auto triage through case closure — with transparency at every step. For teams looking to go deeper on how Hyperautomation™ powers this approach, the Torq platform combines agentic AI with an enterprise-grade automation engine purpose-built for security operations teams.

SEE TORQ IN ACTION

Ready to automate everything?

“Torq takes the vision that’s in your head and actually puts it on paper and into practice.”

Corey Kaemming, Senior Director of InfoSec

“Torq offers unprecedented protection and drives extraordinary efficiency for RSM and our customers.”

Todd Willoughby, Director

Compuquip logo in white

“Torq saves hundreds of hours a month on analysis. Alert fatigue is a thing of the past.”

Phillip Tarrant, SOC Technical Manager

Fiverr logo in black

“The only limit Torq has is people’s imaginations.”

Gai Hanochi, VP Business Technologies

Carvana logo in black

“Torq Agentic AI now handles 100% of Carvana’s Tier-1 security alerts.”

Dina Mathers, CISO

Riskified logo in white

“Torq has transformed efficiency for all five of my security teams and enabled them to focus on much more high-value strategic work.”

Yossi Yeshua, CISO

Cloud Security Architecture: How to Design and Implement a Multi-Cloud Security Strategy

Contents

Get a Personalized Demo

See how Torq harnesses AI in your SOC to investigate, prioritize, and respond to threats faster.

Request a Demo

TL;DR

  • Cloud security architecture is the framework of policies, controls, and technologies that protect data, applications, and infrastructure across cloud environments
  • Multi-cloud adoption is accelerating; 87% of organizations run multi-cloud
  • The five pillars of modern cloud security architecture: identity and access management, network security, data protection, workload security, and continuous monitoring
  • Manual cloud security processes present opportunities for automation to reduce bottlenecks, alert fatigue, and response delays
  • Torq AI SOC Platform enables 75% faster alert processing, 90% duplicate alert reduction, and 60% faster cross-cloud MTTR

Cloud environments expand faster than security teams can protect them. Every new workload, every configuration change, and every API endpoint creates potential exposure. With organizations now operating across AWS, Azure, GCP, and hybrid environments simultaneously, the attack surface multiplies while visibility fragments.

This is the reality of modern cloud security architecture: complexity at scale, threats at machine speed, and security teams stretched thin trying to maintain consistent protection across distributed infrastructure.

This guide breaks down what cloud security architecture means in 2026, the core components every organization needs, the challenges that create opportunities for improvement in multi-cloud security strategies, and how AI-driven automation transforms cloud security operations into proactive defense.

What is Cloud Security Architecture?

Cloud security architecture is the comprehensive framework of policies, controls, technologies, and processes that protect cloud-based systems, data, and infrastructure. It defines how security integrates across every layer of your cloud environment, from identity and access management to network segmentation to data encryption to threat detection and response.

A well-designed cloud security architecture accomplishes three things:

  1. Protects assets: Safeguards data, applications, and infrastructure from unauthorized access, breaches, and attacks
  2. Enables compliance: Maintains adherence to regulatory requirements like SOC 2, PCI DSS, HIPAA, and GDPR across cloud platforms
  3. Supports business velocity: Allows development teams to move fast while managing risk appropriately

Cloud security architecture differs fundamentally from traditional on-premises security. Static perimeters dissolve. Workloads spin up and down in seconds. Data flows across regions and providers. Every cloud platform, whether AWS, Azure, or GCP, implements security controls differently, creating opportunities for unified approaches.

Five Pillars of Modern Cloud Security Architecture

Effective cloud security architecture rests on five interconnected pillars. Strength in each one builds a resilient security posture across the entire environment.

1. Identity and Access Management (IAM)

Identity is the new perimeter. In cloud environments, every access request, whether human or machine, requires verification. Strong IAM architecture includes:

  • Zero trust principles: Verify every access request regardless of source
  • Least privilege access: Grant minimum permissions required for each role
  • Just-in-time (JIT) access: Provide temporary elevated permissions only when needed
  • Multi-factor authentication (MFA): Require multiple verification factors for sensitive resources
  • Service account governance: Monitor and control machine-to-machine authentication

Identity threat detection and response becomes critical as organizations strengthen defenses against credential-based attacks.

2. Network Security

Cloud network security extends beyond traditional firewalls to encompass:

  • Micro-segmentation: Isolate workloads and limit lateral movement
  • Virtual private clouds (VPCs): Create logically isolated network sections
  • Security groups and network ACLs: Control inbound and outbound traffic
  • Web application firewalls (WAFs): Protect applications from common exploits
  • DDoS protection: Mitigate volumetric and application-layer attacks

3. Data Protection

Data protection in cloud environments requires encryption at rest and in transit, plus robust access controls:

  • Encryption management: Implement consistent encryption across cloud platforms
  • Key management: Maintain secure, auditable key lifecycle management
  • Data classification: Identify and protect sensitive data based on classification
  • Data loss prevention (DLP): Monitor and prevent unauthorized data exfiltration
  • Backup and recovery: Ensure data resilience across regions and providers

4. Workload Security

Protecting cloud workloads, including VMs, containers, and serverless functions, requires:

  • Cloud Security Posture Management (CSPM): Continuously monitor for misconfigurations
  • Cloud Workload Protection Platforms (CWPP): Secure runtime environments
  • Container security: Protect Kubernetes clusters and container images
  • Serverless security: Monitor and secure function-as-a-service deployments
  • Infrastructure as Code (IaC) scanning: Catch vulnerabilities before deployment

5. Continuous Monitoring and Response

Security visibility across cloud environments demands:

  • Centralized logging: Aggregate logs from all cloud platforms and services
  • Security Information and Event Management (SIEM): Correlate events and detect threats
  • Cloud-native detection: Leverage AWS GuardDuty, Microsoft Sentinel, GCP Security Command Center
  • Automated response: Orchestrate containment and remediation at machine speed
  • Compliance monitoring: Continuously verify adherence to security policies

Cloud Security Architecture Challenges

Building and maintaining cloud security architecture across multi-cloud environments is hard, and most of that difficulty is exactly what automation and unified tooling are built to solve.

Consolidating Alerts Across Clouds

Security alerts arrive from AWS Security Hub, MicrosoftSentinel, Google Cloud Security Command Center, and third-party tools. Each has unique formats, severity scales, and contextual data structures. This creates an opportunity for unified platforms that normalize and correlate alerts automatically.

Organizations operating in multi-cloud environments can achieve 75% faster alert processing with centralized correlation.

Improving Cross-Cloud Visibility

Multi-stage attacks can span AWS EC2, Azure VMs, and GCP instances. Unified correlation across cloud boundaries enables security teams to detect these attack patterns and respond comprehensively.

Accelerating Triage Through Automation

SOC teams invest significant time manually enriching alerts, correlating events, and determining response actions. Automation accelerates these processes, reduces analyst burnout, and enables faster threat response through automated SOC incident response.

Addressing Configuration Drift

Cloud misconfigurations are one of the most common causes of cloud breaches. Security groups, storage bucket permissions, and IAM configurations benefit from continuous monitoring and automated remediation across multi-cloud environments.

Streamlining Compliance

Maintaining compliance across multiple cloud platforms requires continuous monitoring, documentation, and remediation. Automation transforms compliance from a manual burden into a continuous, auditable process.

How Automation Transforms Cloud Security Architecture

Automation addresses manual process challenges and enables security teams to operate at the speed of cloud infrastructure. Cloud-native security automation delivers these capabilities:

Unified Multi-Cloud Alert Management

Modern cloud security architectures benefit from platforms that automatically ingest, normalize, and correlate security alerts from disparate cloud-native security tools. This provides centralized visibility and intelligent triage across your entire multi-cloud infrastructure.

Key capabilities include:

  • Real-time alert ingestion from AWS Security Hub, Microsoft Sentinel, GCP Security Command Center, and any of the cloud security tools in your stack.
  • Cross-platform correlation that reconstructs attack timelines across cloud boundaries.
  • Automatic deduplication that eliminates redundant alerts and reduces noise.
  • Normalized severity scoring that enables consistent prioritization regardless of source.

Automated Threat Response

Cloud-native response automation triggers coordinated containment actions across AWS, Azure, and GCP simultaneously:

  • Security group modifications
  • VM isolation
  • IAM policy enforcement
  • Cross-cloud network segmentation
  • Evidence collection and preservation

Continuous Compliance Automation

Automated compliance monitoring detects drift, generates audit-ready documentation, and implements corrective controls. This maintains adherence to SOC 2, PCI DSS, GDPR, HIPAA, and other frameworks across multi-cloud environments.

Torq for Cloud Security Operations

Torq for Cloud & AppSec teams delivers the automation layer that modern cloud security architecture requires. The Torq AI SOC Platform connects to major cloud platforms, container orchestrators, SIEMs, and application security tools, achieving complete visibility across hybrid and multi-cloud environments.

Torq helps enterprises detect and respond to security events at scale, instantly and precisely.

Multi-Cloud Event Ingestion

Torq connects to AWS, Azure, GCP, Kubernetes, Docker, and 300+ security tools using native APIs, webhooks, and streaming integrations. This eliminates visibility gaps and enables comprehensive threat detection.

Intelligent Alert Correlation

Cloud security events are correlated across infrastructure layers, from IaaS misconfigurations to container vulnerabilities to application-level threats. Torq Socrates™, Torq’s agentic SOC orchestrator, contextually enriches alerts, grouping them by resource and application for complete incident context.

Automated Remediation

Torq HyperAgents™ enable security teams to remediate threats in minutes. SOC analysts can assign incidents for autonomous remediation or collaborate in natural language for complex scenarios requiring human oversight.

Agentic Workflow Building

The Torq Agentic Builder empowers security teams to create and modify automation workflows using natural language, accelerating time to value and enabling continuous improvement of cloud security processes.

Measurable Results

Organizations using Torq for multi-cloud security operations achieve:

  • 75% faster alert processing
  • 90% duplicate alert reduction
  • 60% faster cross-cloud MTTR

Building Your Cloud Security Architecture: Key Considerations

When designing or modernizing your cloud security architecture, prioritize these elements:

  • Start with visibility: You cannot secure what you cannot see. Ensure comprehensive logging and monitoring across all cloud platforms, services, and workloads before implementing advanced controls.
  • Embrace automation early: Manual security processes create technical debt that compounds over time. Integrate automation into your cloud security architecture from the start, particularly for alert triage, enrichment, and routine response actions. Explore security automation workflow tools to accelerate your journey.
  • Design for multi-cloud reality: Even if you primarily use a single cloud provider today, architect for multi-cloud flexibility. Avoid vendor-specific implementations that create lock-in and limit future options.
  • Integrate security into DevOps: Cloud security architecture succeeds when security integrates into CI/CD pipelines, infrastructure as code, and development workflows. Agentic coding for SecOps enables security teams to build and modify automations at the speed of development.
  • Measure what matters: Track metrics that demonstrate security effectiveness: mean time to detect (MTTD), mean time to respond (MTTR), alert-to-case ratio, and compliance posture over time.

Cloud Security Architecture is a Continuous Process

Cloud environments evolve constantly. New services launch, workloads scale, attack techniques advance. Cloud security architecture requires continuous assessment, adaptation, and improvement.

The organizations that succeed treat cloud security as an ongoing operational discipline, powered by automation that scales with their infrastructure. 

The AI SOC Apocalypse manifesto explores how leading organizations are transforming their security operations for this new reality. 

Ready to modernize your cloud security architecture? 

FAQs

What is cloud security architecture?

Cloud security architecture is the comprehensive framework of policies, controls, technologies, and processes that protect cloud-based systems, data, and infrastructure across public, private, and hybrid cloud environments. Learn more about how security operations teams implement these frameworks.

What are the five pillars of cloud security architecture?

The five pillars are: identity and access management (IAM), network security, data protection, workload security, and continuous monitoring and response. Each pillar addresses critical aspects of protecting cloud environments and benefits from incident response automation.

How does multi-cloud security differ from single-cloud security?

Multi-cloud security requires unified visibility, correlation, and response across different cloud platforms (AWS, Azure, GCP), each with unique security controls, alert formats, and APIs. This complexity creates opportunities for automation to maintain consistent protection through multi-cloud security operations.

What is the biggest opportunity in cloud security architecture?

Alert fragmentation and cross-cloud correlation represent the biggest opportunities for improvement. Unified platforms that correlate security events across multiple consoles enable detection of multi-stage attacks that span cloud boundaries.

How does automation improve cloud security architecture?

Automation enables unified alert correlation across clouds, accelerates triage processes, speeds threat response, maintains continuous compliance, and scales security operations alongside infrastructure growth. The Torq AI SOC Platform delivers these capabilities.

What is cloud security posture management (CSPM)?

CSPM continuously monitors cloud environments for misconfigurations, compliance violations, and security risks. It identifies issues like publicly exposed storage buckets, excessive permissions, and unencrypted data, enabling proactive cloud misconfiguration detection and remediation.
How do you secure a multi-cloud environment?

Securing multi-cloud environments requires centralized visibility, consistent security policies across platforms, automated threat detection and response, continuous compliance monitoring, and unified identity management. Cloud-native security automation accelerates these capabilities.

What is an incident response plan for cloud security?

An incident response plan defines the processes, roles, and procedures for detecting, responding to, and recovering from security incidents in cloud environments. Automation enhances these plans by enabling faster, more consistent response actions.

SEE TORQ IN ACTION

Ready to automate everything?

“Torq takes the vision that’s in your head and actually puts it on paper and into practice.”

Corey Kaemming, Senior Director of InfoSec

“Torq offers unprecedented protection and drives extraordinary efficiency for RSM and our customers.”

Todd Willoughby, Director

Compuquip logo in white

“Torq saves hundreds of hours a month on analysis. Alert fatigue is a thing of the past.”

Phillip Tarrant, SOC Technical Manager

Fiverr logo in black

“The only limit Torq has is people’s imaginations.”

Gai Hanochi, VP Business Technologies

Carvana logo in black

“Torq Agentic AI now handles 100% of Carvana’s Tier-1 security alerts.”

Dina Mathers, CISO

Riskified logo in white

“Torq has transformed efficiency for all five of my security teams and enabled them to focus on much more high-value strategic work.”

Yossi Yeshua, CISO

Container Security at Scale: Automating Cloud Container Threat Response

Contents

Get a Personalized Demo

See how Torq harnesses AI in your SOC to investigate, prioritize, and respond to threats faster.

Request a Demo

TL;DR

  • Container security protects containerized applications across their full lifecycle, from image build through runtime in production.
  • Key risks include misconfigurations, supply chain vulnerabilities, privilege escalation, and ephemeral workload blind spots.
  • Compliance frameworks like PCI DSS, HIPAA, and GDPR apply directly to containerized environments and require continuous enforcement.
  • Container security tools like Aqua and Prisma Cloud deliver strong detection, and pairing them with automated orchestration multiplies their impact.
  • The Torq AI SOC Platform connects your container security stack, automates triage-to-remediation workflows, and keeps your SOC operating at cloud scale.

Containers redefined how enterprises build, ship, and run software. They’re fast, portable, and purpose-built for cloud-native environments. For SOC teams, that speed and scale bring a new class of security demands that call for equally modern defenses.

Managing hundreds of containerized workloads across dynamic, ephemeral environments means the attack surface shifts constantly. Alerts stack up, compliance requirements stay demanding, and the window between detection and response needs to shrink. The teams winning at this are the ones that have automated the hardest parts.

What Is Container Security?

Container security is the practice of protecting containerized applications and their underlying infrastructure from threats and vulnerabilities throughout their full lifecycle, from development through deployment and into runtime. It brings together strategies, tools, and policies designed to minimize risk across containerized environments at every stage.

Containers differ fundamentally from traditional virtual machines. They share a host OS kernel, spin up in seconds, and scale on demand. That agility powers modern application delivery and requires security controls that move just as fast. A vulnerability in a container image, a misconfigured network policy, or a runtime anomaly can propagate across your environment before manual review catches it.

Cloud container security requires visibility that spans the full container lifecycle, from the moment an image is built to every second it runs in production.

Core Components of Container Security

A strong container security posture rests on several interconnected pillars. Each one addresses a distinct layer of risk, and SOC teams in cloud-native environments need all of them working together.

Image Security: Every container starts as an image. Scanning images for known vulnerabilities, malware, and misconfigurations before they reach production is the first line of defense. This includes verifying base images, auditing dependencies, and enforcing policies on what images are permitted to run.

Runtime Protection: Once a container is live, runtime security monitors for anomalous behavior, such as unexpected process execution, privilege escalation attempts, and unusual network connections. Runtime protection catches active threats and behavioral anomalies that emerge after deployment.

Container Network Security: Containers communicate constantly across your environment. Enforcing least-privilege network policies, segmenting workloads, and monitoring east-west traffic keep lateral movement contained if a workload is compromised.

Secrets and Access Management: Hardcoded credentials and improperly managed secrets rank among the most common and most exploitable container vulnerabilities. Proper secrets management using dedicated vaults and automatic credential rotation closes this gap at the source.

Compliance and Policy Enforcement: Containers running in regulated industries must continuously meet specific standards. Automated policy enforcement keeps your environment compliant even as workloads scale and configurations evolve.

Key Security Challenges in Container Environments

Container environments create distinct risk patterns that SOC teams need to plan for proactively.

  • Misconfigurations: Containers deployed with overly permissive settings, exposed ports, or unnecessary privileges create exploitable gaps. Automated configuration enforcement is what keeps pace with deployment velocity at scale.
  • Supply chain vulnerabilities: Modern applications depend on dozens of third-party components. A vulnerability introduced upstream in a base image or open-source library can affect every container built on top of it.
  • Privilege escalation: Containers running as root or with excessive capabilities give attackers a path to break out of the container and reach the host system. Enforcing least privilege at runtime closes this attack vector.
  • Inter-container ntwork threats: Proper network segmentation limits what a compromised container can reach. Enforcing strict traffic policies between workloads contains lateral movement before it spreads.
  • Ephemeral workload visibility: Containers often live for seconds or minutes. SOC teams need logging and monitoring tools purpose-built for short-lived workloads to maintain full visibility across ephemeral activity.

Common Risks, Compliance, and Operational Impact

Container vulnerabilities create more than security risks. They create operational and business risk too. A single misconfigured container can expose sensitive data, cause service outages, or trigger a compliance violation with material regulatory consequences.

For SOC teams, the challenge is scale. Managing container security monitoring across hundreds or thousands of containers, spanning multiple cloud environments, while keeping pace with alerts from across your full tool stack — that’s where automation creates the biggest operational lift, turning high-volume manual processes into manageable, repeatable workflows.

Container Compliance Requirements

Organizations running containerized workloads in regulated industries face direct compliance obligations. Meeting them manually, across environments that change constantly, creates significant operational burden.

  • PCI DSS requires strict controls around cardholder data, including network segmentation, access controls, and continuous monitoring of payment-processing systems.
  • HIPAA mandates safeguards for protected health information, including audit logging, access controls, and documented incident detection and response capabilities.
  • GDPR requires organizations to protect personal data and demonstrate the ability to identify and report breaches within defined timeframes.
  • SOC 2 evaluates controls across security, availability, and confidentiality, all directly relevant to containerized environments.

Automation transforms compliance from a reactive, periodic effort into a continuous, built-in output. Every response gets logged, very policy gets enforced and every audit trail builds itself.

7 Best Practices for Container Security

Securing containers means building security into every stage of the lifecycle, proactively, and with enough automation to keep pace with cloud-native deployment speeds.

  1. Shift security left: Integrate image scanning and policy checks into your CI/CD pipeline. Addressing vulnerabilities before deployment reduces risk and remediation cost downstream.
  2. Enforce least privilege: Run containers with the minimum permissions required. Drop unnecessary Linux capabilities, avoid running as root, and use read-only file systems wherever feasible.
  3. Implement network segmentation: Define and enforce network policies that limit container-to-container communication to only what the application requires. Tight segmentation limits blast radius when a workload is compromised.
  4. Manage secrets properly: Use a dedicated secrets manager. Credentials hardcoded in container images or passed as plain-text environment variables are an avoidable exposure.
  5. Monitor runtime behavior continuously: Static scanning identifies known vulnerabilities at a point in time. Runtime monitoring adds continuous coverage, catching behavioral anomalies that signal active exploitation or emerging misconfiguration across live workloads.
  6. Automate vulnerability and patch management: When a new CVE surfaces, your team needs to know which images are affected and move fast. Automated vulnerability management workflows that detect, prioritize, and trigger remediation dramatically compress exposure windows.
  7. Maintain immutable infrastructure: Treat containers as immutable artifacts. Rebuild and redeploy from updated images rather than patching running containers. This keeps your environment consistent, auditable, and free of configuration drift.

Container Security Tools and Monitoring

A well-equipped container security stack includes specialized tools for every layer of protection:

  • Aqua Security delivers full lifecycle container security, including image scanning, runtime protection, and compliance reporting. Aqua’s depth of visibility into container behavior makes it a high-value detection layer for SOC teams.
  • Prisma Cloud provides cloud-native security across the full application stack, with strong container workload protection and compliance capabilities built in.
  • Sysdig focuses on runtime security and deep observability, giving teams granular visibility into what’s happening inside running containers in real time.

These tools generate rich telemetry and high-fidelity alerts. The opportunity is in what happens next: when those alerts need to be triaged, enriched, and acted on across your broader SOC ecosystem. Centralized orchestration is what turns detection into response at speed. For teams managing cloud infrastructure and containerized applications together, Torq is purpose-built for exactly this challenge.

Prevention and Threat Mitigation

Prevention and response work together in container security. Building strong prevention into your workflows reduces alert volume and response pressure downstream.

  • Policy enforcement at build time: Use admission controllers like Open Policy Agent or Kubernetes admission webhooks to block non-compliant workloads before they deploy.
  • Risk-based vulnerability prioritization: Focus remediation on CVEs that are exploitable in your specific environment. Risk-based prioritization helps your team work on what matters most.
  • Automated remediation workflows: When a vulnerability is confirmed, automatically trigger the appropriate response: quarantine the container, initiate a rebuild, or create a developer ticket, and keep remediation moving at machine speed. Explore automated SOC incident response to see how this works end to end.
  • Threat intelligence enrichment: Enrich alerts with external threat intelligence to contextualize risk, separate genuine threats from noise, and accelerate the path to response.

Automating Container Security with Torq

Container security tools excel at detection. The real operational opportunity is in everything that follows: triage, enrichment, escalation, remediation, and documentation. Automation handles each of those steps in seconds, consistently, at any scale.

The Torq AI SOC Platform powers that automated response layer. Torq connects your container security tools to your broader SOC ecosystem through a hyperautomation engine, enabling your team to build and deploy full response lifecycle workflows entirely in a visual, code-free environment.

Torq Hyperautomation™ drives orchestration across 300+ pre-built integrations, including Aqua, Prisma Cloud, Sysdig, Jira, Slack, and your SIEM. Torq Socrates™, Torq’s agentic SOC orchestrator, adds an intelligent reasoning layer that analyzes incoming alerts, determines the appropriate response, and executes workflows in real time. Torq HyperAgents™ extend that intelligence further, enabling specialized AI Agents to handle discrete tasks like enrichment, case creation, notification, and remediation as part of a coordinated, automated response.

For Cloud and AppSec teams, Torq delivers a set of capabilities purpose-built for containerized environments: 

  • Container and Kubernetes security integration for runtime threat detection and workload policy enforcement
  • Cloud compliance automation that continuously monitors and enforces PCI DSS, HIPAA, GDPR, and SOC 2 across multi-cloud environments
  • Automated vulnerability triage that correlates CVE data with runtime context and asset criticality
  • DevSecOps pipeline integration with CI/CD platforms like GitHub Actions, GitLab, and Jenkins, so security gates run at full development speed

Real-Time Response and Orchestration

Here’s what automated container security response looks like in practice.

The scenario: Aqua Security detects a critical CVE in a container image running in production.

  1. Enrichment: Torq receives the alert from Aqua and enriches it automatically. It pulls CVE details, assesses the affected image’s deployment scope, and queries threat intelligence to evaluate exploitability.
  2. Case creation: Torq opens a structured incident case, pulling in all relevant context: the affected containers, impacted services, compliance implications, and a prioritized severity score.
  3. Notification and escalation: The right stakeholders receive immediate notification via Slack or email, with full context already included. Every relevant detail is ready for action the moment the alert lands.
  4. Remediation trigger: Based on severity and your team’s configured policy rules, Torq triggers the appropriate remediation action: quarantining the container, initiating an image rebuild, or creating a Jira ticket for the engineering team with everything they need to act.
  5. Documentation and compliance: Every action gets logged automatically, building an auditable record that supports compliance reporting, all generated as a built-in part of the response.

What would take an analyst 30-45 minutes of manual work happens in seconds, every time, regardless of alert volume. That’s the operational impact of security automation workflows applied to container environments. For a broader look at what’s driving urgency around SOC automation right now, the AI SOC Apocalypse report lays out the full picture.

Closing the Gap Between Detection and Action

Container environments scale faster than security teams can staff. Smarter orchestration is the answer.

Torq eliminates the vendor sprawl that creates friction in modern SOC operations. A single automation layer connects your container security tools, ticketing system, SIEM, and communication platforms, so your team manages orchestrated workflows instead of point-to-point integrations. API-based and cloud-native, Torq extends the value of the tools you already use. Learn more about how SOC teams use Torq to scale their operations.

Compliance becomes a continuous output. Torq’s workflows enforce policy, log every action, and generate audit-ready documentation, automatically, as part of every response. For cloud-native environments, that means faster MTTR, reduced analyst burden, and a security posture that scales with your infrastructure.

The Future of Container Security Is Automated

Container security at cloud scale requires speed, consistency, and the ability to act across a distributed environment the moment a threat surfaces. The teams that operate most effectively combine strong detection tools with automated orchestration that closes the gap between alert and action, enriching, triaging, and remediating at the speed the threat environment demands.

Torq’s AI SOC Platform gives your team that capability. Built for cloud-native environments, integrated with the container security tools you rely on, and engineered to scale with your infrastructure as it grows.

The data backs it up. The 2026 AI SOC Leadership Report surveyed 450 CISOs and SOC leaders and found 94% already use AI somewhere in the SOC, yet 80% still run fragmented point solutions, and 85% say they’d prefer a unified platform. The security leaders closing the detection-to-action gap fastest are the ones who’ve made automation the connective tissue across their entire stack.

Container security at scale demands more than monitoring — it demands automation that connects your entire stack.

See what 450 CISOs and SOC leaders say is the missing link in the 2026 AI SOC Leadership Report.

FAQs

What is container security?

Container security is the practice of protecting containerized applications and their infrastructure from threats and vulnerabilities across the full lifecycle, from image build through deployment and runtime. It covers image scanning, runtime protection, network segmentation, secrets management, and compliance enforcement. For cloud-native SOC teams, strong container security pairs detection tools with automated response workflows to keep pace with the speed and scale of modern environments.

What are the biggest container security risks?

The most common container security risks include misconfigurations, supply chain vulnerabilities in base images or third-party dependencies, privilege escalation from containers running with excessive permissions, lateral movement through insufficient network segmentation, and blind spots in ephemeral workloads. Addressing these risks requires both preventive controls and real-time container security monitoring.

How do you secure containers in cloud environments?

Securing containers in cloud environments means applying security at every stage: scanning images in your CI/CD pipeline, enforcing least-privilege access, segmenting container networks, managing secrets properly, and monitoring runtime behavior continuously. Pairing these practices with automated incident response ensures threats get detected and remediated at the speed cloud-native environments demand.

What container security tools do SOC teams use?

SOC teams commonly use Aqua Security, Prisma Cloud, and Sysdig for container-specific detection and visibility. These tools integrate directly with the Torq AI SOC Platform, which orchestrates alert triage, enrichment, case creation, and remediation across the full SOC ecosystem through Torq Hyperautomation.

What compliance frameworks apply to container security?

PCI DSS, HIPAA, GDPR, and SOC 2 all have direct implications for containerized environments. Each requires ongoing controls, logging, and the ability to detect and respond to security events within defined timeframes. Automated compliance enforcement built into your response workflows makes continuous adherence achievable at scale.

What is container security for DevOps?

Container security for DevOps means integrating security into the development and deployment pipeline from the start: scanning images at build time, enforcing policies through admission controllers, and giving developers fast feedback on vulnerabilities before code reaches production. This approach, often called DevSecOps, enables security to move at the pace of development. Agentic coding for SecOps explores how AI-powered tooling is accelerating this further.

How does Torq help with container security automation?

Torq connects your container security tools, including Aqua, Prisma Cloud, and Sysdig, to your broader SOC stack and automates the full response workflow: enrichment, case creation, notification, remediation, and compliance logging. Torq Socrates, Torq’s agentic SOC orchestrator, reasons over alerts and executes responses in real time. Explore Torq HyperAgents to see how the platform handles container threats at enterprise scale.

SEE TORQ IN ACTION

Ready to automate everything?

“Torq takes the vision that’s in your head and actually puts it on paper and into practice.”

Corey Kaemming, Senior Director of InfoSec

“Torq offers unprecedented protection and drives extraordinary efficiency for RSM and our customers.”

Todd Willoughby, Director

Compuquip logo in white

“Torq saves hundreds of hours a month on analysis. Alert fatigue is a thing of the past.”

Phillip Tarrant, SOC Technical Manager

Fiverr logo in black

“The only limit Torq has is people’s imaginations.”

Gai Hanochi, VP Business Technologies

Carvana logo in black

“Torq Agentic AI now handles 100% of Carvana’s Tier-1 security alerts.”

Dina Mathers, CISO

Riskified logo in white

“Torq has transformed efficiency for all five of my security teams and enabled them to focus on much more high-value strategic work.”

Yossi Yeshua, CISO

Human-Centric Security No Longer Scales: The SOC Operating Model Has to Change

Contents

Get a Personalized Demo

See how Torq harnesses AI in your SOC to investigate, prioritize, and respond to threats faster.

Request a Demo

John White is the Field CISO for EMEA at Torq. A respected security executive with more than 20 years of leadership experience, John previously served as CISO at Virgin Atlantic, where he led a multi-year transformation deploying the Torq AI SOC Platform to modernize cyber operations. Prior to that, he built and transformed security functions for global organizations, including ASOS, Liberty Global, AEG Europe, and KPMG.

Many security functions today still rely heavily on humans for detection, triage, and response, often by design. But as environments grow more complex and alert volumes explode, it raises a hard question: Can this approach scale on its own?

Adopting AI in security operations isn’t just about adding tools. It means rethinking the SOC operating model itself — roles, workflows, and team structures. Here’s why, and how.

Human Speed Is Not Enough

AI-powered attackers are rewriting malware in hours, not weeks. They don’t sleep, don’t take holidays, and don’t slow down between shifts. The uncomfortable truth for every security leader: a defense built around human reaction times is already structurally defeated.

Earlier this year, Check Point documented a threat actor who used AI to build an entire malware platform. What had previously required a 30-week development cycle was executed in hours. Let that land for a moment. A months-long engineering effort, compressed to a morning. And the defenders on the other side? Still triaging alerts by hand. Still waiting for a human analyst to open the ticket.

I’ve spent more than 20 years in this industry. I’ve led security transformations at Virgin Atlantic, ASOS, Liberty Global, and others. I’ve seen every generation of the threat landscape evolve — from script kiddies to organized crime to nation-state actors. But I have never seen a shift as fundamental as this one. The emergence of agentic AI on the offensive side has broken the basic assumption that human defenders, given enough tools and talent, can keep pace. They cannot. Not anymore.

94% of organizations are using AI in the SOC in some capacity80% are still running fragmented toolsThe average SOC runs 7 different AI tools — most of them disconnected

Source: 2026 AI SOC Leadership Report

The Math Stopped Working

Security teams have always faced a staffing problem. The talent shortage is not new. But something changed recently: the gap between the attack surface and the available defense capability stopped being a hiring problem and became a physics problem. You cannot hire your way to machine speed. You cannot add a third shift to match an adversary that operates continuously, at scale, without fatigue or error.

Consider what a machine-speed attack looks like in practice. An AI-assisted attacker is not simply running faster phishing campaigns. It is dynamically adapting malware signatures to evade detection. It is scanning and correlating exposed credentials across the internet in real time. It is probing your attack surface while your analysts are writing up last night’s incident report. The asymmetry is not modest. It is categorical.

“You cannot fight machine-speed threats with human-speed defense. A security organization built around 9-to-5 shifts and human triage cycles is, structurally, indefensible against what’s coming.”

– John White, Field CISO, Torq

Why “More Tools” Is the Wrong Answer

The instinctive response to a growing threat landscape has always been procurement. Add a new detection layer. Buy the next-generation endpoint solution. Subscribe to another threat intelligence feed. The average SOC today runs seven AI-powered tools. 10% are managing 10 or more. Across the enterprise, organizations deploy an average of 83 security tools from 29 different vendors.

And yet analysts are more overwhelmed than ever. Not because the tools don’t work in isolation, but because a human being sits at every integration point — manually bridging context between platforms, fighting alert fatigue, and making triage decisions that should have been automated years ago. More tools without a unified execution layer don’t multiply capability. It multiplies noise.

85% of security leaders say they want consolidation over fragmented point solutions. Yet 80% are still running exactly that. The intention exists. The SOC operating model to support it does not, because those models were designed for a slower, more forgiving threat environment.

The analysts on your team are not unhappy because they dislike security. They’re unhappy because they’re not doing security work. They’re drowning in noise instead of solving problems. I’ve seen this firsthand. When AI handles triage at scale, something remarkable happens: you look out at your team, and they don’t seem overwhelmed anymore. They have time to think. They apply quality, not just throughput. The work they were hired to do becomes possible again.

Accountability Has Changed

Here is the harder conversation I have been having with CISOs across EMEA: the accountability framing has fundamentally shifted.

A decade ago, a CISO’s culpability was largely reactive — did you have reasonable controls in place at the time of breach? That question has not gone away. But a new question has emerged alongside it: Did you fail to adopt capabilities that would have materially reduced your exposure?

Failing to govern and deploy AI-driven security is no longer a conservative choice that preserves safety. It is a strategic decision to remain structurally behind. And boards, insurers, and regulators are beginning to understand the difference. CISOs who treat 2026 as a transition year — a year to watch and learn — will find that window has already closed around them.

I want to be clear: this is not an argument for removing humans from the loop. Quite the opposite. The decisions that require genuine human authority are the ones that demand business context — your organization’s risk appetite, the political environment you’re operating in, and the board’s strategic direction. That judgment layer cannot and should not be automated.

But the execution layer — the triage, the enrichment, the initial containment, the correlation of signals across your stack — that needs to run at machine speed. And it can.

What the New SOC Operating Model Looks Like

When I evaluate security platforms now, I use a simple filter: does this require constant human intervention to function? If yes, it becomes a bottleneck, not a defense. Any tool that cannot operate autonomously within clearly defined constraints, while still providing real-time observability, will not scale against the threat environment we are describing.

The strongest platforms I have seen do three things well:

  1. They reduce cognitive load. They interpret volumes of data and surface the insights that matter, rather than adding to the noise.
  2. They move beyond detection into recommendation and, where appropriate, remediation.
  3. They are continuously self-measuring, turning security from a reactive function into an optimizing system that can demonstrate its own effectiveness.

This is the SOC operating model I spent years trying to build from the inside at Virgin Atlantic, and the reason I moved to Torq. The agentic SOC — where machines fight machines, where AI Agents handle the execution layer at the speed the threat requires, and where human analysts focus on the judgment calls that actually need them — is not a vision document. It is deployable today.

The question for every security leader reading this is not whether this future is coming. It is whether you will be leading it or responding to it.

Here’s what happens when the SOC operating model is redesigned around the execution layer running at machine speed:

8.2x faster incident detection-to-containment75% reduction in MTTR for common security incidents95% decrease in manual tasks for Tier 1 SOC analysts
100% of Tier 1 tickets auto-remediated without human involvement4x capability to handle security alerts with the same-sized team80% alert fatigue reduction

“AI isn’t a tool you bolt onto your existing SOC. It’s forcing us to fundamentally rethink how security organizations are structured, staffed, and measured. The CISOs who redesign their SOC operating model now will build teams that operate at machine speed.”

– John White, Field CISO, Torq

A Call to Action: Redesign Your SOC Operating Model

Start with your current state, but do not think in disciplines. Think in outcomes. Where does human latency create an unacceptable gap? Where are your analysts spending time on decisions that should be automated? Where is the absence of 24/7/365 coverage leaving you exposed in the hours between shifts?

Design the SOC operating model of the future with AI and automation at its heart — not layered on top of a legacy model, but embedded from the foundation. That means 24/7 coverage that never sleeps, consistent execution that never fatigues, and human judgment applied exactly where it adds irreplaceable value.

The threat is already operating at machine speed. The only rational response is to meet it there.

Keep reading John’s CISO to CISO Blog Series on Redesigning SecOps for AI.

SEE TORQ IN ACTION

Ready to automate everything?

“Torq takes the vision that’s in your head and actually puts it on paper and into practice.”

Corey Kaemming, Senior Director of InfoSec

“Torq offers unprecedented protection and drives extraordinary efficiency for RSM and our customers.”

Todd Willoughby, Director

Compuquip logo in white

“Torq saves hundreds of hours a month on analysis. Alert fatigue is a thing of the past.”

Phillip Tarrant, SOC Technical Manager

Fiverr logo in black

“The only limit Torq has is people’s imaginations.”

Gai Hanochi, VP Business Technologies

Carvana logo in black

“Torq Agentic AI now handles 100% of Carvana’s Tier-1 security alerts.”

Dina Mathers, CISO

Riskified logo in white

“Torq has transformed efficiency for all five of my security teams and enabled them to focus on much more high-value strategic work.”

Yossi Yeshua, CISO

AI SOC Metrics That Actually Matter: How to Measure Whether AI Is Working in Your SOC

Contents

Get a Personalized Demo

See how Torq harnesses AI in your SOC to investigate, prioritize, and respond to threats faster.

Request a Demo

TL;DR:

  • Track what matters. MTTI, MTTR, autonomous case closure rate, analyst hours reclaimed, false positive suppression, and escalation accuracy. Not vanity metrics like “alerts processed.”
  • Baseline before you deploy. Without pre-deployment benchmarks, any improvement is anecdotal and indefensible at budget time.
  • Benchmark against real results. Carvana automated 100% of Tier-1 alerts. HWG Sababa improved MTTI and MTTR by 95%. Valvoline saved 6 to 7 analyst hours per day within 48 hours.
  • Report in board language. Translate AI SOC metrics into risk reduction, increased capacity, improved coverage, and greater trust maturity.

Every security vendor shipping an AI product in 2026 makes the same promises. Faster triage. Shorter response times. Fewer false positives. Reclaimed analyst hours. But, six months after deployment, most security leaders still cannot answer a straightforward question from the board: Is this thing actually working?

The problem is not necessarily that AI in the SOC fails to deliver (although in many cases, when the AI is immature or bolted-on, it does). The core problem is that most organizations never defined what “working” looks like before they deployed it. They skipped baselines, tracked the wrong metric, or failed to build a reporting framework that connects SOC performance to business outcomes. So when the CFO asks what the organization got for its AI investment, the CISO is left pointing at vendor dashboards full of numbers that mean nothing to anyone outside the SOC.

That is the accountability gap. It is the difference between an AI deployment that earns expanded investment and one that gets quietly deprioritized at the next budget cycle.

This article provides the AI SOC metrics framework to close that gap: the metrics that indicate whether AI is delivering real value, the baselines you should have captured before deployment (and how to reconstruct them if you did not), the benchmarks from real production environments that show what “good” looks like, and the reporting model that translates AI SOC metrics into the language your board already speaks.

What AI SOC Metrics Actually Matter?

Not every number your SOC produces tells you whether AI is delivering value. The right AI SOC metrics are genuinely diagnostic. 

The AI SOC metrics that matter:

  • Mean Time to Investigate (MTTI) measures whether AI is accelerating the part of the workflow where analysts spend most of their time. Faster triage speed has become table stakes for AI SOC tools. The real test is investigation speed — whether the AI is doing meaningful work like enriching data, correlating events, and building timelines, instead of  just routing alerts to the same queue slightly faster.
  • Mean Time to Respond (MTTR) is the end-to-end metric: from alert to resolution. This is the number boards understand because it maps directly to risk exposure. Every minute between detection and response is a minute an attacker has to move laterally, exfiltrate data, or escalate privileges. When AI compresses MTTR, it compresses the window of exposure.
  • Autonomous case closure rate tracks the percentage of cases that resolve without human intervention and the accuracy of that resolution. This is the metric that separates agentic AI from assisted tooling. If a human still has to review every case the AI touches, you haven’t automated anything.
  • Analyst hours reclaimed measures the time your team got back for higher-value work. Not “alerts processed” but actual hours. The distinction matters because it connects directly to capacity, which in turn connects to what your team can now do that it couldn’t before: deeper investigations, threat hunting, proactive risk reduction, and new automation development.
  • False-positive suppression rate indicates whether the AI is genuinely filtering noise or merely relabeling it. If your analysts are still manually reviewing the same volume of cases under a different status label, false-positive suppression isn’t working.
  • Escalation accuracy measures whether the AI makes the right call when it does hand a case to a human. High autonomous closure rates mean nothing if the cases that are escalated are wrong, incomplete, or lack context. Escalation accuracy is a direct proxy for analyst trust.

The metrics that mislead:

  • “Alerts processed” counts volume without outcomes. Processing 10,000 alerts means nothing if 9,500 of them didn’t need investigation.
  • “Time saved per alert” ignores whether the alert warranted investigation. Saving 30 seconds on a false positive isn’t time savings.
  • “AI accuracy” without context hides the failures that matter most. Consider this scenario: 99% accuracy on easy cases and 60% on hard ones isn’t 99% accuracy. It’s a weighted average that misleads the buyer.

Baselining Your AI SOC Metrics Before Deployment

This is the step that’s all too easy to skip, but without it, you can’t prove improvement later. Before deploying AI in your SOC, capture current-state baselines for MTTI by case type (phishing, malware, identity compromise, etc.), MTTR by severity level, analyst hours spent on Tier 1 triage, investigation, and strategic work, case backlog depth and aging, and escalation volume and accuracy.

Without these baselines, any post-deployment improvement is anecdotal. Your MTTR dropped? Compared to what — last month, which happened to be a quiet threat period? You’re closing more cases autonomously? Were you tracking closure rates before, or just estimating?

With baselines, you have a before-and-after story that boards understand. Not “we think things are better” but “our MTTI for phishing cases dropped from 45 minutes to six minutes, and here’s the data.”

If you’ve already deployed AI without capturing baselines, you’re not out of options. Pull historical data from your SIEM and ticketing system for the 90 days prior to deployment. Reconstruct approximate MTTI and MTTR by case type using ticket timestamps. Survey your analysts on how they spent their time pre-deployment — their estimates won’t be precise, but they’ll give you a good comparison point..

AI SOC Metrics Benchmarks: What “Good” Looks Like in Real Deployments

This is where the conversation shifts from theory to evidence. Most vendors publishing AI SOC content can tell you what metrics to track, but very few can tell you what the numbers should actually look like because they don’t have customer data to back it up.

Here’s what production deployments have demonstrated.

MTTR trajectory: HWG Sababa, a managed security services provider, achieved a 95% improvement in MTTI and MTTR for medium- and low-priority cases, and 85% for high-priority cases — with investigation and response now occurring nearly simultaneously in under eight minutes. That’s a measurable, repeatable benchmark across priority tiers. If your AI has been live for six months and your MTTR curve is flat, the platform isn’t learning.

Autonomous closure rates. Carvana automated 100% of Tier 1 alert handling and 41 different runbooks within one month of deployment. Bloomreach‘s SOC uses Torq’s AI SOC Orchestrator, Socrates, to handle Tier 1 and Tier 2 tasks autonomously, freeing analysts from entirely repetitive triage. These results establish the benchmark: leading organizations are closing the majority of Tier 1 and even Tier 2 cases autonomously within months of deployment. If your autonomous closure rate has stalled after six months, review your confidence thresholds, workflow design, and the scope of cases you’re allowing the AI to handle.

Analyst hours reclaimed. Valvoline saved 6-7 analyst hours per day after deploying Torq — and saw measurable ROI within 48 hours of go-live. That’s not a percentage on a dashboard. That’s time analysts can point to on their calendars — hours redirected from repetitive triage to investigation, threat hunting, and automation development.

SOC throughput without headcount growth. HWG Sababa nearly doubled SOC throughput with no new hires. Agoda compressed incident report generation from seven hours to 40 minutes. These results matter because they answer the question every CISO faces: Can I scale my SOC without scaling my team? The data says yes — if the AI is measured and managed correctly.

Use these benchmarks not as targets to hit on day one, but as reference points for your own deployment curve. 

Turning AI SOC Metrics into a Board-Ready Reporting Framework

CISOs who successfully justify AI investment don’t present raw AI SOC metrics to the board. They translate those metrics into the four things boards care about: risk, cost, capacity, and trajectory.

1. MTTR reduction → Risk exposure reduction. Frame it as: “Our mean time to respond dropped from four hours to 12 minutes. That means an attacker’s window to operate inside our environment shrank by 95%.” Boards understand windows of exposure; they might not understand MTTR.

2. Analyst hours saved → Capacity gained. Don’t frame this as headcount reduction; frame it as coverage expansion. Instead: “We recovered the equivalent of 1.5 full-time analysts in capacity. That capacity is now allocated to threat hunting and proactive risk reduction work that we couldn’t staff before.” Boards understand that doing more with the same team is possible.

3. Autonomous closure rates → Coverage improvement. Frame it as: “Before AI, we could meaningfully investigate approximately 60% of incoming alerts. We now investigate 100%. Every alert gets full triage and, when warranted, a complete investigation — without adding headcount.” Boards understand coverage gaps. Telling them you closed the gap is more powerful than any MTTR chart.

4. Escalation accuracy → Trust maturity. This is the trend line that matters most for long-term buy-in: “In month one, the AI escalated cases at 82% accuracy. By month six, it was 96%. The system is measurably getting better at knowing when to act and when to ask for help.” Boards understand learning curves — show them one.

For reporting cadence, deliver monthly operational AI SOC metrics to SOC leadership — MTTI, MTTR, closure rates, escalation accuracy, and analyst utilization. These are your tuning instruments. Quarterly, deliver business impact summaries to the CISO and board — risk reduction, capacity gained, coverage improvement, cost avoidance, and the trend curves that show compounding returns. 

How Long Does It Take for AI to Show Measurable Results in a SOC?

Tracking AI SOC metrics isn’t a one-time exercise. It’s a maturity journey, and the metrics should reflect that.

  • Month 1–3: Validate performance in shadow mode. Run AI decisions in parallel with analysts. Compare what the AI would have done against what analysts actually did. Establish accuracy baselines and identify where the AI agrees with your team and where it diverges. This phase builds internal confidence. If the AI matches analyst decisions a majority of the time on Tier 1 cases, you have the evidence to increase autonomy.
  • Month 3–6: Increase autonomy. Expand autonomous closure. Track escalation accuracy weekly. Tune confidence thresholds based on real outcomes, not theoretical risk models.
  • Month 6–12: Expand use cases. Benchmark against industry data. Extend AI into Tier 2 investigation, cross-team workflows, and compliance reporting. Demonstrate compounding improvement — not just in speed, but in scope.
  • Month 12+: Activate AI-driven insights. The AI surfaces trends humans couldn’t detect at scale — detection rule gaps, recurring misconfiguration patterns, team capacity forecasting, and emerging attack vector correlation. At this stage, the AI isn’t just executing your security strategy; it’s informing it.

The key signal to watch across all stages: AI SOC metrics should compound before they plateau. An early flat line means the platform isn’t learning. A late plateau after months of sustained improvement is what a mature deployment looks like. MTTR should keep dropping. Autonomous closure rates should keep climbing. Escalation accuracy should keep tightening. If your numbers plateau after month three, something is wrong. Either the AI isn’t learning from new data, the use cases aren’t expanding, or the confidence thresholds need adjustment. 

The AI SOC Metrics Imperative

The organizations getting the most from their AI investment aren’t running the most sophisticated models. They’re running the clearest measurement frameworks — and they have the discipline to track them.

Define your baselines. Track the metrics that connect to outcomes. Build the dashboard your board actually wants to see. And benchmark against organizations that have already proven what’s possible.

Explore our 90 Days to SOC Autonomy roadmap.

FAQs

What are the most important AI SOC metrics to track?

The AI SOC metrics that matter most are MTTI, MTTR, autonomous case closure rate, analyst hours reclaimed, false positive suppression rate, and escalation accuracy. Baseline these metrics before deployment and track them monthly. Organizations using Torq have demonstrated MTTI/MTTR improvements of 95%, autonomous alert management of 55%+ of total volume, and full Tier 1 automation within months of deployment.

What is a good autonomous case closure rate for an AI SOC?

Leading organizations achieve 55–100% autonomous case closure rates for Tier 1 and Tier-2 cases. HWG Sababa automatically manages approximately 55% of total monthly alert volume end-to-end. Carvana automated 100% of Tier 1 alert handling and 41 runbooks within one month. If your AI has been live for six months and autonomous closure is stagnant, review your confidence thresholds and workflow design.

How do you report AI SOC metrics to the board?

Translate AI SOC metrics into business language: MTTR reduction maps to reduced risk exposure, analyst hours saved maps to capacity gained (not headcount cut), autonomous closure rates map to coverage improvement, and escalation accuracy maps to trust maturity. Report operational metrics monthly to SOC leadership and quarterly business impact summaries to the CISO and board.

How long does it take for AI to show measurable results in a SOC?

Most organizations see initial results within weeks. Valvoline saw ROI within 48 hours of deploying Torq. However, the compounding value of agentic AI — improving accuracy, expanding use cases, surfacing operational trends — builds over 3-12 months. HWG Sababa achieved a 95% MTTI/MTTR improvement and nearly doubled SOC throughput without adding headcount, with the steepest gains occurring in the early months of deployment.

SEE TORQ IN ACTION

Ready to automate everything?

“Torq takes the vision that’s in your head and actually puts it on paper and into practice.”

Corey Kaemming, Senior Director of InfoSec

“Torq offers unprecedented protection and drives extraordinary efficiency for RSM and our customers.”

Todd Willoughby, Director

Compuquip logo in white

“Torq saves hundreds of hours a month on analysis. Alert fatigue is a thing of the past.”

Phillip Tarrant, SOC Technical Manager

Fiverr logo in black

“The only limit Torq has is people’s imaginations.”

Gai Hanochi, VP Business Technologies

Carvana logo in black

“Torq Agentic AI now handles 100% of Carvana’s Tier-1 security alerts.”

Dina Mathers, CISO

Riskified logo in white

“Torq has transformed efficiency for all five of my security teams and enabled them to focus on much more high-value strategic work.”

Yossi Yeshua, CISO

What SOC Analysts Actually Want From AI

Contents

Get a Personalized Demo

See how Torq harnesses AI in your SOC to investigate, prioritize, and respond to threats faster.

Request a Demo

Rick Bosworth is a cybersecurity marketing executive with nearly two decades of experience driving GTM strategy across technology startups. His uniquely technical perspective bridges the gap between complex solutions and practical customer outcomes. Rick has deep expertise spanning EDR, CNAPP, CWPP, AppSec, CTEM, and agentic SecOps. When he is not speaking publicly, enabling sellers, or leading cross-functional initiatives, Rick enjoys adventurous dining, endurance athletics, and craft beer.

When asked about the #1 expected benefit of agentic AI, security leaders didn’t say faster detection or better MTTR. They said quality of life. This finding comes directly from 450 CISOs and cybersecurity leaders surveyed in the recently published 2026 AI SOC Leadership Report.

There’s no shortage of AI in today’s security operations center (SOC). Generative AI. LLM copilots. Agentic workflows. Custom-built agents. Vendor-driven automation. The SOC is saturated with intelligence, at least in theory. And yet, ask SOC analysts how things feel on the ground, and the answer is far more complicated.

Nearly four in five organizations are now using AI in their SOCs in some capacity, and many have embedded it across workflows. While AI adoption has surged, operational clarity has not kept pace. Instead of simplifying operations, AI has introduced a new layer of complexity: more tools, more outputs, more decisions to validate. This is the paradox at the heart of the modern SOC: 

To understand why, you have to look past adoption metrics and into what analysts are actually experiencing, and more importantly, what they actually want.

AI Is Everywhere, But It’s Fragmented

On paper, the SOC has embraced AI. In practice, it’s stitched together from disconnected parts. The SOC now runs an average of 7 AI-powered SOC tools, and 80% of teams rely on fragmented point solutions. These tools operate independently, each with its own interface, logic, and version of reality.

No single system can see the full picture, so analysts rush in to fill the gap. SOC staff become the integration layer, manually correlating signals, validating outputs, and reconciling conflicting conclusions across tools. Operational overhead, the very thing AI was supposed to eliminate, has been reintroduced.

This is not a failure of AI capability, but a failure of architecture.

The Analyst Experience: From Operator to Orchestrator

AI is reshaping the role of the SOC analyst. Previously, analysts were the execution layer, spending their time triaging alerts, enriching data, and running playbooks. AI now handles much of that processing. In its place, a new layer of work has emerged: oversight, validation, and decision-making.

On average, analysts now spend 8.6 hours per week reviewing AI-generated outputs. At first glance, that can look like inefficiency: a full workday spent checking the machine’s work. But that interpretation misses the shift that’s actually happening.

Analysts are moving from execution to judgment. From doing the work to deciding what matters. If AI does the lion’s share of the previously manual, repetitive tasks, SOC capacity expands. AI saves more than the 8.6 hrs per week that humans spend on oversight.

This is progress, and this is only the early innings. Nearly 9 in 10 security leaders say AI has improved workload and reduced burnout. But this progress comes with a condition: the oversight-for-execution trade-off only works if it’s efficient.

When AI outputs are opaque, inconsistent, or fragmented, oversight becomes a source of friction. When reasoning is clear and context is unified, oversight becomes strategy.

What Security Leaders Say Their Analysts Need Most

Strip away the noise, the AI hype, and dashboards, and a clear picture emerges of what analysts actually need. When 450 security leaders were asked what would most improve SOC operations, the answers weren’t about faster models or more automation. They pointed to the conditions their teams need to actually do their jobs.

1. Better Quality of Life

At its core, the SOC remains a human system. And the leaders running these teams are explicit about what would improve it: 

  • Fewer repetitive, manual tasks
  • Better workload distribution and prioritization
  • More sustainable work-life balance

These objectives reflect a daily reality of alert fatigue, context switching, and cognitive overload. AI has the potential to solve these problems, but only if it reduces friction, not adds to it.

2. AI They Can Trust

Trust is the defining constraint of AI in the SOC. Full stop.

Only a small fraction of leaders report zero concerns about AI. The vast majority point to issues like:

  • Data privacy risks
  • False negatives (missed threats)
  • False positives
  • Black-box decision-making

The common thread? Visibility. Transparency. Explainability. Analysts and cybersecurity leaders don’t just want answers. They want to understand how those answers were reached. In fact, 90% of security leaders say they need explainability to trust AI decisions.

Because in security operations, decisions carry consequences. And confidence comes from clarity.

3. Control Over Automation

Despite widespread belief in AI’s capabilities (here is your friendly reminder to download the 2026 AI SOC Leadership Report for the supporting details), most teams are cautious about letting it act autonomously.

Nearly all organizations are comfortable with some level of AI-driven action, and most draw a hard line at medium-severity incidents. Not only is the aforementioned trust factor at play, but also a lack of control.

Today’s tools often present a binary choice: AI acts, or humans act. That’s hardly a choice when the stakes are high.

What analysts actually want is a dial. They want to calibrate autonomy based on:

  • Severity
  • Confidence
  • Context

Low-risk, high-volume alerts? Let AI handle them end-to-end. High-risk, high-impact incidents? Keep humans in the loop.

Not all automation is, or even should be, equal. Analysts demand the flexibility to decide where the line is drawn, and to move it over time at their discretion. See also, judgment layer.

4. Fewer Tools, More Cohesion

Perhaps the most consistent signal across the data is this: 85% of security leaders would prefer a unified platform over multiple point solutions.

Let us be crystal clear: no one is suggesting replacing existing tools. EDRs, CNAPPs, and other security controls serve critical functions. The best are exceptional at their prescribed function. The issue is what sits above them, or rather, what does not.

Most SOCs today do not have a unified layer that:

  • Sees across the full stack
  • Correlates fragmented signals
  • Provides consistent reasoning
  • Enables coordinated action

So analysts jump into that void. And teams are back to manual, repetitive tasks in the effort to stitch together context spread across data siloes. The previously mentioned tradeoff between execution and oversight falters, diminishing the value of what AI could otherwise deliver.

The Real Bottleneck: Trust, Not Tech

One of the most striking findings in the data is the dichotomy between what teams believe AI can do and what they actually allow it to do. To wit, even though 97% believe AI can handle alert triage, only 35% are using it for that purpose.

This pattern repeats across the SOC. (Did you even download the 2026 AI SOC Leadership Report?) AI is widely trusted to analyze, investigate, and recommend. It’s far less trusted to act. 

Organizations lack confidence in how AI operates. Trust breaks down when:

  • Decisions cannot be explained
  • Data access is not governed
  • Outputs cannot be verified
  • Control boundaries are not clear

In other words, AI has the ability. Analysts just don’t trust it to do the right thing. 

The SOC Analysts Are Asking For: Unified, Explainable, Controllable

Despite the challenges, there is remarkable alignment on what the ideal SOC should look like. Across roles, industries, and geographies, the vision is consistent for a system that is:

  • Unified across the entire security stack
  • Explainable in every decision it makes
  • Adaptive, learning from outcomes over time
  • End-to-end, covering the full alert lifecycle
  • Controllable, with adjustable levels of autonomy

This blueprint for the AI SOC is laid out clearly in the research findings and reflects a fundamental shift in how AI is expected to function within it.

The security industry has spent the last several years racing to embed AI into every corner of the SOC. That tinkering or adoption phase is over. The next phase will make that intelligence scalable, usable, and trustworthy for the enterprise.

Enterprises demand AI that:

  • Shows its reasoning (transparency)
  • Operates within clear boundaries (control, guardrails)
  • Augments the SOC (capacity, throughput, efficiency)

Organizations that close these gaps, moving from fragmented tools to a unified AI SOC platform, from opaque outputs to transparent reasoning, and from brittle automation to adjustable autonomy, will unlock the outcomes that AI was always expected to deliver. Faster response. Lower risk. Higher analyst productivity.

The rest will continue to manage complexity, just with smarter tools. Smarter tools are only valuable when they make the system itself — in this case, the SOC — smarter.

That’s what SOC analysts actually want.

SEE TORQ IN ACTION

Ready to automate everything?

“Torq takes the vision that’s in your head and actually puts it on paper and into practice.”

Corey Kaemming, Senior Director of InfoSec

“Torq offers unprecedented protection and drives extraordinary efficiency for RSM and our customers.”

Todd Willoughby, Director

Compuquip logo in white

“Torq saves hundreds of hours a month on analysis. Alert fatigue is a thing of the past.”

Phillip Tarrant, SOC Technical Manager

Fiverr logo in black

“The only limit Torq has is people’s imaginations.”

Gai Hanochi, VP Business Technologies

Carvana logo in black

“Torq Agentic AI now handles 100% of Carvana’s Tier-1 security alerts.”

Dina Mathers, CISO

Riskified logo in white

“Torq has transformed efficiency for all five of my security teams and enabled them to focus on much more high-value strategic work.”

Yossi Yeshua, CISO

How Torq Reduces Mean Time to Contain

Contents

Get a Personalized Demo

See how Torq harnesses AI in your SOC to investigate, prioritize, and respond to threats faster.

Request a Demo

TL;DR

  • Mean Time to Contain (MTTC) measures how quickly your SOC stops a threat from spreading after detection, making it one of the most consequential metrics in incident response.
  • MTTC sits between MTTD (Mean Time to Detect) and MTTR (Mean Time to Respond/Resolve), placing it at the critical middle phase where active threat damage is limited or stopped.
  • Slow alert triage, manual workflows, and fragmented tooling are the top factors that inflate MTTC in enterprise SOCs.
  • The Torq AI SOC Platform automates triage, investigation, and containment actions, compressing what once took hours into minutes.
  • SOC teams that embed automation into their containment workflows see measurable improvements in MTTC, analyst capacity, and overall security posture.

When a threat lands inside your environment, detection is only half the battle. The real test is how fast your SOC moves from “we know something’s wrong” to “the threat is contained.” That window is the Mean Time to Contain (MTTC), where breaches either grow or stop growing.

For enterprise SOC directors, MTTC has become one of the most telling indicators of operational maturity. A team with a fast MTTC is one where automation is doing the heavy lifting, playbooks are consistent, and analysts are focused on decisions rather than manual tasks.

This article breaks down what MTTC is, how it relates to other key incident response metrics, what inflates it, and how the Torq AI SOC Platform helps security teams drive it down, measurably and at scale.

What Is Mean Time to Contain (MTTC)?

Mean Time to Contain (MTTC) is an incident response metric that measures the average time elapsed between the detection of a security incident and the moment it is successfully contained, meaning the threat is neutralized or isolated and prevented from spreading.

A lower MTTC signals a more efficient SOC: one that acts quickly, limits blast radius, and prevents secondary damage from a spreading threat. A higher MTTC exposes the organization to escalating risk with every passing minute.

MTTC vs. MTTD vs. MTTR

These three metrics are often grouped together, and for good reason. They map the full arc of an incident response lifecycle, each measuring a distinct phase:

  • MTTD (Mean Time to Detect): How long it takes to identify that an incident is occurring. This phase is largely determined by your detection tooling and monitoring coverage.
  • MTTC (Mean Time to Contain): How long it takes to stop the threat from spreading after it has been detected. This is the active response phase, where containment actions — such as isolating a host, blocking a user, or revoking credentials — occur.
  • MTTR (Mean Time to Respond/Resolve): How long it takes to fully resolve the incident and return systems to normal operation. MTTR is the broadest metric and includes containment plus remediation and recovery.

Think of them as a sequence: detect, contain, resolve. MTTC lives in the middle, and it’s often the phase where the most damage happens or is prevented. You can read more about MTTD vs. MTTR and why they matter on the Torq blog.

Why MTTC Matters

Every minute a threat remains uncontained, the scope of the incident grows: more systems exposed, more data at risk, more analyst time consumed. MTTC gives SOC leaders a direct, measurable lens into both their response workflow effectiveness and their detection capabilities. Organizations that benchmark and actively work to reduce MTTC gain a concrete operational advantage. Faster containment means smaller incidents, lower remediation costs, and a stronger overall security posture.

Key Incident Response Metrics SOCs Should Track

MTTC is one piece of a larger picture. The most operationally mature SOCs track a suite of incident response metrics that together tell the full story of detection-to-resolution performance. Here are the five every SOC director should have on their dashboard:

1. Mean Time to Detect (MTTD): MTTD measures the gap between when a threat enters the environment and when the SOC recognizes it. Improving MTTD largely depends on detection tooling — SIEM, EDR, XDR — and how well those tools surface actionable signals from noise.

2. Mean Time to Contain (MTTC): MTTC measures the active response phase, from detection to containment. This is where automation has the most immediate impact, as containment actions are often repeatable and logic-driven.

3. Mean Time to Respond / Resolve (MTTR): MTTR captures the total time from incident detection through full resolution and recovery. It’s the broadest metric and reflects the combined efficiency of your detection, containment, and remediation processes. For a deeper dive, see 3 Ways Torq Reduces MTTR with AI and Automation.

4. Mean Time to Acknowledge (MTTA): MTTA measures how long it takes an analyst to acknowledge an alert after it fires. High MTTA often signals alert fatigue or understaffed triage queues, both of which automation directly addresses.

5. Time to Detect (TTD): TTD focuses on per-incident detection timing rather than averages, giving teams granular visibility into outlier incidents that pull the mean upward.

Together, these metrics inform SOC decision-making at every level: where to invest in tooling, where automation provides the highest ROI, and how to benchmark operational improvement over time. For a broader view of how triage quality affects each of these numbers, the Torq incident triage checklist is a strong reference.

How These Metrics Relate: A Quick Reference

MetricWhat It MeasuresPhase
MTTDTime from threat entry to detectionDetection
MTTCTime from detection to containmentActive Response
MTTRTime from detection to full resolutionFull Lifecycle
MTTATime from alert fire to analyst acknowledgmentTriage
TTDPer-incident detection timeDetection

Top Factors That Inflate Mean Time to Contain

Understanding what drives MTTC up is the first step toward driving it down. These are the five most common contributors in enterprise SOCs:

1. Slow alert triage. When analysts spend significant time manually reviewing and prioritizing alerts, the window between detection and containment stretches. High-volume alert environments, where hundreds or thousands of alerts fire daily, make manual triage a bottleneck by design. Automating triage so that critical alerts surface immediately and low-priority noise is handled automatically is one of the highest-leverage MTTC improvements a SOC can make. 

2. Manual, undocumented workflows. When containment actions depend on individual analyst knowledge rather than documented, automated playbooks, response consistency drops, and speed suffers. Different analysts take different steps; some steps get missed under pressure, and institutional knowledge is lost over time. Standardized, automated workflows remove that variability and give every analyst the same reliable path forward.

3. Fragmented tooling. Enterprise SOCs often operate with dozens of security tools that each require separate logins, dashboards, and manual handoffs. When an analyst pivots between an EDR console, a SIEM dashboard, a ticketing system, and a communication platform to execute a single containment action, that context-switching adds measurable time to every incident. Orchestration that stitches those tools into unified, automated workflows eliminates that friction entirely.

4. Unclear escalation paths. When ownership of an incident is ambiguous or escalation timing is left to individual judgment, containment stalls while teams sort out who acts next. Well-defined escalation criteria, built into automated workflows, keep incidents moving at the right velocity with clear accountability at every step.

5. Insufficient context at the point of action. Analysts who need to hunt for context — pulling logs, querying threat intel feeds, checking asset inventories — before making a containment decision add latency to every response. Automated enrichment that surfaces context when an alert fires gives analysts everything they need to act immediately. Explore how automated SOC incident response enables this.

How Torq Optimizes MTTC Through Automation

The Torq AI SOC Platform is purpose-built to compress Mean Time to Contain by automating the detection-to-containment pipeline, from the moment an alert fires to the moment the threat is neutralized.

Here’s how Torq’s capabilities map directly to MTTC reduction:

Automated Triage at Machine Speed

Torq’s Auto Triage capability automatically processes incoming alerts, applying contextual enrichment, severity scoring, and routing logic without analyst intervention. Alerts that would otherwise sit in a queue are triaged in seconds. Analysts receive prioritized, enriched cases — ready for decision-making — so they make containment decisions faster and with greater confidence.

The Torq AI SOC Platform automates up to 95% of Tier 1 triage tasks, resulting in a shorter gap between detection and the first containment action.

Agentic SOC Orchestration

Torq Socrates™, Torq’s agentic SOC orchestrator, operates as an intelligent layer that investigates, reasons, and acts across the full incident response workflow. Socrates works continuously — enriching cases, correlating signals, and executing or recommending containment actions in real time.

Socrates accelerates incident response by handling the repeatable, logic-driven steps autonomously and surfacing only the decisions that require human judgment.

Orchestrated Containment Across Your Entire Stack

Torq Hyperautomation™ connects your full security stack — EDR, SIEM, identity providers, cloud environments, ticketing systems — into unified, automated response workflows. When a containment action is needed, Torq executes it across every relevant tool simultaneously.

Isolating an endpoint, revoking a user session, blocking a malicious IP, and updating a ticket all occur as part of a single automated workflow that executes in parallel across your entire environment. That compression is where the most dramatic MTTC gains happen.

Multi-Agent Response at Scale

Torq HyperAgents™ is Torq’s multi-agent system that deploys specialized AI Agents across triage, investigation, and response functions simultaneously. HyperAgents operate in parallel, with multiple agents handling different aspects of an incident concurrently, with full coordination and auditability.

For complex, multi-vector incidents where containment requires action across several systems at once, HyperAgents delivers a speed and scale advantage that goes well beyond what manual workflows achieve.

Case Management That Keeps Containment on Track

Torq’s Case Management capability provides analysts with full visibility into incident status, containment actions, and outstanding response steps, all in a single interface. With everything centralized, tracked, and actionable from one place, analysts stay focused on the work that moves the incident forward.

For enterprise SOC directors, this also means full auditability: every containment action is logged, timestamped, and attributed, making post-incident review and compliance reporting straightforward.

Real-World Impact

Torq customers report meaningful MTTC and MTTR reductions after deploying the platform. Valvoline, for example, saves seven analyst hours per day through Torq’s automation — time previously consumed by manual triage and response tasks. That capacity recovery means analysts can focus fully on active incidents, accelerating containment when it matters most.

5 Best Practices for Reducing MTTC in Your SOC

Reducing Mean Time to Contain takes the right combination of process discipline and automation investment. These five practices deliver the biggest results:

1. Automate Tier 1 Triage Completely 

Manual Tier 1 triage is the single largest MTTC bottleneck in most enterprise SOCs. Automating alert enrichment, severity scoring, and routing eliminates the queue-based delays that push MTTC up. Start by identifying the alert categories that consume the most analyst time with the least decision variability — those are your highest-ROI automation targets. 

2. Standardize Containment Playbooks 

Every common incident type — phishing, credential compromise, ransomware, malware execution — deserves a documented, automated containment playbook. Standardized playbooks give every analyst the same reliable path forward and eliminate the hesitation and variability that inflate MTTC under pressure. Treat your incident response plan as a living document that improves with every post-incident review.

3. Integrate Your Tools into Unified Workflows 

Fragmented tooling is a direct multiplier on MTTC. Every manual handoff between systems adds latency. Invest in orchestration that connects your security stack so containment actions execute across all relevant tools from a single workflow trigger. For a look at what high-performing security automation workflows look like in 2026, see Torq’s roundup of security automation workflow tools.

4. Define and Automate Escalation Criteria 

Build escalation logic into your automated workflows so incidents route to the right analyst or team based on severity, asset criticality, and threat type. Fast, consistent escalation keeps high-severity incidents moving at the right velocity with clear ownership at every stage.

5. Measure, Benchmark, and Iterate 

MTTC improvement is a continuous process. Establish baseline measurements, set targets, and review performance after every significant incident. Use that data to identify which incident types or workflow stages still carry the most latency and prioritize automation investments accordingly. Teams that treat MTTC as an active KPI see the fastest, most sustained improvement.

Faster Containment Starts with the Right AI SOC Platform

Mean Time to Contain is one of the clearest, most consequential measures of SOC effectiveness. It sits at the center of the incident response lifecycle, the phase where active threat damage is either limited or allowed to grow, and it reflects directly on how well your team’s processes, tooling, and automation work together.

The AI SOCs that consistently achieve strong MTTC numbers share a common thread: they’ve automated the repeatable, logic-driven work of triage and containment so their analysts focus on the decisions that require human expertise. The Torq AI SOC Platform is built for that outcome. From automated triage and agentic orchestration with Socrates to Hyperautomation-powered response workflows and multi-agent execution with HyperAgents, Torq compresses every phase of the detection-to-containment pipeline, giving enterprise SOCs a measurable edge where it matters most.

But not every platform that claims AI SOC delivers the automation depth your containment workflows actually need. The AI SOC market is crowded with vendors making big promises. 

Are you ready to cut through the noise and find out what a real AI SOC looks like — one built to help your team contain faster, respond smarter, and prevent breaches before they spread?

FAQs

What is Mean Time to Contain (MTTC) in cybersecurity?

Mean Time to Contain (MTTC) is a security operations metric that measures the average time between the detection of a security incident and the successful containment of that threat, meaning it has been isolated and stopped from causing additional damage. SOC teams track MTTC to evaluate the speed and efficiency of their active response workflows. A lower MTTC reflects stronger containment capabilities, tighter playbooks, and higher levels of automation. Learn more about MTTC and related incident response metrics.

How does MTTC differ from MTTR?

MTTC and MTTR (Mean Time to Respond/Resolve) measure different phases of incident response. MTTC captures the time from detection to containment, stopping the threat from spreading. MTTR captures the full lifecycle from detection through complete resolution and recovery, including containment and remediation, root cause analysis, and system restoration. MTTC is a subset of MTTR, and improving MTTC is one of the most effective ways to pull MTTR down. See MTTD vs. MTTR: Definition, Differences, & Why They Matter for a full breakdown.

What is a good MTTC benchmark?

MTTC benchmarks vary by industry, organization size, and threat type, but the general target for high-performing enterprise SOCs is to contain high-severity incidents within 1 hour of detection. Many organizations with mature security automation capabilities achieve containment in minutes for common, repeatable incident types. Teams actively benchmarking their MTTC typically use those measurements to prioritize automation investments where latency is highest.

What are the most important incident response metrics to track alongside MTTC?

The core incident response metric set most SOC directors track includes MTTD (Mean Time to Detect), MTTC (Mean Time to Contain), MTTR (Mean Time to Respond/Resolve), and MTTA (Mean Time to Acknowledge). Together, these metrics map the full detection-to-resolution lifecycle and highlight the most meaningful efficiency gains. For a full explanation of each, visit MTTD vs. MTTR: Definition, Differences, & Why They Matter.

How does automation reduce Mean Time to Contain?

Automation reduces MTTC by eliminating manual triage delays through enriching and routing alerts at machine speed, executing containment actions automatically and simultaneously across multiple tools, and removing the context-switching and handoff latency that slows manual response. The Torq AI SOC Platform automates the full detection-to-containment pipeline, enabling SOCs to contain threats in minutes. Learn more about automated SOC incident response.

How do I measure MTTC effectively in my SOC?

Measuring MTTC accurately requires consistent timestamp logging across your incident response workflow, specifically a detection timestamp and a containment timestamp. The average of those deltas across incidents gives you your MTTC. From there, segmenting MTTC by incident type, severity, and responsible team provides the granular visibility needed to identify where automation investments will have the greatest impact. Torq’s Case Management provides the centralized tracking and auditability needed to measure MTTC consistently at enterprise scale.

What role does an AI SOC platform play in reducing MTTC?

An AI SOC platform reduces MTTC by automating the most time-consuming phases of the detection-to-containment workflow. Agentic AI continuously investigates, enriches, and acts on incoming signals, while Hyperautomation simultaneously executes containment actions across the full security stack. The result is a dramatic compression of the time between when a threat is detected and when it’s stopped. The Torq AI SOC Platform is purpose-built for this outcome, combining agentic orchestration, multi-agent execution, and end-to-end automation to give enterprise SOCs measurably faster containment at scale.

SEE TORQ IN ACTION

Ready to automate everything?

“Torq takes the vision that’s in your head and actually puts it on paper and into practice.”

Corey Kaemming, Senior Director of InfoSec

“Torq offers unprecedented protection and drives extraordinary efficiency for RSM and our customers.”

Todd Willoughby, Director

Compuquip logo in white

“Torq saves hundreds of hours a month on analysis. Alert fatigue is a thing of the past.”

Phillip Tarrant, SOC Technical Manager

Fiverr logo in black

“The only limit Torq has is people’s imaginations.”

Gai Hanochi, VP Business Technologies

Carvana logo in black

“Torq Agentic AI now handles 100% of Carvana’s Tier-1 security alerts.”

Dina Mathers, CISO

Riskified logo in white

“Torq has transformed efficiency for all five of my security teams and enabled them to focus on much more high-value strategic work.”

Yossi Yeshua, CISO